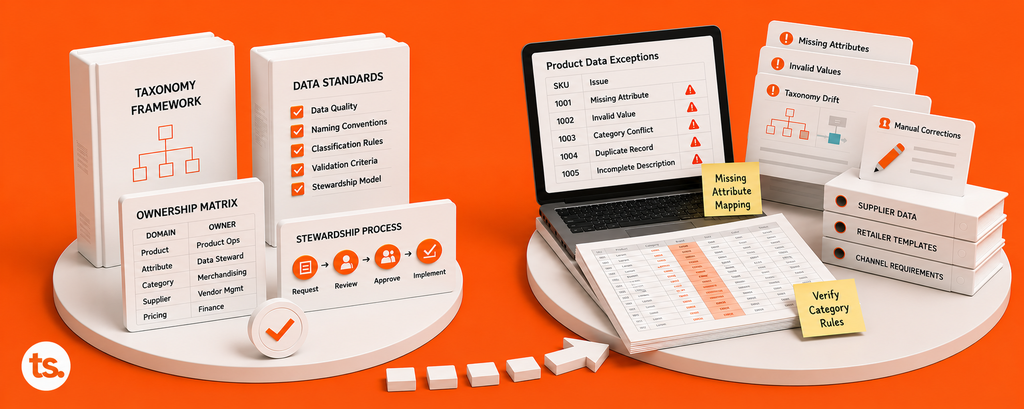
Most companies think they have solved data ownership the moment a title exists for it. Someone becomes “the data owner,” a line goes on an org chart, and the conversation moves on.
Picture a mid-size consumer goods company where a product recall requires updated compliance and safety data to reach the customer-facing record within twenty-four hours. The named Data Owner sits with the VP of Merchandising. Updating that record depends on three other teams, none of whom report to that VP, and none of whom are measured on how fast the handoff happens. The record updates five days later. The org chart says someone owns this. In the moment it mattered, nobody actually did.
In brief
Naming a data owner does not guarantee that ownership survives the moment data crosses from one department to another
The strongest governance models tie ownership to a functional domain that spans departments, not to a single centralized title
Deloitte found organizations with a Chief Digital Officer as primary owner achieved 88% of expected program value, compared with 59% under a more centralized CIO-led model
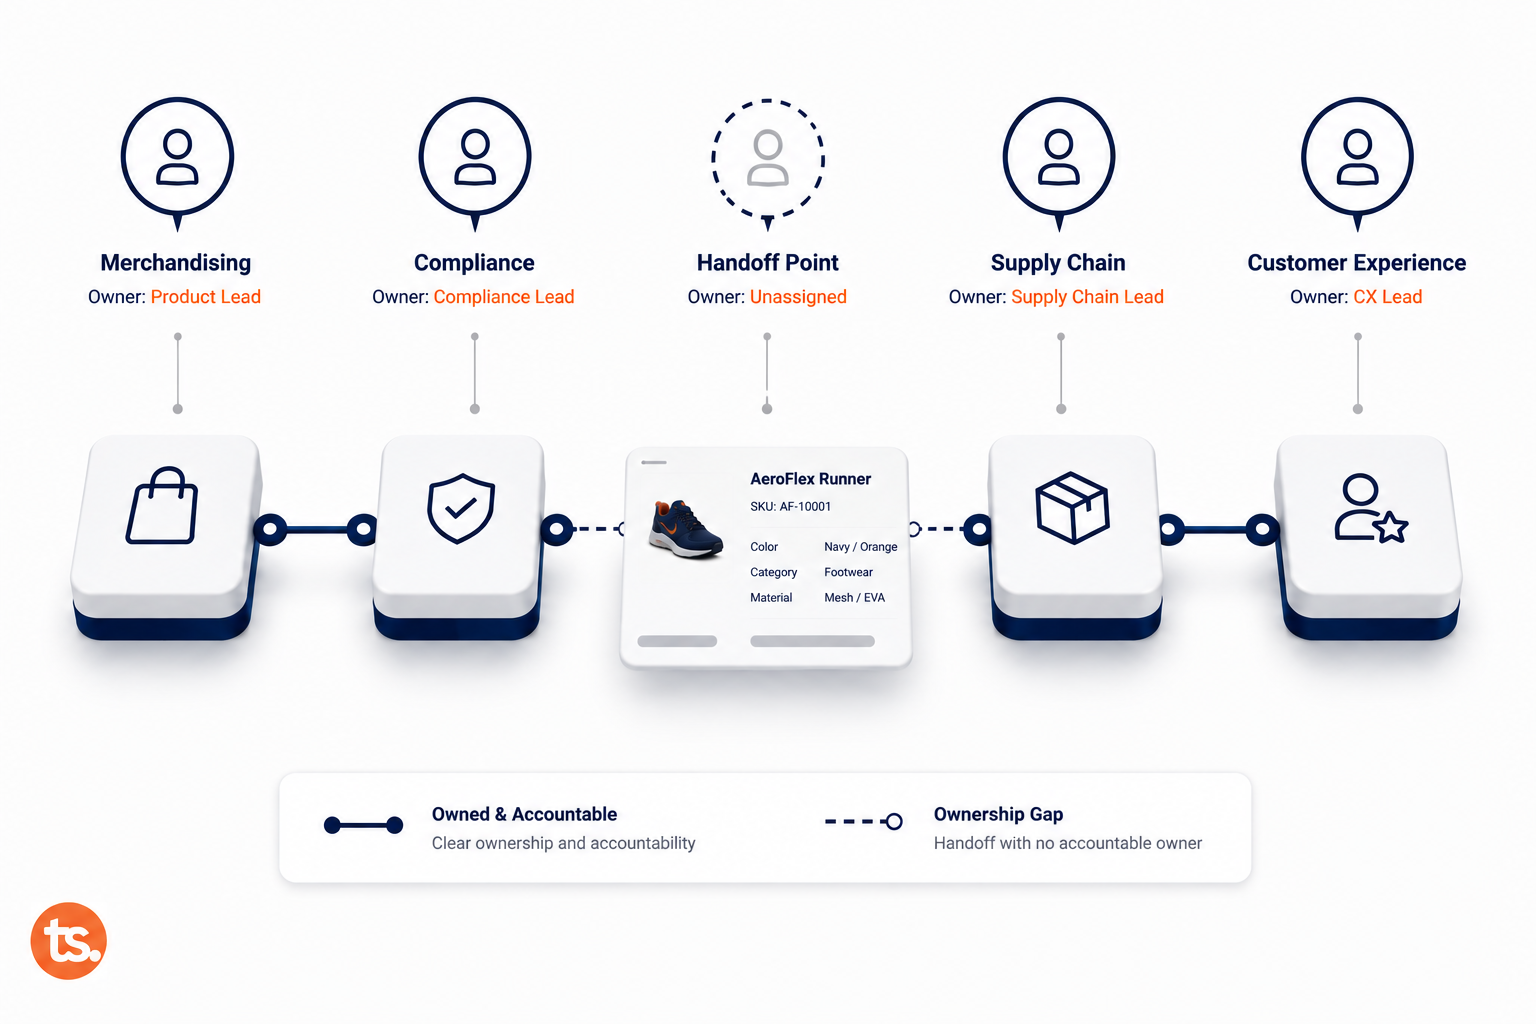
Fixing this rarely requires a reorganization. It requires naming who owns each specific handoff point, not just who owns the category of data
Cross-functional data ownership means accountability for a data domain, structured to follow the data across the departments it actually touches, rather than sitting with a single role disconnected from those departments.
What “Having a Data Owner” Actually Looks Like Today
What does it mean to have a data owner? In most organizations, it means a single title, usually senior, has been assigned formal responsibility for a category of data. It rarely means that role has operational authority over the teams whose actions actually determine whether that data stays accurate.
That gap between formal title and operational reach is not a rare misconfiguration. It is the default setup in most enterprises, since ownership usually gets assigned during a governance initiative, a single meeting, a single sign-off, rather than being built into the actual workflows where departments hand data to one another.
Why This Gap Persists Even After Governance Programs Launch
A governance program can produce a policy document, a RACI chart, and a named owner in a matter of weeks. What it cannot produce in that same window is a change to how Compliance, Supply Chain, and Marketing actually work together day to day. The policy exists on paper before the operational relationship exists in practice, and the gap between the two rarely closes on its own.
Why Ownership Assigned to a Role Doesn’t Survive a Handoff
Why does data ownership fail even when someone is formally accountable? Ownership assigned to a role fails at the handoff because the owner has authority over their own team’s work, not over the work of the other departments the data has to pass through to stay accurate.
A title gives someone the right to be asked questions. It does not give them the right to change how another department prioritizes its own work.
The Handoff Is Where Accountability Actually Lives
Data rarely breaks inside a single department. It breaks in the space between two departments, where one team finishes its part and assumes the next team will pick it up correctly, without anyone confirming that assumption is true. That space, the handoff itself, is exactly where most ownership models have nothing to say.
A title answers who is accountable. It never answers who acts first when two departments disagree about whose job it is.
Where Data Ownership Actually Breaks Down
Where does data ownership typically fail inside an organization? It fails most often at three specific points: where merchandising or product teams hand data to compliance, where supply chain systems feed customer-facing records, and where marketing content depends on data neither team owns outright.
Handoff Point
What Typically Breaks
Merchandising to Compliance
A product change ships before the compliance-relevant fields are confirmed updated
Supply Chain to Customer-Facing Record
Inventory or sourcing changes reach internal systems before they reach the public record
Marketing to Regulatory
Campaign content references product claims neither team has final authority to verify
Merchandising to Compliance
A product update moves fast because merchandising is measured on speed to market. Compliance is measured on accuracy. Neither team is measured on how quickly the two connect, so the connection is the first thing that slips.
Supply Chain to Customer-Facing Record
Supply chain systems update the moment a sourcing or inventory change happens internally. The public-facing record updates only when someone remembers to push that change forward, and remembering is not a system, it is a hope.
Marketing to Regulatory
Campaign content often references product claims that live in a completely different system than the one marketing actually edits, creating a gap between what marketing believes is true and what the record confirms is true.
McKinsey’s own analysis of enterprise data governance describes a retailer that solved this differently. Rather than assigning ownership by data category, it assigned ownership by domain, giving specific executives accountability for data domains that explicitly spanned multiple functions, so the product owner driving checkout improvements also owned the sales and payment domains outright, not just the parts that touched their own team.
The handoff does not fail because nobody is responsible. It fails because two people are responsible for two different halves of the same problem.
What Works Instead: Ownership Built Into the Handoff
Everything so far explains why ownership assigned to a title fails. What follows is what actually holds up in its place.
What does effective cross-functional data ownership look like in practice? It looks like ownership tied to a domain that explicitly includes the handoff points, not just the data itself, with a single accountable person at each point of transfer, not a single accountable person for the category as a whole.
Deloitte’s 2025 research on digital operating models found that organizations with a Chief Digital Officer as the primary owner of digital initiatives achieved an average of 88% of expected program value, compared with 69% under a Chief Technology Officer and only 59% under a Chief Information Officer. The same research found that matrixed structures, where a central team supports individual business units while those units retain real autonomy, consistently outperformed centralized, single-decision-body models.
Assign Ownership at the Domain, Not the Category
A domain includes every department the data actually touches. Ownership of “product data” in the abstract solves nothing. Ownership of the specific domain spanning merchandising, compliance, and the customer-facing record gives one person authority across the exact handoff that keeps breaking.
Name Who Acts First at Each Handoff
Every handoff needs a single person whose job is to notice when the transfer has not happened, not just a person who is accountable after the fact. That is a different role than a data owner. It is closer to an operational trigger than a title.
Build the Handoff Into the Workflow, Not the Policy
A policy document describes what should happen. A workflow makes it happen automatically, or at minimum, makes its absence immediately visible. The organizations Deloitte and McKinsey both describe succeeded because they changed the mechanism, not just the org chart.
Ownership that lives only in a policy document is a title. Ownership built into the workflow is a mechanism, and mechanisms are what survive a busy quarter.
Is Your Data Ownership Structural or Just a Title? A Quick Self-Assessment
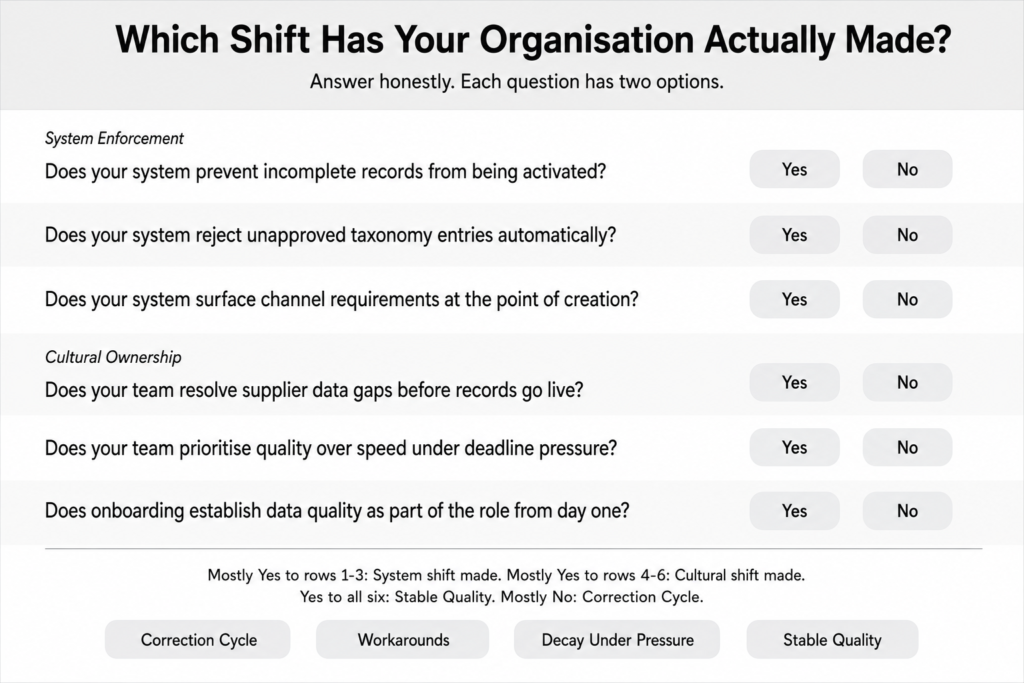
The difference between a title and a working structure is only visible when you look for it directly. Six honest questions make that concrete.
Ownership and Authority
Does your named data owner have any authority over the teams the data actually passes through?
If two departments disagreed about whose job a data update was, would there be a clear, immediate answer?
Is anyone specifically accountable for the handoff itself, separate from the data category as a whole?
Structure and Visibility
Would a missed handoff be visible automatically, or only after something downstream goes wrong?
Is your ownership model closer to centralized, one final decision-maker, or matrixed, shared but clearly assigned?
Could you name, right now, the exact three or four handoff points where your own organization’s data is most likely to break?
Outcome guide: Three or more “no” answers means your data ownership currently exists as a title rather than a working structure, and the handoffs beneath it are very likely unmanaged.
Where This Leaves You
Most organizations discover this gap the same way, not through an audit, but through a moment where the record was wrong at exactly the wrong time, and the person with “owner” in their title had no way to have caught it.
Naming an owner is not the mistake. Stopping there is. A title without operational reach is a name on a chart. A domain that includes the handoff, with someone accountable for the transfer itself, is a structure that actually holds when a real deadline hits it.
That is the exact gap ThoughtSpark’s Data Governance and Data Readiness Hub work is built to close, for teams that would rather find their weakest handoff on their own schedule than have a recall, an audit, or a customer find it first.
Key Takeaways
McKinsey’s analysis of enterprise data governance found that assigning ownership by domain, spanning the departments data actually touches, outperforms assigning ownership by data category alone
Deloitte found organizations with a Chief Digital Officer as primary digital owner achieved 88% of expected program value, compared with 59% under a more centralized CIO-led model
Matrixed ownership structures, which pair central support with real business-unit autonomy, consistently outperform centralized, single-decision-body models
Most data failures happen at the handoff between departments, not inside any single department’s own work
Fixing this requires naming who acts first at each specific handoff point, not just who owns the data category overall
Most companies think of AI readiness the way they think of a home inspection. Pass it once, and you’re done.
This is not how it works. Picture a mid-size distributor whose product data passed an AI-readiness check at the start of the year. Attributes complete, identifiers standardized, feeds clean. By the third quarter, its products had quietly stopped surfacing in agent-driven procurement comparisons, and nobody could say exactly when it started.
This happens more often than most product data teams realize. Across enterprise product data programs, the pattern is consistent: teams pass the readiness test once, then stop asking whether they would still pass it today.
In brief
AI agents evaluate product data continuously, not once, which is why passing a readiness check today doesn’t guarantee passing the next one
Structuring a catalog is necessary, but only ever the starting point
Lasting readiness needs an owner, a checking cadence, and a feedback loop
AI-ready product data means product information structured, complete, and consistent enough for an AI agent to verify a claim with certainty, rather than interpret or infer it the way a human buyer would. An AI agent, in this context, is software that independently searches, compares, and evaluates product data on a buyer’s behalf, with or without a human confirming the final decision.
What Makes Product Data AI-Ready?
What is AI-ready product data? AI-ready product data is product information that is structured, complete, and consistent enough for an AI agent to verify a claim with certainty, rather than interpret it the way a human would. This distinction, verification versus interpretation, determines whether a product stays visible in agent-driven discovery and comparison.
A human buyer forgives a lot. A vague spec, a missing dimension, a description leaning on brand feeling instead of fact. People fill the gap with trust, patience, or enough goodwill to click through anyway.
An AI agent evaluating that same product on someone else’s behalf works differently. It carries no brand loyalty and no reason to guess in your favor.
Human Buyer
AI Agent
Handles ambiguity
Fills gaps with trust and intuition
Requires explicit, structured certainty
Response to missing data
Clicks through anyway
Excludes the product from consideration
Brand loyalty
Can outweigh a data gap
Carries no influence on the evaluation
Evaluation frequency
Once, at the moment of purchase
Continuously, on every query
This applies well beyond retail. Whether your product data lives in a PIM, an MDM hub, or an ERP-fed catalog, structured product data now shapes agentic commerce across grocery, industrial distribution, healthcare, and automotive aftermarket sourcing, anywhere a buyer, human or agent, needs to compare, verify, and decide.
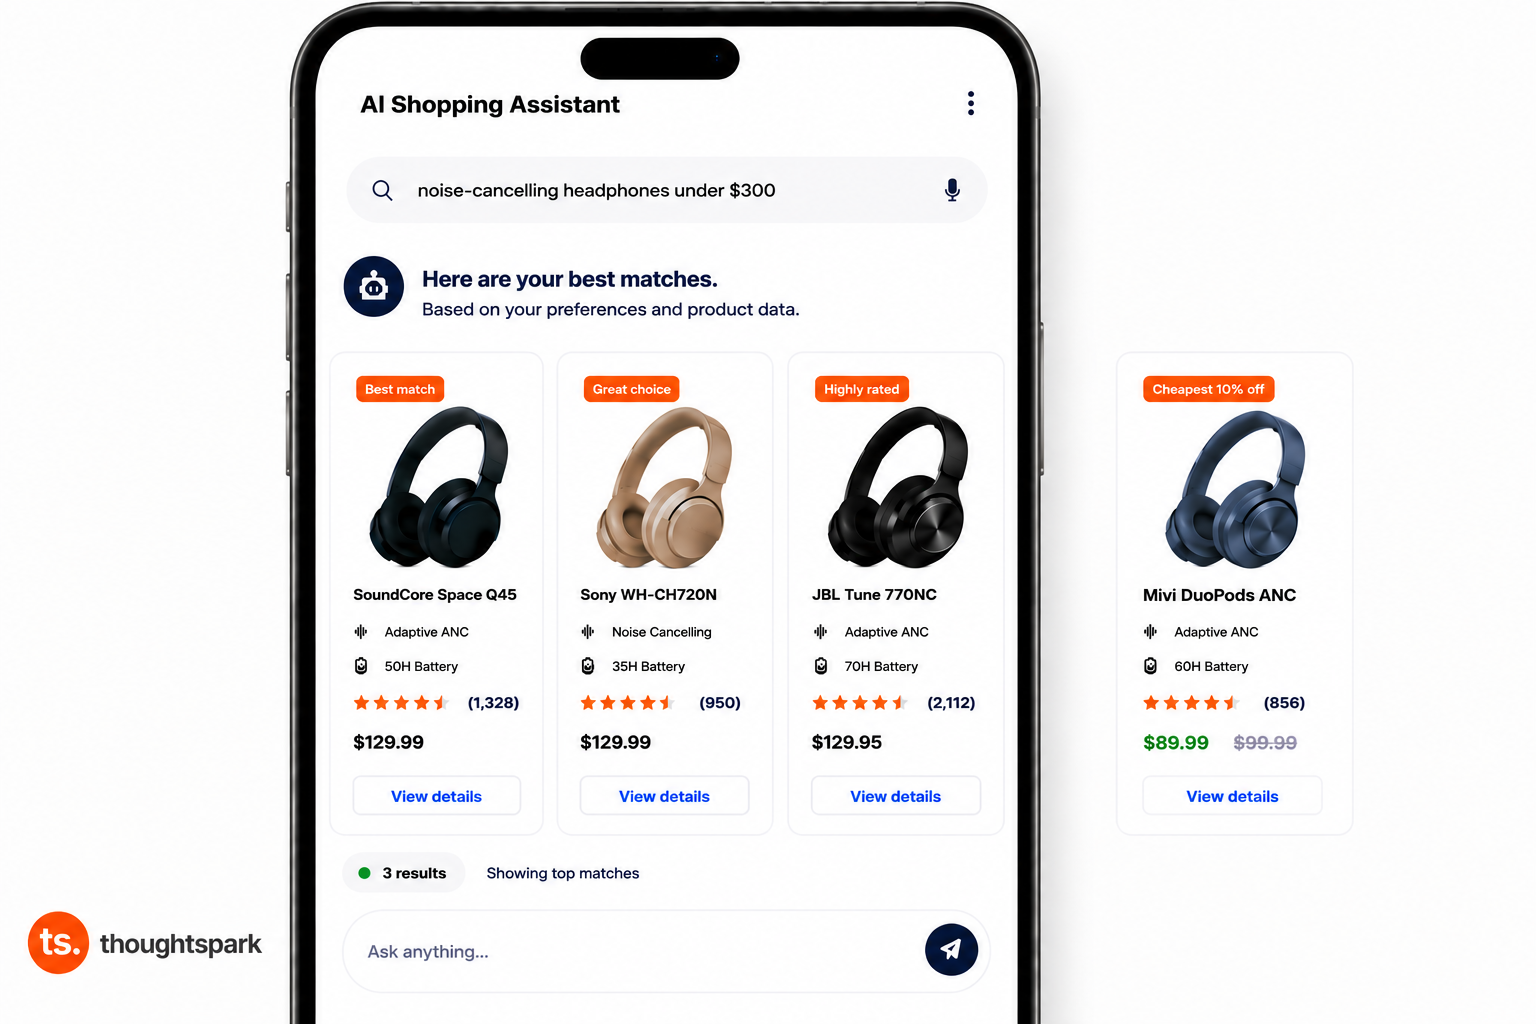
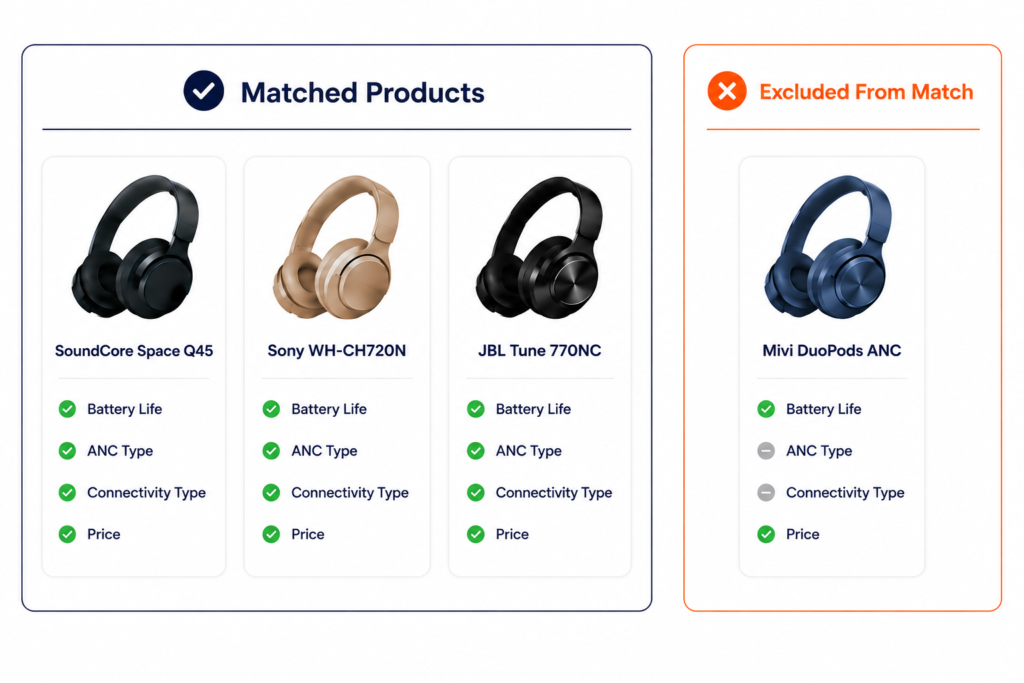
Here is what that gap looks like in practice, when an AI assistant compares real products against a real search.
Same search, same four products. One excluded from the AI’s match count, not for its price or battery life, but for two data fields nobody filled in
Why This Matters at Scale, Not Just in Principle
The mechanism above is not theoretical. By 2028, Gartner predicts ninety percent of B2B buying will be AI agent intermediated, representing over fifteen trillion dollars in B2B spend moving through AI agent exchanges. That scale is why the difference between interpretation and verification stops being academic for any business selling into a B2B channel.
How AI Agents Actually Evaluate Product Data
How do AI agents evaluate product data? AI agents evaluate product data using three mechanics: structured attributes and schema, feed format and real-time synchronization, and cross-channel consistency. A product fails evaluation if any one of the three is incomplete, regardless of how strong the others are.
Real platforms are already doing this evaluation today. ChatGPT Shopping, Google’s expanding shopping surfaces, Perplexity’s shopping features, and Microsoft Copilot’s checkout integration all pull from structured product data to compare, recommend, and in some cases complete a purchase on the buyer’s behalf.
Forrester’s own 2026 analysis names this directly: building what the firm calls a machine advantage, a content strategy built on schema, comprehensive product information, and genuine topical depth, is what earns favor with the AI crawlers and agents now evaluating brands across both owned and non-owned channels.
Three mechanics determine whether a product clears that evaluation, on any of these platforms:
Mechanic
What It Requires
What Fails If It’s Missing
Structured attributes and schema
Dimensions, materials, certifications exist as labeled fields, tagged with Schema.org markup where applicable, not buried in description text
The agent cannot infer a fact that was never stated as data
Feed format and real-time sync
Pricing, availability, and specification reflect the current ERP or transactional system state, close to real time
A weekly feed against a daily-changing system creates a standing, catchable gap
Cross-channel consistency
The same product shows identical attributes, identifiers, and GTINs across every channel and syndication partner where it appears
Inconsistency reads to an agent as a trust signal, not a technicality
One recurring issue across enterprise catalogs: taxonomy inconsistency between internal PIM structures and external channel requirements. A product classified correctly in a PIM can still fail agent evaluation if the taxonomy mapping to a marketplace or GDSN feed introduces a mismatch downstream.
An agent cannot infer what a page does not state. If a fact is not structured, it does not exist to the agent evaluating it.
Why AI Readiness Fades After the Initial Fix
Why does AI readiness fade after a data cleanup project? AI readiness fades because agents re-evaluate catalogs continuously, while most organizations treat readiness as a project with a defined end date. Data that was accurate at project close can be inaccurate months later, with no alert triggered anywhere in the system.
Most guidance treats AI readiness as a structuring project:
Clean the attributes
Fill the missing fields
Standardize the identifiers
Close the project
Each of those steps genuinely matters, and skipping any of them would leave a catalog unreadable to an agent from day one. The part this checklist leaves out is what happens after the fix, once agents keep checking your master data and product records long after the project wrapped up and the team has moved on to the next priority.
Readiness Is a Condition That Has to Be Maintained
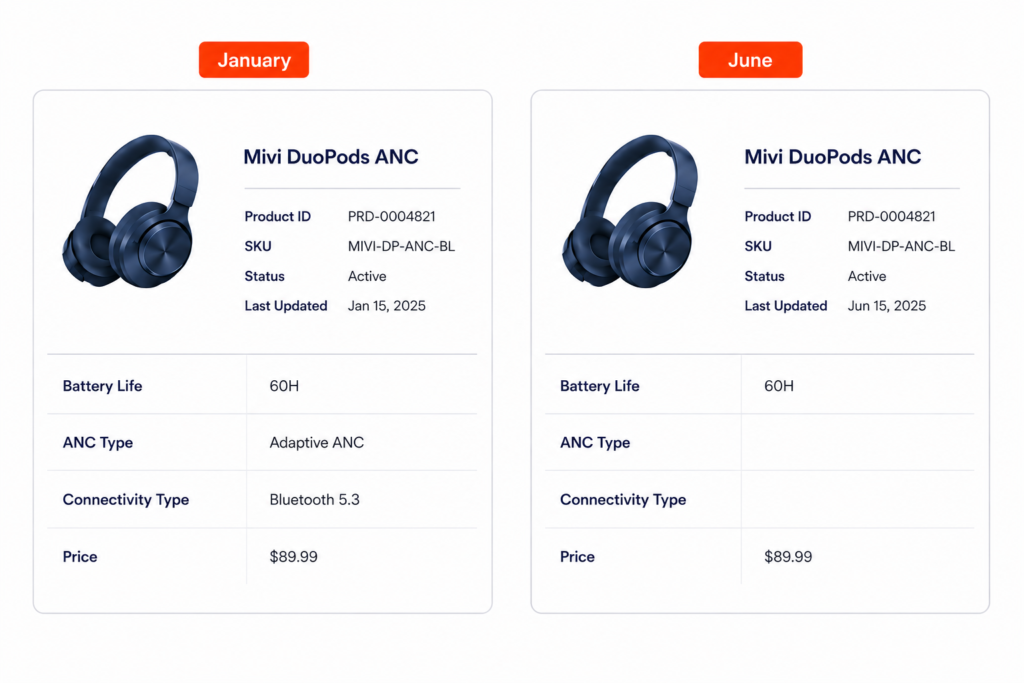
Agents evaluate your catalog fresh every time, against whatever the record says at that exact moment. That distributor’s data was accurate in January and stale by June. The process itself never changed. The underlying source data simply moved while the published record stood still.
Same listing. Same status: Active. Two fields quietly disappeared, and nothing in the system said so.
To an agent, the record is accurate or it is not. The space between what your data says and what is actually true is where visibility erodes, quietly, for months, before a pattern becomes visible to anyone on your team.
What Causes AI-Ready Product Data to Drift
What causes product data drift? Product data drift is caused by a small, repeatable set of upstream changes, most commonly supplier or specification updates, compliance shifts, pricing desynchronization between ERP and catalog systems, and expired seasonal attributes, none of which automatically propagate to the published product record.
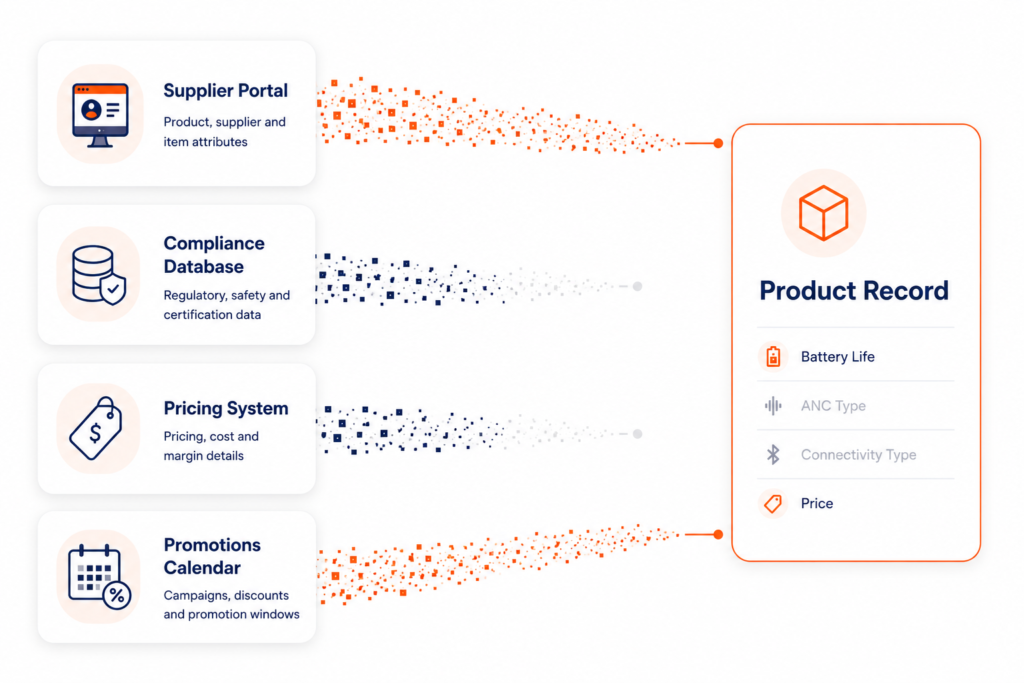
A supplier changes a component, a compliance requirement shifts, or a pricing feed slips out of sync. Each of these is where that erosion actually begins.
Two connections never stopped. Two quietly did. The record never knew the difference.
Each of these systems maps to one of the four causes below: what a system stops feeding is what quietly goes missing.
Supplier and Specification Changes
The published attribute stays exactly as it was, and an agent comparing that spec against a competitor’s accurate listing quietly ranks the outdated record lower or excludes it entirely.
Compliance and Regulatory Attribute Shifts
In regulated categories like healthcare or automotive parts, this single gap can be enough for an agent to exclude the product from consideration on trust grounds alone.
Pricing and Availability Sync Gaps
An agent comparing multiple sources for price accuracy treats that mismatch as a reliability signal worth investigating.
Seasonal and Promotional Attribute Expiration
Agents built to avoid recommending unavailable or mispriced products treat this the same way they would treat any other inaccurate field.
Organizations frequently discover that these four causes trace back to gaps in cross-functional ownership. The PIM, MDM, and ERP tools involved are rarely the actual point of failure. The handoffs between the teams responsible for each system are usually where things break down.
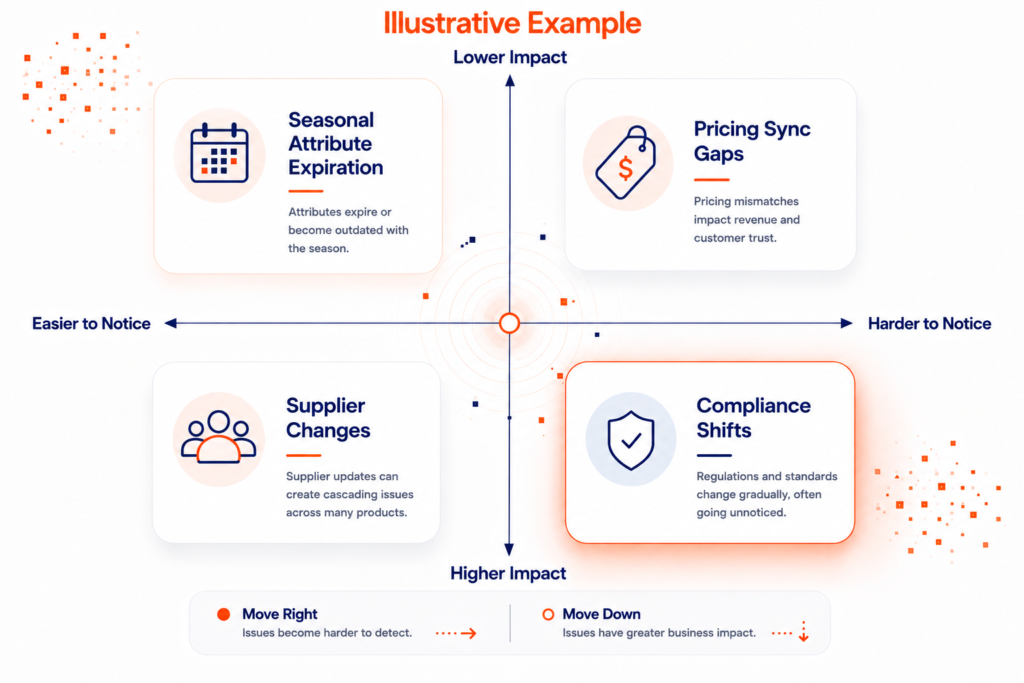
Every organization experiences these four causes differently, some are easy to notice and low-stakes, others are easy to miss and costly. The following shows how one team might plot them, though your own catalog will likely look different:
This is one example. Plot your own four causes based on your organization’s experience.
Whichever cause lands in the hardest quadrant for you, easy to miss and costly when missed, is usually the first place to build an owner and a feedback loop.
Every one of these failures hides in plain sight until an agent treats it as a disqualification.
The Ownership-Cadence-Feedback Framework
Everything so far explains why readiness fades. What follows is what actually stops it.
What does it take to maintain AI-ready product data? Maintaining AI readiness requires three organizational commitments: a named owner accountable after project close, a recurring cadence for checking readiness, and an automated feedback loop connecting source system changes to the published product record.
Preventing drift does not require a large technical investment. It requires three commitments, made in this order, each addressing a different point where readiness typically breaks down.
MIT Sloan Management Review argues that durable governance comes from embedding controls directly into workflows and decision rights, rather than layering periodic reviews on top of business as usual. Product data readiness follows the same logic, one level down, at the level of the catalog rather than the enterprise.
Assign Ownership That Outlives the Project
Someone stays accountable for catching drift after the initial cleanup ends, by name. Without a named owner past go-live, drift stops being a possibility and becomes the expected outcome.
Build a Recurring Readiness Cadence
Waiting for a sales dip to surface a data problem means the damage already happened before anyone noticed. A defined cadence, whether monthly or quarterly, gives the organization a rhythm for catching drift independent of whether a problem has already surfaced elsewhere.
Create a Feedback Loop From Source to Record
When a spec, price, or compliance attribute changes upstream in an ERP or supplier system, that update should reach the published product record automatically, through system integration rather than manual re-entry. Most drift starts exactly in this gap, between catalog operations and the systems feeding it.
The project that structures your data has a deadline. The agent that keeps checking it does not.
Most organizations do not build all three at once. That sequence maps directly onto four stages most organizations move through, whether they name them or not.
Stage
What It Looks Like
Structured
Data has been cleaned and organized once, typically as part of a defined project
Owned
A named individual is accountable for readiness beyond the original project
Monitored
A recurring cadence exists for checking readiness
Autonomous
Source-to-record updates flow automatically, closing the loop
Most organizations sit at Structured the moment a readiness project closes. Moving to Owned is the highest-leverage next step, since ownership is what makes a cadence and a feedback loop hold.
When to Reassess Product Data Readiness
When should you reassess AI readiness outside a regular schedule? Reassess immediately whenever a specific trigger event occurs, a new supplier, a compliance update, an ERP migration, a seasonal catalog refresh, or an unexplained shift in conversion, rather than waiting for the next scheduled review.
A recurring cadence catches drift that accumulates slowly, the kind that builds up over weeks without a single identifiable cause. Some drift arrives all at once, triggered by a specific event elsewhere in the business, and a calendar alone will not catch it in time.
Trigger Event
Why It Matters
New supplier or manufacturing change
Specifications may shift without downstream notification
Regulatory or compliance update
A compliance attribute can fall out of date instantly
Pricing or ERP system migration
Sync gaps are most likely during and immediately after migration
Seasonal catalog refresh or promotional cycle
Expired attributes are easy to overlook at scale
Unexplained shift in conversion or consideration
Often the first visible symptom of drift already in progress
Each of these is a moment where cost starts accumulating quietly, whether or not anyone is watching for it yet.
The moment a supplier changes a spec or a system migrates, drift already has a head start, whether or not anyone notices right away.
What Poor AI Readiness Actually Costs
What does poor AI readiness cost a business? The cost is not a single missed sale. It is compounding exclusion, since an agent that excludes a product once will exclude it again on every future query, until the underlying data is corrected.
That accumulation is not abstract. With B2B buying shifting this heavily toward agent intermediation, the cost of invisibility compounds fast.
How this shows up varies by industry, but the pattern repeats:
Grocery and distribution: products silently missing from automated procurement comparisons, quarter after quarter, with no single event marking when it started
Industrial manufacturing: a spec sheet mismatch quietly removing a part from consideration in every automated sourcing search run afterward
Healthcare and regulated categories: a lapsed compliance attribute excluding a product on trust grounds, even when the product itself remains fully compliant
Six months of any of these is six months of lost consideration that never shows up on a report, because nobody was checking while it was happening.
Fifteen products silently dropped from consideration this quarter cost exactly as much as fifteen products rejected at checkout. The first kind never generates a report.
That distributor from the opening eventually found its own gap, though not through a report. A channel partner asked why volume had quietly dropped, months after the actual cause had already passed.
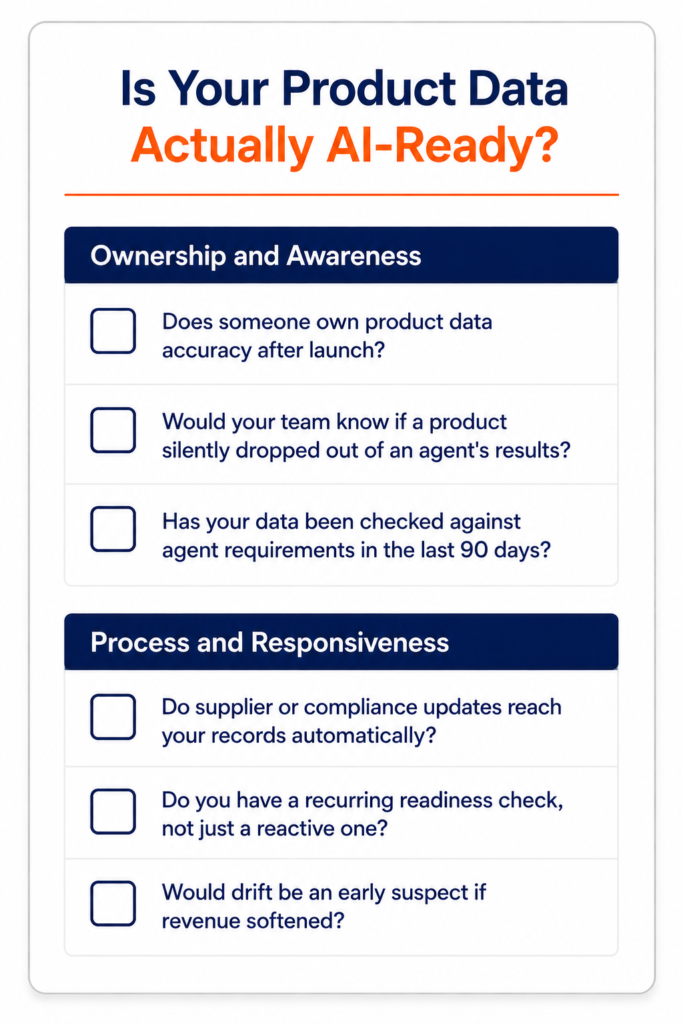
Is Your Product Data Actually AI-Ready? A Quick Self-Assessment
The problem, the framework, and the stakes are only useful if you can see where your own organization stands right now. Six honest questions make that concrete.
Six questions. No pre-filled answers. Where your organization stands is the part only you can check.
Ownership and Awareness
Does someone specifically own product data accuracy after launch or cleanup ends?
Would your team know today if a product had silently dropped out of an agent’s consideration set?
Has your product data been checked against current agent requirements in the last ninety days?
Process and Responsiveness
When a supplier or compliance detail changes, does that update reach your published record automatically?
Do you have a recurring cadence for checking readiness, separate from reacting to a known problem?
If revenue softened next quarter with no obvious cause, would data drift be an early place your team would look?
Outcome guide: Three or more “no” answers means readiness is currently a one-time event in your organization rather than an ongoing discipline, and drift is likely already underway somewhere in your catalog.
Where This Leaves You
Most organizations discover this gap eventually, usually after a partner or a customer notices before the data team does. The six questions above exist so that discovery happens on your terms.
What separates the organizations that catch drift early from the ones that find out the hard way is rarely technology. It is whether anyone owns readiness once the initial project ends. A framework without an owner stays a document. Add an owner but no cadence, and the response stays reactive instead of proactive. Add a cadence but no feedback loop, and the work never stops being manual.
Put those three together, and readiness stops being something you finish and becomes something you run. That is the operating model ThoughtSpark’s Data Readiness Hub and Data & AI Strategy work exists to help build, for teams that would rather close this gap on their own schedule than have an agent expose it first.
Key Takeaways
Gartner predicts ninety percent of B2B buying will be AI agent intermediated by 2028
Forrester identifies a machine advantage, a content strategy built on schema, comprehensive product information, and topical depth, as what earns favor with AI crawlers and agents
MIT Sloan Management Review links durable governance to embedding controls into workflows, not periodic review
Drift traces back to four specific causes: supplier changes, compliance shifts, pricing sync gaps, and seasonal attribute expiration
Poor data quality broadly costs organizations millions annually, a cost that compounds as agent-driven evaluation scales
Three commitments, a named owner, a recurring cadence, and a feedback loop from source to record, separate organizations that stay visible from ones that drift unnoticed
Every organization assessing data readiness for an AI initiative starts in the same place: the quality dashboard, the governance audit, the completeness report. These tools were built to answer one question: does the data meet the standards the current system requires?
Knowing the answer matters, and for an AI initiative, it is only the starting point.
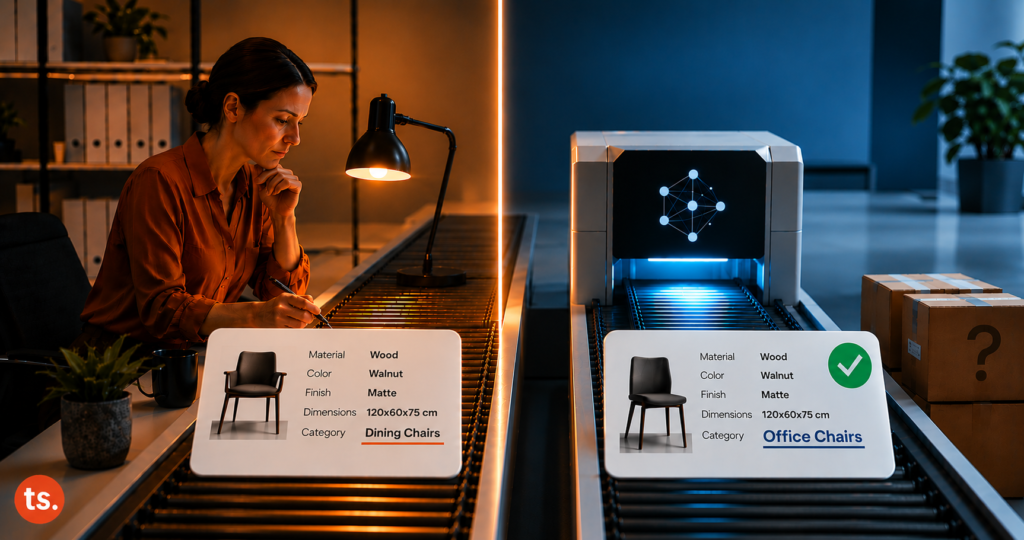
An AI initiative needs to know whether the data can support the specific outputs the AI system will produce, in the specific context it will operate in, without the human judgment layer that used to compensate for what the data was missing. Standard readiness tools were built for a different consumption model.
The AI Readiness Gap Index was built for this one.
Key takeaways
Most standard data readiness assessments were built to confirm that data meets internal quality standards. The AI Readiness Gap Index goes further, assessing whether data can support what the next AI initiative specifically demands.
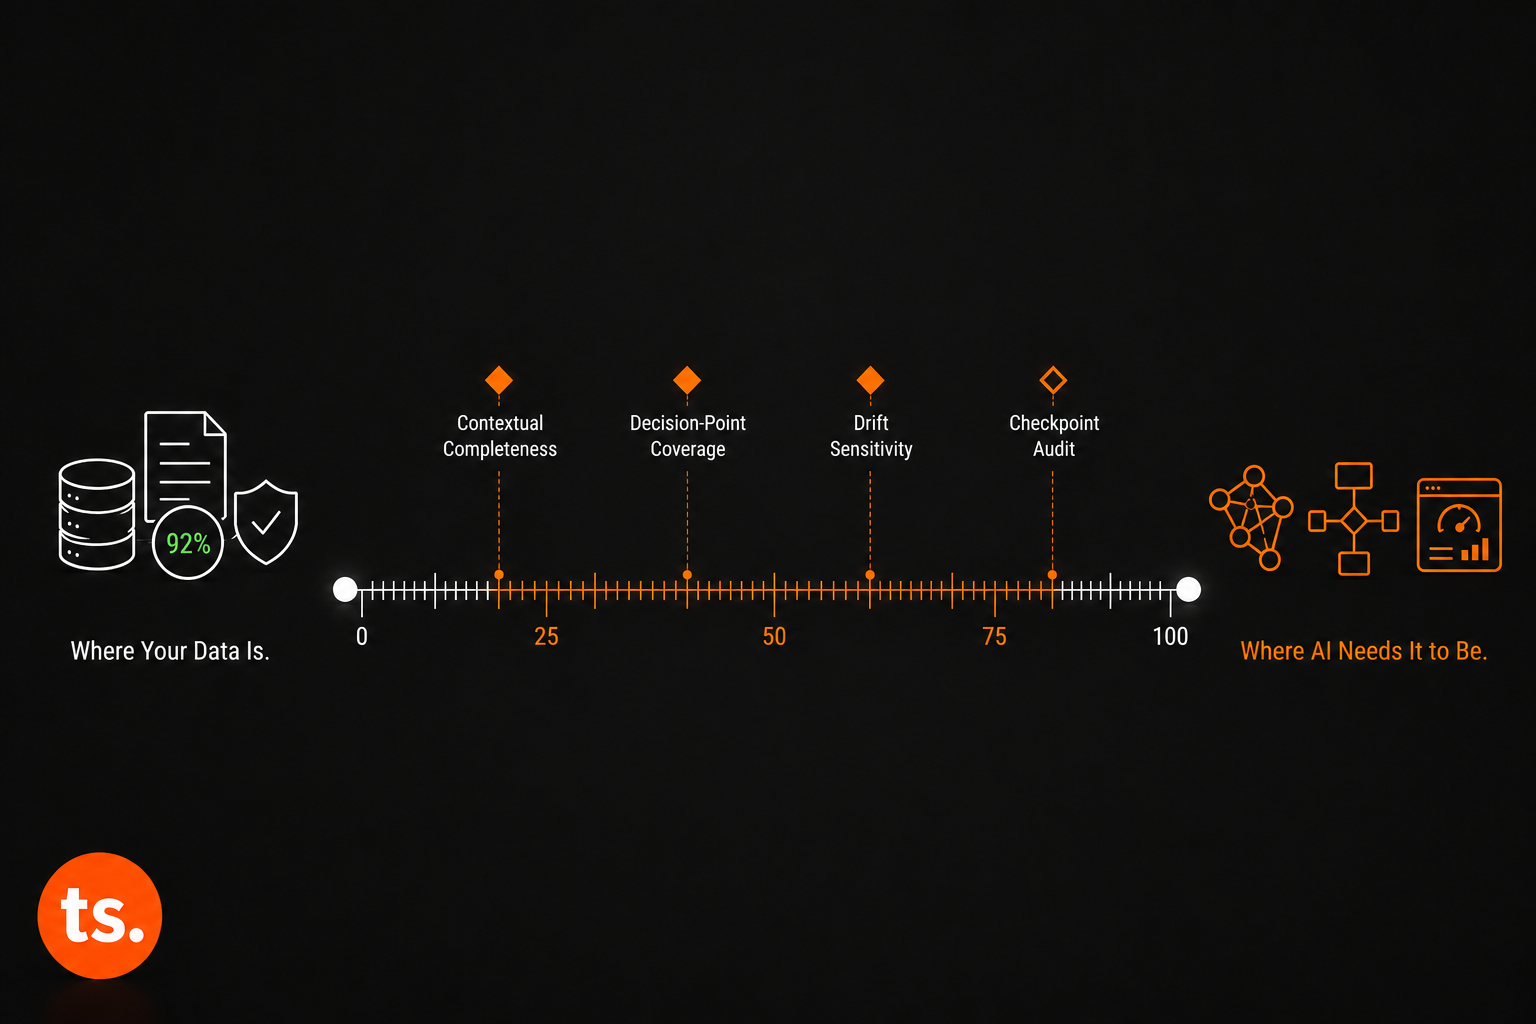
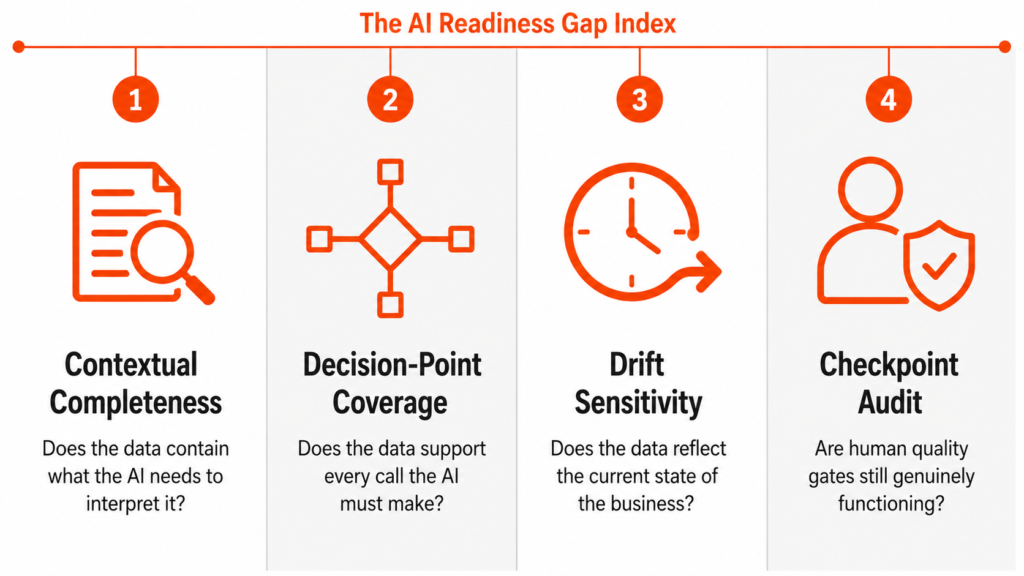
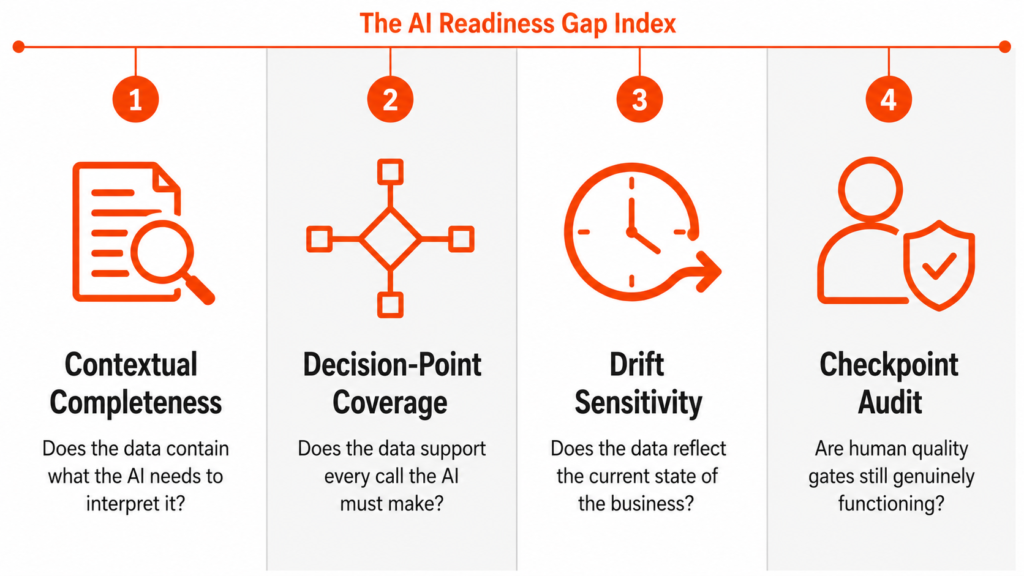
The Index evaluates readiness across four dimensions that standard checks rarely cover: Contextual Completeness, Decision-Point Coverage, Drift Sensitivity, and Checkpoint Audit.
The EDM Association’s 2026 Global Data Management Benchmark found that only 31% of organizations have advanced data strategy capability, leaving most without the foundation required to support AI at scale.
The Index is a structured set of questions the organization needs to answer before committing to an AI initiative timeline, producing a gap assessment rather than a score.
Genuine AI readiness changes every time the consumption model changes. The Index should be applied before every significant AI initiative and reassessed at every material change.
Why Standard Readiness Assessments Leave a Gap
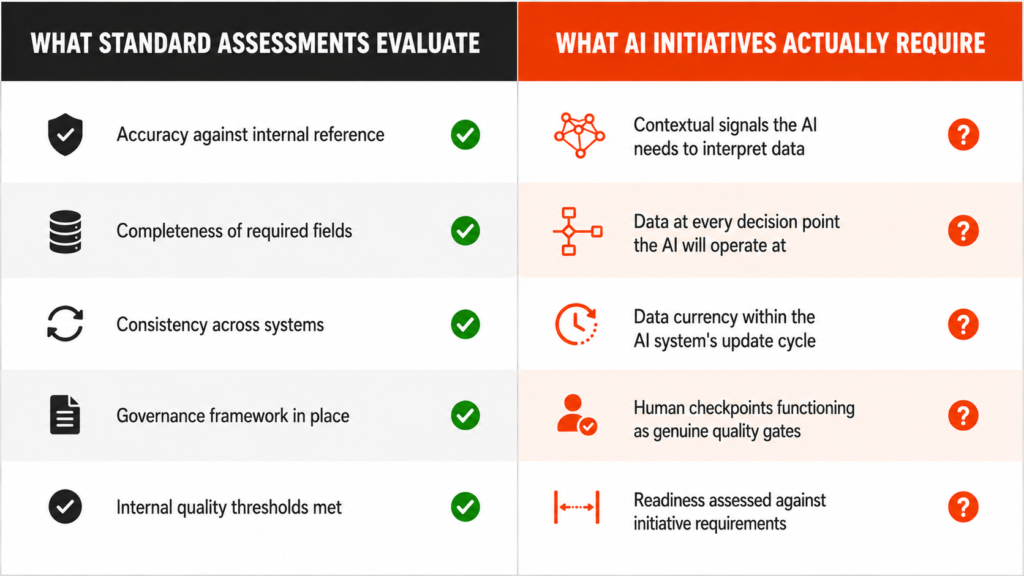
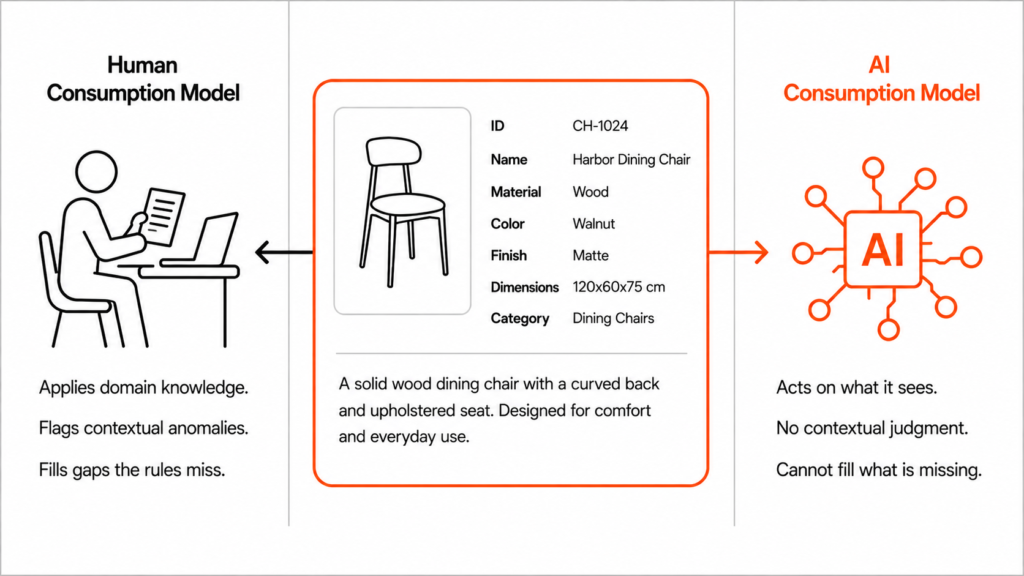
Standard data readiness assessments were designed for a specific consumption model, one where data moves through a system, gets reviewed by a person, and that person’s judgment fills the gaps between what the rules enforce and what the business actually needs. In that model, evaluating accuracy, completeness, and consistency against internal thresholds is sufficient because the human reviewer compensates for whatever the data is missing by applying context, pattern recognition, and domain knowledge.
AI operates without that compensation layer. When an AI system consumes data, it acts on what it sees without the contextual judgment the human reviewer used to supply. A completeness check sufficient for human review may be insufficient for AI consumption, because the data can meet every internal standard while missing the contextual signals, decision-point coverage, data currency, and checkpoint validation the AI system needs to produce a reliable output.
Most organizations discover this gap after committing to an AI initiative timeline, because the readiness assessment they applied was designed to confirm that internal standards are met, which is a meaningful but incomplete measure of what AI consumption specifically requires.
The scale of this problem is confirmed by the EDM Association’s 2026 Global Data Management Benchmark, the most comprehensive cross-industry data management capability assessment available, covering 435 organizations across more than 50 countries. The benchmark found that only 31% of organizations have advanced data strategy capability, leaving most operating in the Developmental or Defined capability ranges and without the foundation required to support AI at scale. Across nearly all data management components, AI investment is outpacing data readiness.
“AI investment is outpacing data readiness. Only 31% of organizations have advanced data strategy capability, leaving most without the foundation required to support AI at scale.”
— EDM Association, 2026 Global Data Management Benchmark Report
The gap is structural. Standard assessments answer the right question for internal data management and an incomplete one for what an AI initiative specifically demands. The AI Readiness Gap Index was built to answer the complete question.
What Is the AI Readiness Gap Index?
The AI Readiness Gap Index is a four-dimension framework for assessing the specific distance between where an organization’s data currently performs and where the next AI initiative needs it to perform.
The Index was built to answer four questions that standard readiness tools do not address:
Does the data contain the contextual signals the AI system needs to interpret what it is seeing?
Does the data at every workflow decision point contain enough for the AI to make the call a human used to make?
Does the data reflect the current state of the business within the AI system’s update cycle?
Are the human checkpoints in the workflow functioning as genuine quality gates?
A data quality audit evaluates whether data meets internal standards, covering accuracy, completeness, and consistency against thresholds the organization has defined. A governance assessment evaluates whether frameworks, ownership structures, and policies are in place. The Index sits alongside both of these, evaluating the specific gap between where data performs today and what the next AI initiative requires of it.
The Index produces a gap assessment. It identifies where the gaps are, how significant they are for the specific initiative being planned, and what it would take to close them before the initiative commits to a timeline that assumes they do not exist.
“The AI Readiness Gap Index assesses the specific distance between where an organization’s data currently performs and where the next AI initiative needs it to perform, across four dimensions that standard readiness checks do not evaluate.”
— ThoughtSpark
The four dimensions are Contextual Completeness, Decision-Point Coverage, Drift Sensitivity, and Checkpoint Audit. Each addresses a specific type of gap that standard assessments do not detect and that AI initiatives consistently encounter after committing to timelines that assumed the data was ready.
Contextual Completeness: What It Measures and Why It Matters for AI
How Contextual Completeness Is Measured
Contextual completeness measures whether data contains the signals an AI system needs to interpret what it is seeing, evaluated against what the AI will consume rather than against what the internal system requires to be populated.
What Standard Assessments Check Instead of Contextual Completeness
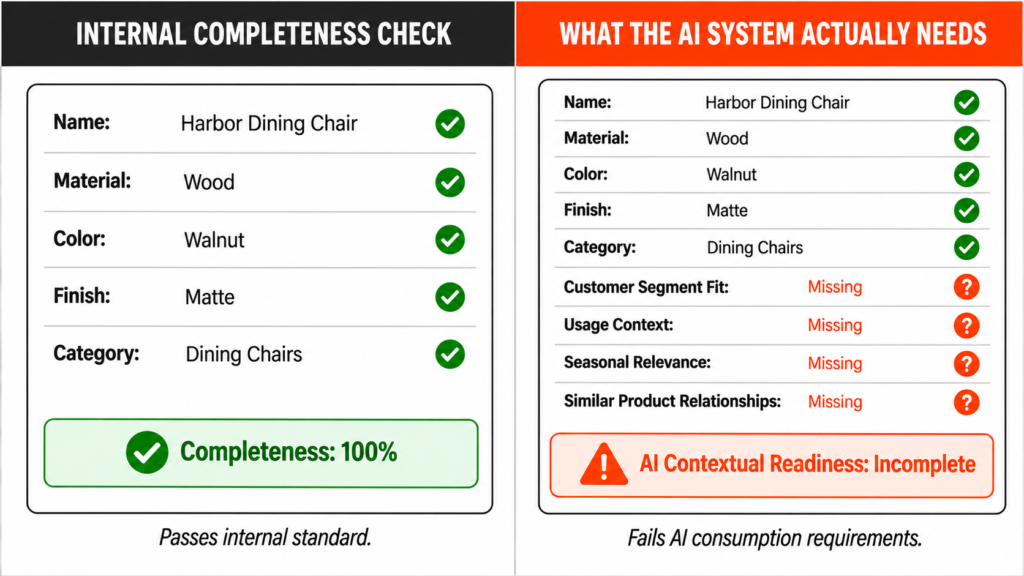
Standard completeness checks evaluate whether mandatory fields contain values. A product record is complete if the required fields are populated. A customer record is complete if the required attributes are present. These checks confirm that the data meets the internal standard, and that standard was defined based on what the internal system requires to process the record, not based on what an AI system needs to produce a reliable output from it.
Why Contextual Completeness Matters Specifically for AI
AI systems need more than populated fields. They need the contextual signals that tell them how to interpret what they are seeing, including the relationships between attributes, the historical patterns that establish what normal looks like, and the categorical context that determines whether a value is appropriate for the specific situation being processed.
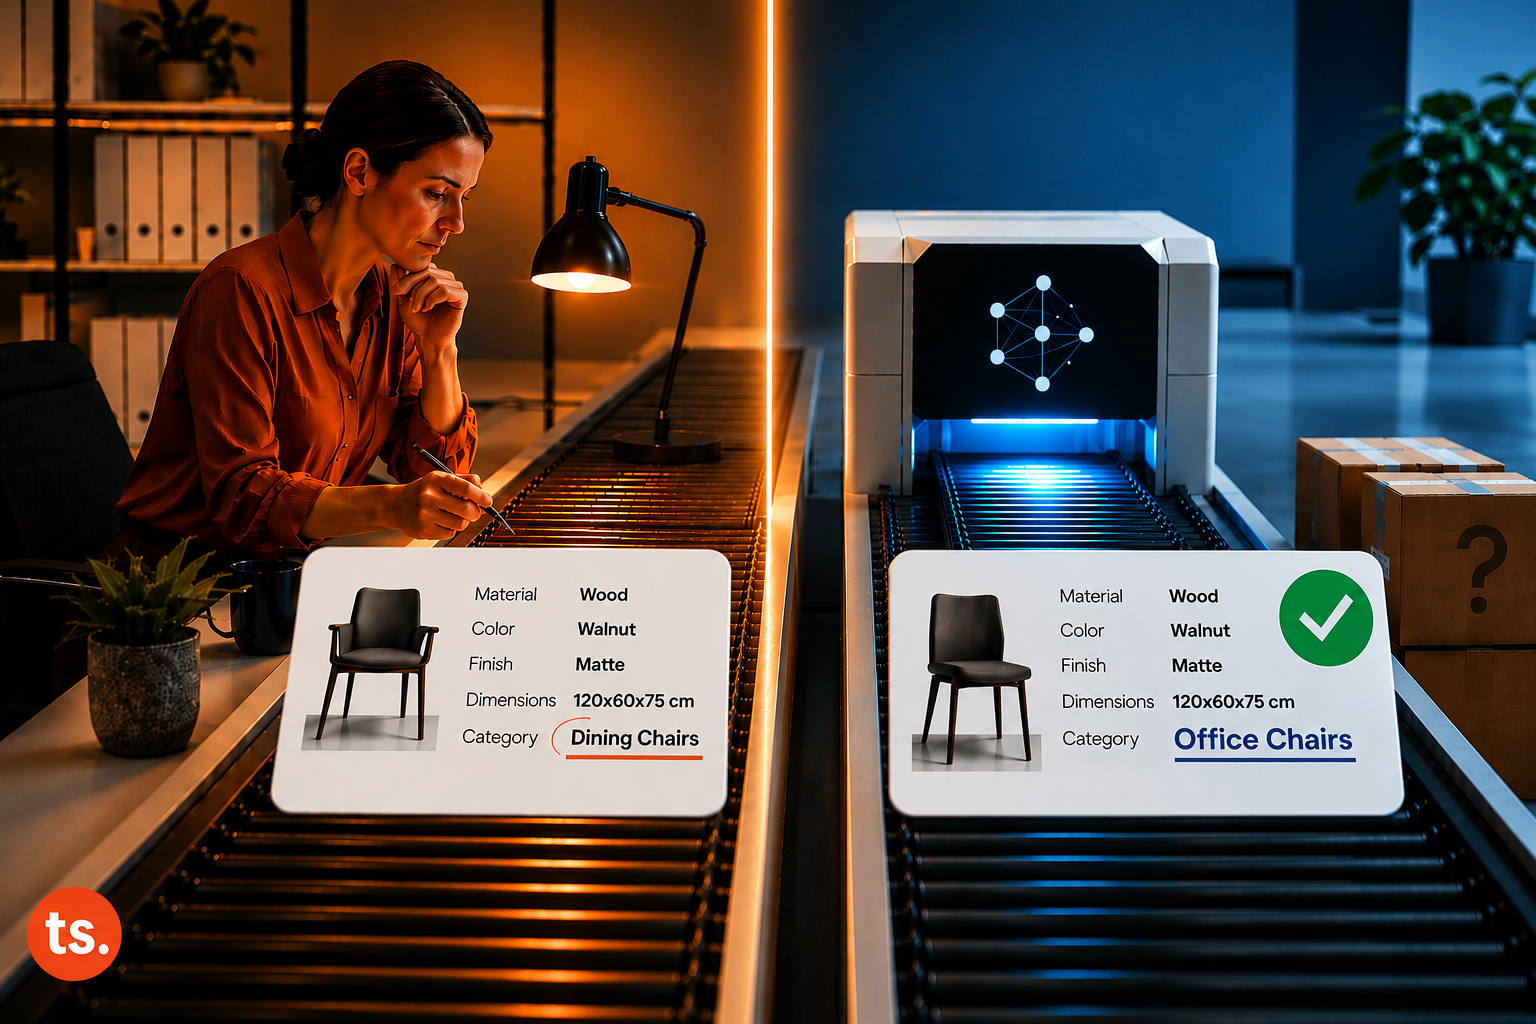
A product record can be 100% complete against internal thresholds and still be missing the attributes an AI personalization engine needs to make the right recommendation for a specific customer segment, because the internal threshold was defined for a human reviewer who would supply that context from memory.
The contextual completeness gap is particularly significant because it is invisible to standard assessment tools. The completeness score looks healthy while the AI outputs diverge from what the business expected, and the connection between the missing context and the divergent output is difficult to trace because the data technically met the standard it was assessed against.
Diagnostic Question: Contextual Completeness
Does the data contain the specific attributes, relationships, and contextual signals the AI system will consume when making recommendations, classifications, or decisions, evaluated against what the AI requires rather than against what the internal system requires to be populated?
What a Contextual Completeness Gap Looks Like Operationally
An AI recommendation engine surfaces the same recommendations regardless of customer segment because the data lacks the segment-specific contextual attributes that would differentiate them
A classification model consistently misclassifies edge cases because the training data contains the required fields but not the contextual signals that distinguish edge cases from standard cases
A generative AI system produces outputs that are factually correct but contextually inappropriate because the data meets internal quality standards while lacking the relationship and context data that would make outputs situationally relevant
Decision-Point Coverage: What It Measures and Why It Matters for AI
How Decision-Point Coverage Is Measured
Decision-point coverage measures whether the data at every point in the workflow where a human used to apply judgment contains enough information for the AI to make the same call reliably.
What Standard Assessments Check Instead of Decision-Point Coverage
Standard readiness assessments evaluate data at the aggregate level, covering overall accuracy, completeness, and consistency across the dataset. They do not map the specific points in the workflow where judgment was applied before the output moved forward, and they do not evaluate whether the data at those specific points is sufficient for the AI to replicate that judgment.
Why Decision-Point Coverage Matters Specifically for AI
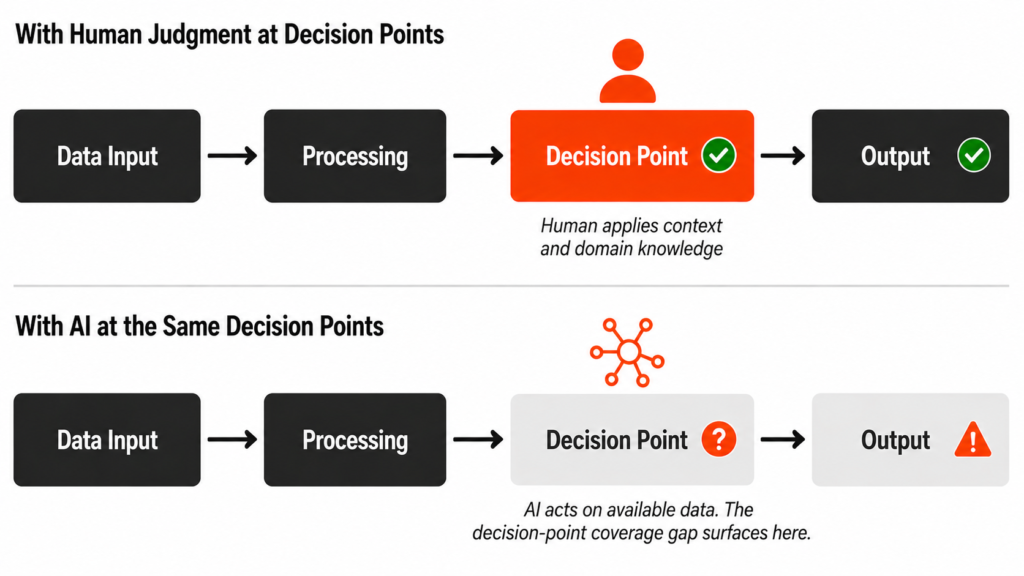
Every workflow that AI is being applied to has points where a human used to look at what the system produced and make a decision before the output moved forward. Some of those decision points were formal and documented, while many were informal, operated by a person who knew enough about the business to know when something looked wrong and who would flag it before it caused a downstream problem.
When AI replaces or accelerates that workflow, those decision points still exist structurally while the human judgment that used to operate them does not. The AI reaches the same point in the workflow and makes the call based on what the data contains. When the data at that point is insufficient for the AI to make the call the human would have made, the AI makes a different call, and the standard readiness assessment never evaluated whether that would happen.
Decision-point coverage assessment requires mapping the workflow before evaluating the data, identifying every point where judgment was applied before the output moved forward, and then evaluating whether the data at each of those points is sufficient for the AI to make the same call reliably.
Diagnostic Question: Decision-Point Coverage
Have you mapped the points in the workflow where a human used to apply judgment before the output moved forward, and evaluated whether the data at each of those points contains enough information for the AI to make the same call reliably?
What a Decision-Point Coverage Gap Looks Like Operationally
An AI system processes standard cases correctly and consistently makes the wrong call in edge cases because the data at those decision points does not contain the signals that allowed the human reviewer to recognise them
A content generation model produces outputs that are structurally correct but commercially inappropriate because the data available at the point between generation and publication does not encode the business context a human reviewer used to apply there
Drift Sensitivity: What It Measures and Why It Matters for AI
How Drift Sensitivity Is Measured
Drift sensitivity measures how quickly data moves away from the state in which it was assessed relative to the AI system’s update cycle, and whether that drift creates a gap between what the AI is working with and what the business currently looks like.
What Standard Assessments Check Instead of Drift Sensitivity
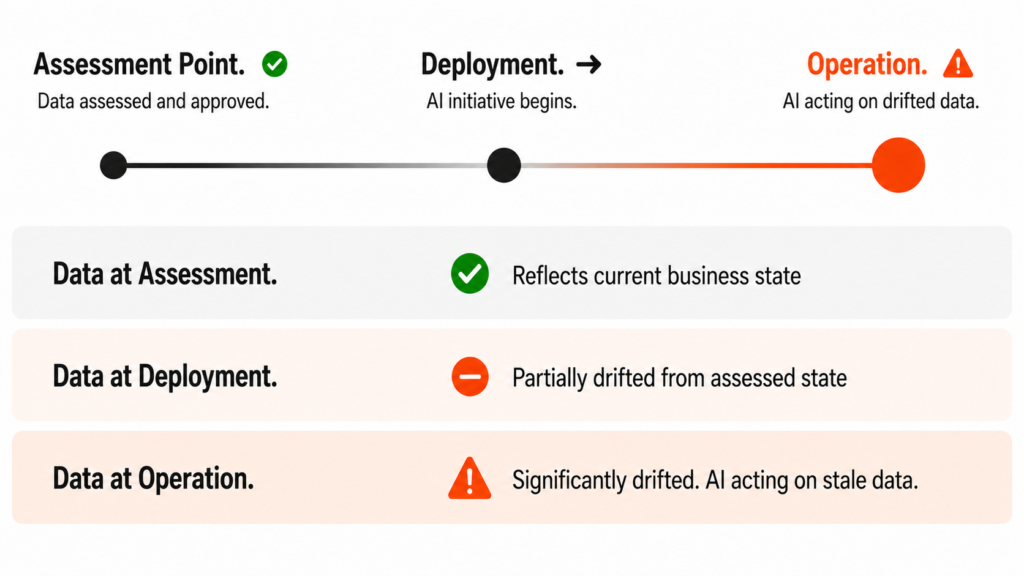
Standard readiness assessments evaluate data at a point in time. The data is assessed, the standard is met, and the initiative proceeds on the assumption that the data will remain in a sufficiently similar state.
In human-reviewed workflows this assumption was manageable because the reviewer notices when something looks different from what it did before and adjusts their judgment accordingly. AI systems continue operating on the data as it was at the point of assessment, with the gap between that state and the current state of the business growing silently while the outputs continue to look correct.
Why Drift Sensitivity Matters Specifically for AI
AI systems make significantly more decisions per unit of time than human reviewers, which means the compounding effect of operating on drifted data is larger and less visible. Data drift that introduces a manageable level of error across ten human decisions a day introduces a materially different level of error across ten thousand AI decisions a day, and that drift may be invisible in the quality dashboard because the data still meets the standard it was assessed against at the last assessment point.
Diagnostic Question: Drift Sensitivity
How quickly does your data drift from the state in which it was last assessed, and does that drift happen faster than your AI system’s update cycle can compensate for?
What a Drift Sensitivity Gap Looks Like Operationally
An AI pricing model begins consistently underperforming against market conditions three months after deployment because the market data it was trained on reflected conditions that have since changed and the model’s update cycle is quarterly
A customer segmentation model produces increasingly inaccurate segment assignments over time because customer behavior data drifts faster than the model retrains, and the drift is invisible in the quality dashboard because the underlying data still meets the completeness and accuracy standards it was assessed against when the model was deployed
Checkpoint Audit: What It Measures and Why It Matters for AI
How Checkpoint Audit Is Measured
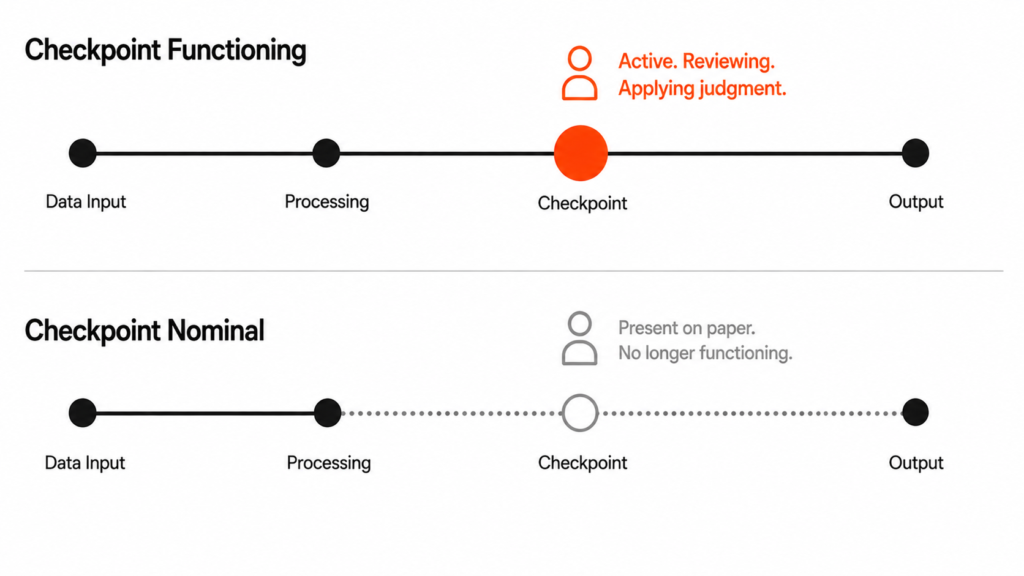
Checkpoint audit evaluates whether the human judgment that used to surface what the rules missed is still functioning in the workflow as a genuine quality gate, assessed against actual review capacity rather than against whether the checkpoint position exists on paper.
What Standard Assessments Check Instead of Checkpoint Audit
Standard readiness assessments evaluate the data. They do not evaluate the process the data moves through or the human judgment that used to operate at critical points in that process. A checkpoint that exists on paper, where a named person is documented as the reviewer, satisfies a governance assessment regardless of whether that person has the time, volume capacity, and authority to genuinely review each item.
Why Checkpoint Audit Matters Specifically for AI
Every data workflow has points where a human used to look at what the system produced and apply something the system could not supply independently: domain knowledge, business context, and pattern recognition built from experience with the data. These checkpoints were rarely documented as formal quality control steps. They existed because the people running the workflow knew enough to know when something was wrong, and they caught things before those things became problems.
When AI enters the workflow, these checkpoints change in one of two ways:
The person is removed from the process on the assumption that the AI makes the checkpoint unnecessary
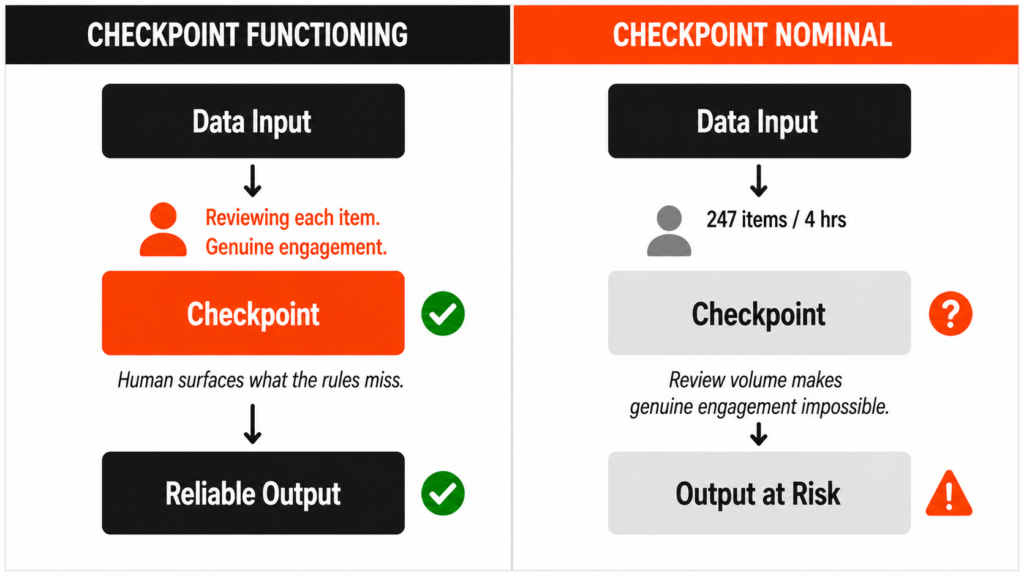
The person remains but is asked to review so many outputs so quickly that the review becomes a formality rather than a genuine evaluation
In both cases, the checkpoint stops functioning as the quality gate it used to be. A checkpoint that processes approvals faster than genuine per-item review could take is functioning as an approval stamp regardless of what the process documentation says, and the data quality it was supposed to protect has no effective quality gate between it and the AI output.
Diagnostic Question: Checkpoint Audit
Where in the workflow did a person used to surface what the rules missed, is that person still in the process, and if they are, are they genuinely reviewing or nominally approving?
What a Checkpoint Audit Gap Looks Like Operationally
An AI content moderation system begins allowing outputs that a human reviewer would have flagged because the reviewer who used to catch contextually inappropriate content is now reviewing AI outputs at a volume and pace that makes genuine engagement with each output impossible
A data enrichment process begins producing records with values that are technically valid but operationally incorrect because the person who used to notice when a supplier’s data conflicted with the business’s own understanding of the product has been moved to a different role and the enrichment now runs without that contextual check
How to Apply the Index Before Your Next AI Initiative
The Index is applied to the relationship between the data and the specific initiative being planned, which means the first step is always defining what the initiative requires before evaluating whether the data delivers it.
Step 1 — Define the initiative’s specific data requirements.
Before assessing the data against any dimension, document what the AI initiative will specifically do with the data:
Which attributes it will consume
Which decision points it will operate at
How frequently the data needs to reflect the current state of the business
Where in the workflow human judgment used to function as a quality gate
This definition becomes the standard against which the four dimensions are assessed. Without it, the assessment defaults to internal standards that were designed for a different purpose.
Step 2 — Apply the four dimensions against those requirements.
For each dimension, evaluate the data against what the initiative specifically requires:
Contextual Completeness: does the data contain the signals this AI system needs, evaluated against what the AI will consume?
Decision-Point Coverage: does the data at each decision point contain enough for this AI to make the call a human used to make?
Drift Sensitivity: does the data currency match what this AI system needs at the pace it will operate?
Checkpoint Audit: are the quality gates this workflow depends on still functioning as genuine gates?
Step 3 — Identify the gaps.
For each dimension where the data does not meet what the initiative requires, document:
What is missing
How significant the gap is for this initiative’s specific use case
What it would take to close it
Gaps vary in significance by initiative type. A drift sensitivity gap matters more for a real-time recommendation engine than a quarterly reporting model. A checkpoint audit gap matters more for a high-stakes decision workflow than a low-stakes classification task.
Step 4 — Decide.
With the gaps identified and sized, the organization faces a genuine decision:
Close the gaps before committing to the initiative timeline
Accept the gaps and plan explicitly for their operational consequences
Restructure the initiative to operate within the data’s current capabilities
Making this decision with full awareness of the gaps, before the timeline is committed, is significantly less expensive than making it after.
The most important output of the AI Readiness Gap Index is the decision the organization makes with full awareness of the gap, before the initiative timeline assumes the gap does not exist.
When to Reassess Your AI Readiness Gap Index Assessment
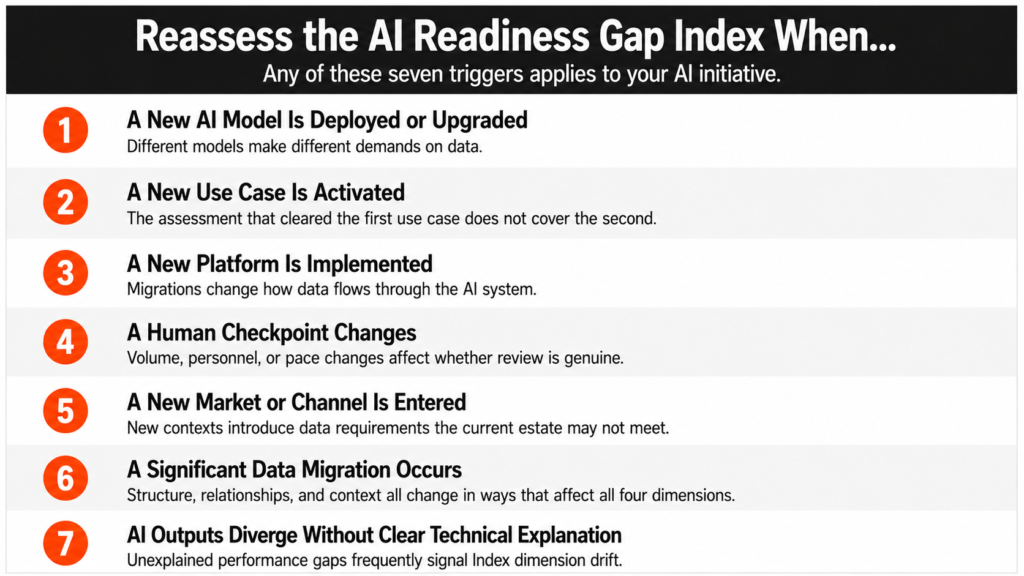
Genuine AI readiness changes every time the relationship between the data and the AI system that consumes it changes materially. Seven specific triggers should prompt a new Index assessment:
A new AI model is deployed or upgraded. Different models make different demands on data. A model upgrade that improves performance on one task dimension may expose gaps in data dimensions that the previous model was less sensitive to.
A new use case is activated. An AI system deployed for one use case may be extended to a second that makes different data demands. The readiness assessment that cleared the first use case does not automatically clear the second.
A new platform is implemented. Platform migrations change how data is stored, processed, and accessed, affecting how data flows through the AI system. A dataset that was contextually complete on the previous platform may be missing signals on the new one.
A human checkpoint changes. When the person operating a checkpoint is replaced, when review volume increases significantly, or when the approval process is accelerated, the checkpoint audit dimension should be reassessed. The checkpoint may have been functioning as a genuine quality gate before the change and be functioning nominally after it.
A new market or channel is entered. New markets and channels introduce data requirements the existing data estate may not meet. The Index should be applied to the new context before the AI system is extended to operate in it.
A significant data migration or transformation occurs. Data migrations change the structure, relationships, and context of data in ways that affect all four Index dimensions. Completeness checked before a migration may not reflect completeness after it.
AI outputs begin diverging from expected performance without a clear technical explanation. Unexplained performance degradation in an AI system frequently signals that one or more Index dimensions have drifted since the last assessment. The Index should be applied before concluding the problem is in the model.
Before your next AI initiative commits to a timeline that assumes the data is ready, the conversation worth having is whether the readiness assessment applied to reach that assumption was designed for what AI actually requires.
That is the conversation ThoughtSpark helps enterprise data and AI teams have through the AI Readiness Gap Index, identifying the specific gaps between the data’s current performance and the initiative’s actual requirements, and building the path to close them before the initiative depends on data that was never assessed for what it will be asked to do.
Think about the last time a data problem was identified before it became expensive. Who identified it?
In most organizations there is someone, or a small group of people, who are deeply embedded in the actual workflow, identifying the exact gaps that automated systems miss despite rarely appearing in official governance frameworks or data dictionaries. They have been in the data long enough to know when something is off, and they act on that knowledge before it becomes a downstream problem.
When AI enters the workflow, that changes. Their role is occasionally restructured, but more often they are moved out of the process entirely on the assumption that speed is an improvement on judgment, or they remain but are asked to review so many outputs so quickly that the review becomes a formality rather than a genuine quality check.
The workflow looks the same from the outside, but the layer that used to surface what the rules missed is no longer functioning the way it was.
That is the gap most AI readiness assessments never account for, and it explains why an AI initiative can pass every data readiness check and still produce outcomes the business did not expect.
This blog covers one specific question most AI readiness assessments never ask: is the person who used to surface what the rules missed still in the process, and if they are, are they actually reviewing or just approving?
Key takeaways
Most AI readiness assessments evaluate whether data is accurate, complete, and consistent, leaving aside whether the human judgment that used to surface what the rules missed is still functioning in the process.
When AI replaces or accelerates a workflow, the human checkpoint that provided contextual correction often disappears with it, without anyone making a deliberate decision to remove it.
An AI outcome can be wrong even when the data is technically accurate, because the outcome depends on the contextual layer the data was missing.
The readiness standard your organization uses today was almost certainly built for a world where a human was still in the loop at the point where judgment mattered most.
Genuine AI readiness requires a different kind of assessment, one that starts from what the AI system will do with the data rather than from what the internal system requires the data to be.
What AI Readiness Assessments Are Actually Checking
When most organizations assess whether their data is ready for AI, they evaluate it against accuracy, completeness, and consistency, covering whether the data matches a reference, the required fields are populated, and the values hold across systems. These dimensions were designed for a specific consumption model, one where data moves through a system, gets reviewed by a person, and the person’s judgment fills the gaps between what the rules enforce and what the business actually needs. In that model, a completeness check is meaningful because the reviewer will notice something missing and ask for it, while an accuracy check works because the person can flag a value that looks contextually wrong even if it is technically correct.
AI operates differently. The data moves through the system and the AI acts on what it sees, without the judgment or domain knowledge the human analyst used to supply, which means a completeness check only confirms that required fields are populated rather than confirming that the data contains the contextual signals the AI needs to produce a reliable output. The same limitation applies to accuracy — matching a reference does not tell you whether that reference reflects what the AI needs to make the right call in the specific situation it is processing.
Wait. Em dash still present in “The same limitation applies to accuracy — matching a reference.” Fix: “The same limitation applies to accuracy, since matching a reference does not tell you whether that reference reflects what the AI needs to make the right call in the specific situation it is processing.”
This is where most readiness frameworks stop short, and it is precisely what Accenture Research’s 2026 study on AI-ready data confirmed when surveying 2,000 organizations deploying advanced AI. Data readiness emerged as the most frequently cited barrier to AI value, with most organizations applying frameworks that predate the specific demands of agentic and advanced AI systems. The assessment was designed for one consumption model, and AI operates in a different one. What that difference costs an organization when it goes unexamined is more specific than most readiness frameworks were built to detect.
“Data readiness is the most frequently cited barrier to AI value. Most organizations are applying readiness frameworks that predate the specific demands of advanced AI systems.”
– Accenture Research, AI-Ready Data for Advanced AI, 2026
The Human Checkpoint Most Assessments Never Evaluate
Every data workflow has moments where a human used to look at what the system produced and apply something the system could not supply independently: domain knowledge, business context, and pattern recognition built from years of seeing what the data means in practice.
Although this checkpoint rarely appeared in governance frameworks or data dictionaries as a formal quality control step, it functioned as one because the person running it had enough context to identify what the rules missed, consistently, before problems reached downstream.
When AI enters the workflow, that person’s role changes in ways that are rarely planned deliberately. Their position is occasionally restructured, but more often they are moved out of the process entirely on the assumption that AI speed is an improvement on human judgment, or they remain while being asked to review so many outputs so quickly that the review becomes a signature rather than a genuine evaluation.
This is the dynamic MIT Sloan Management Review captured in its research on agentic AI, drawing on what leaders have learned from early deployments. The research found that human-in-the-loop oversight frequently becomes performative, with people asked to approve so many things so fast that they do not genuinely engage with what they are approving, leaving a checkpoint that still exists on paper but has stopped functioning as one.
“Human-in-the-loop oversight frequently becomes performative. People are asked to approve so many things so fast that they do not really engage with what they are approving. The checkpoint still exists on paper but has stopped functioning as one.” — MIT Sloan Management Review, Agentic AI: What Leaders Wish They Knew Sooner
What that describes is a process design failure of exactly the kind a standard data readiness assessment was never built to surface, and by the time it becomes visible, the cost of addressing it has already grown significantly.
What Happens When the Checkpoint Disappears
The consequences of removing the human checkpoint are not always immediate, which is part of what makes this failure mode so difficult to detect and so expensive to correct.
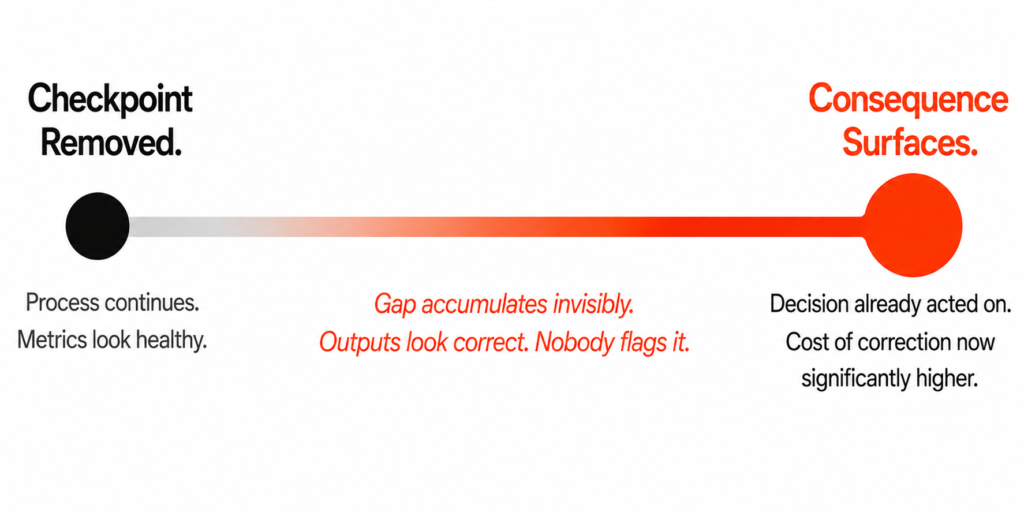
The AI produces outputs, the outputs look correct, the metrics improve, and the initiative is declared a success before the team moves on to the next use case.
The gap surfaces later, when a pattern the human would have identified has been running long enough to produce a decision, a recommendation, or an output that the business has already acted on. By that point the cost of correction is significantly higher than the cost of maintaining the checkpoint would have been, and the connection between the missing checkpoint and the downstream consequence is rarely made because too much time has passed between the two events.
This is what Forrester’s research on the state of agentic AI in 2026 identified as a structural pattern rather than an isolated incident. The research found that agents bolted onto workflows built for human pace produce only task savings, and that genuine value requires rebuilding roles and approval structures around autonomy rather than attaching automation to a process still designed around manual review. The organizations that have captured AI value are those that redesigned the workflow around what the AI actually needs to perform reliably, including identifying where human judgment needs to remain, in what form, and at what frequency.
“Agents bolted onto workflows built for human pace produce only task savings. Real value requires rebuilding roles and approval structures around autonomy rather than attaching automation to a process still designed around manual review.” — Forrester, The State of Agentic AI in 2026
The readiness failure in these cases is structural rather than technical, and it remains invisible to standard readiness assessments because those assessments were built to check the data rather than the process the data moves through, and that distinction points directly to how the standard itself was designed.
Why the Readiness Standard Wasn’t Built for This
The readiness standard most organizations apply to AI initiatives was built for a specific world, one where data moves through a system, a person reviews what comes out, and that person’s judgment is the last quality gate before the output reaches a decision.
In that world, accuracy, completeness, and consistency are the right dimensions to assess because they ensure the data is in the right shape for the person reviewing it, and the person does the rest. AI changed what the rest means. Without a person automatically in the loop, the AI acts on what it sees, without questioning contextually suspicious values, applying domain knowledge, or flagging data that reflects a state of the business that has already changed.
The readiness standard was built for a world where the human checkpoint was a given, and in an AI-first workflow the checkpoint becomes a deliberate design decision rather than an assumed constant. Most organizations are applying a framework designed before AI changed what readiness required, which is a failure of timing rather than intention, and the organizations that close this gap will do so by extending their existing framework to cover the dimensions the original design never needed to address.
What AI Readiness Actually Requires Now
Genuine AI readiness extends the existing standard rather than replacing it, covering the dimensions the original framework never needed to address because a human was always there to fill them in. Four of those dimensions are worth examining specifically, because none of them appear in a standard completeness, accuracy, and consistency assessment, and all of them determine whether an AI initiative delivers what the business expects.
Contextual completeness. The AI needs more than populated fields, specifically the contextual signals that tell it how to interpret what it is seeing. A product record can be 100% complete against internal thresholds and still lack the attributes an AI personalization engine needs to make the right recommendation for a specific customer segment, because the internal threshold was defined for a human reviewer who would supply that context from memory.
Decision-point coverage. Mapping the points in the workflow where a human used to apply judgment, and evaluating whether the data at each of those points contains enough information for the AI to make the same call reliably, is a different exercise from checking whether the data is accurate and complete. Most readiness assessments do not attempt it.
Drift sensitivity. Data that was accurate at the point of assessment may reflect a state of the business that has already changed by the time the AI acts on it, and the question worth asking is how quickly the data drifts relative to the AI’s update cycle. If the drift is faster than the cycle, the AI is consistently acting on a version of reality that no longer exists.
Checkpoint audit. Where in the workflow did a person used to surface what the rules missed, is that person still in the process, and if they are, are they genuinely reviewing or nominally approving? The checkpoint audit is the dimension most organizations have never formally conducted because it never needed to be an assessment step when the human was always there.
Understanding these four dimensions is the starting point, and knowing which of them your current standard already covers is what separates an organization that is genuinely ready from one that believes it is.
How to Know Whether Your Standard Has Kept Pace
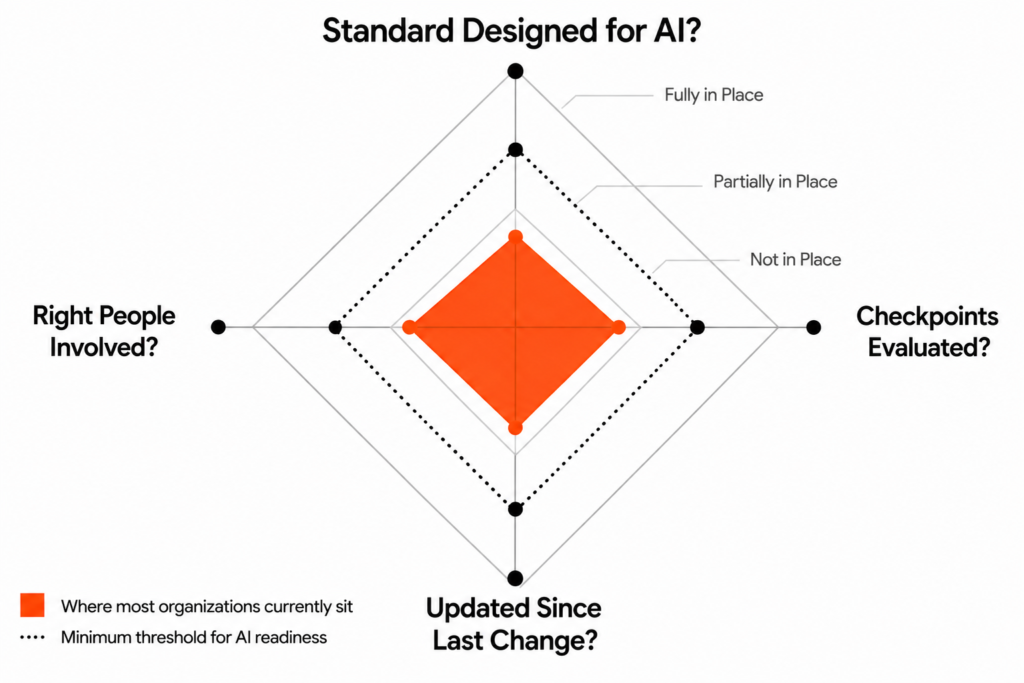
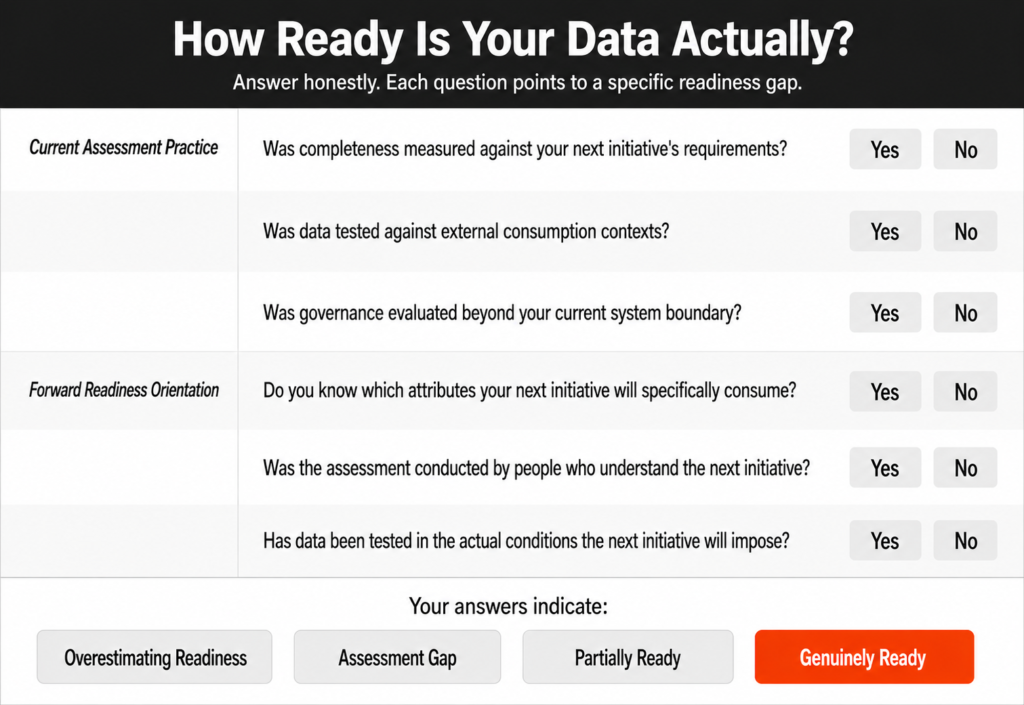
Before extending an existing readiness framework to cover an AI initiative, four questions are worth answering honestly. They are not designed to produce a score. They are designed to surface where the standard has stopped keeping pace with what the AI initiative actually requires.
Was your readiness standard designed before your organization began using AI to consume the data it governs? A standard that predates the AI initiative it is now being applied to was almost certainly designed for a human consumption model, which makes it incomplete for what AI actually requires.
Does your readiness assessment evaluate whether the human checkpoints in the workflow are genuinely functioning? A checkpoint that exists on paper but processes approvals too quickly for genuine engagement is functioning as a formality rather than a quality gate, and a readiness assessment that cannot distinguish between the two is missing the most critical quality layer in an AI workflow.
Has your readiness standard been updated since the last significant change to how the data is consumed? Every time a new AI model is deployed, a new platform is implemented, or a new use case is activated, the consumption model changes, and the readiness standard needs to change with it. Most organizations update their data while leaving the framework they use to assess it unchanged, which means the standard is almost always lagging behind the current deployment.
Do the people who designed your readiness standard understand what the AI system consuming the data actually does with it? If the consumption model has changed, if AI is now doing what a person used to do, the people responsible for the readiness standard need to understand the new model well enough to assess whether the data genuinely supports it, rather than assessing it against a model that no longer reflects how the data is used.
If the honest answer to any of these is no, your readiness standard has not kept pace with what your AI initiative will demand from the data, and the gap between what the standard checks and what AI actually needs is where the initiative’s most expensive surprises are waiting.
Before your next AI initiative extends your existing readiness framework to cover something it was never designed to assess, the question worth answering is whether the standard itself is ready for what AI actually requires, beyond whether the data meets the standard you already have.
That is the assessment ThoughtSpark helps enterprise data and AI teams conduct, identifying the specific distance between the readiness framework you have and the one your AI initiative actually needs, and building the path between the two.
Your organization has probably invested significantly in data readiness.
A governance program. A platform migration. A data quality initiative. Possibly all three. The dashboards are improving. The CDO has a seat at the leadership table. The data strategy is documented and aligned to the technology roadmap.
And yet, when a new AI initiative, a major platform decision, or a channel expansion needs your data to perform, something is not quite ready.
That experience, of believing you are prepared and then discovering you are not, is not a failure of execution. It is a symptom of how most organizations define and measure data readiness, and that definition is almost always measuring the wrong thing.
Key takeaways
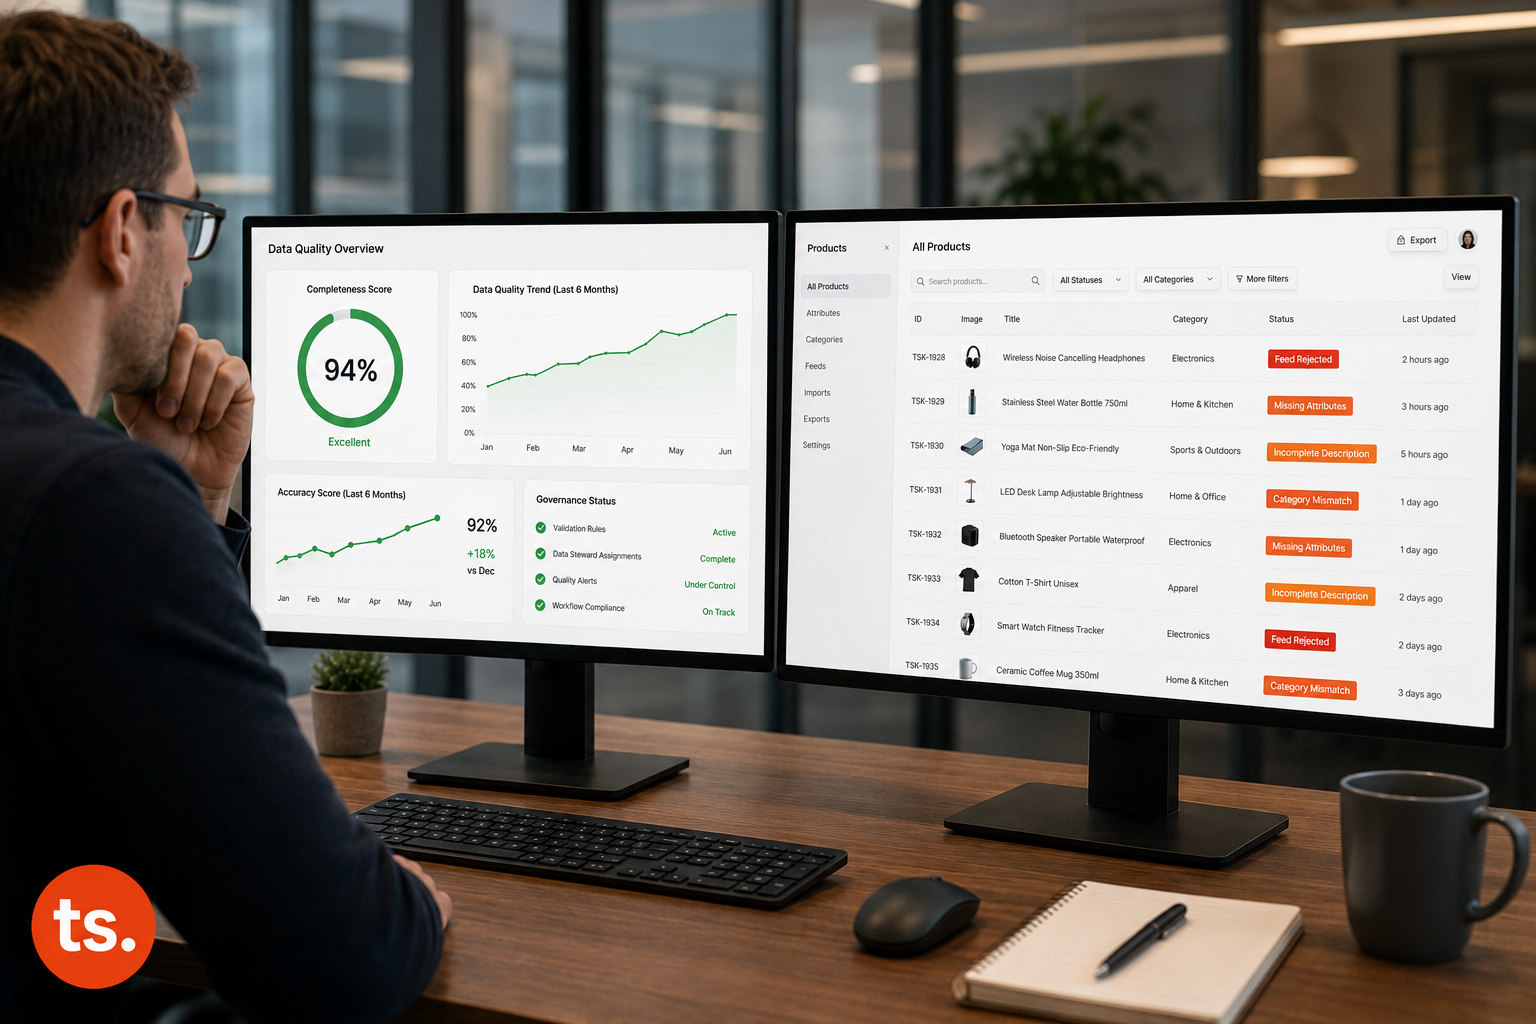
Most organizations assess data readiness against internal standards — whether their data meets the requirements of the systems that store it — not against what the business needs the data to actually do next.
The IBM Institute for Business Value found that 81% of CDOs say their data strategy is integrated with their technology roadmap, yet only 26% are confident their data can support AI-enabled revenue streams. That 55-point gap is what overestimation looks like at scale.
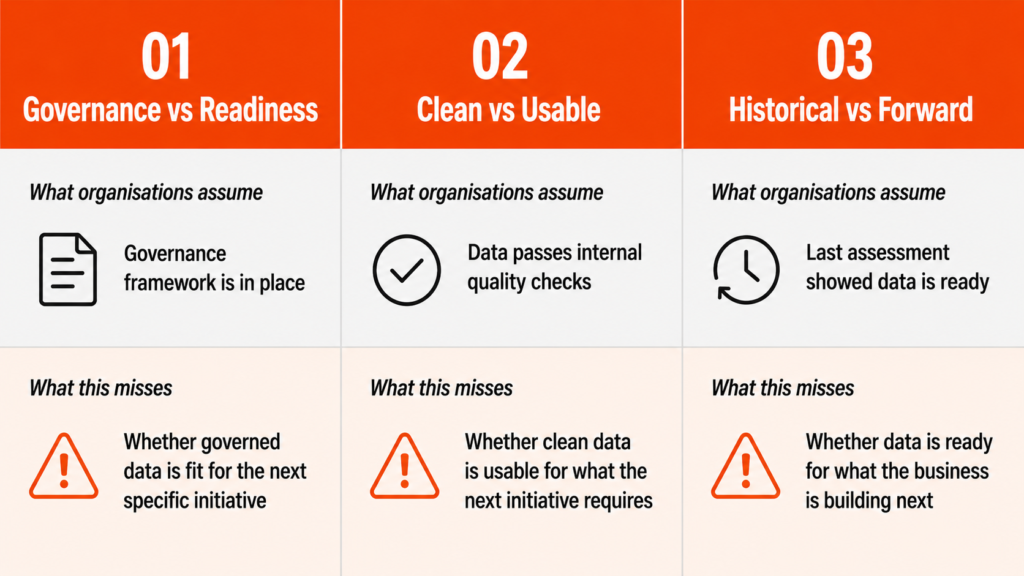
Overestimation happens in three specific ways: confusing governance with readiness, confusing clean data with usable data, and confusing historical readiness with forward readiness.
Genuine data readiness is not a milestone you reach. It is a continuous assessment of whether your data can support the specific outcomes your organization is building toward next.
The question worth asking before your next platform decision, AI initiative, or channel expansion is not whether your data passed the last quality review. It is whether your data is ready for what comes next.
Why Data Readiness Is Harder to Assess Than Most Organizations Realize
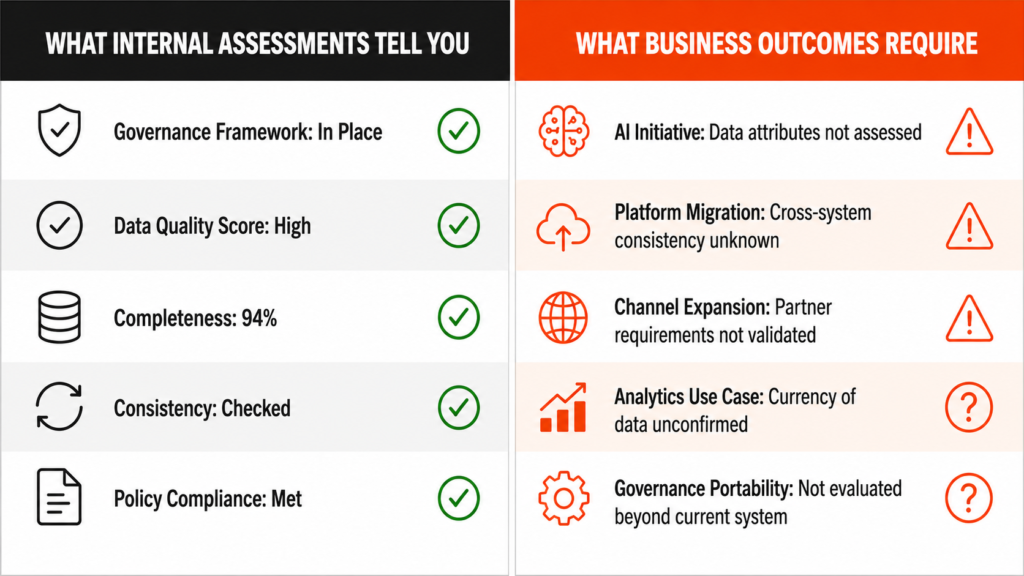
Most Organizations assess data readiness using the tools they already have — quality dashboards, governance audit results, platform implementation reports, completeness scores. These tools measure internal conditions accurately, and the problem is that internal conditions are not what determines whether data performs when the business needs it to.
A governance audit tells you whether your framework is in place. It does not tell you whether the data that framework governs is fit for the specific initiative you are about to commit to. A quality dashboard tells you whether your data meets the thresholds you defined when you built the measurement system, and it does not tell you whether those thresholds reflect what your next AI model, your next platform, or your next channel partner actually requires.
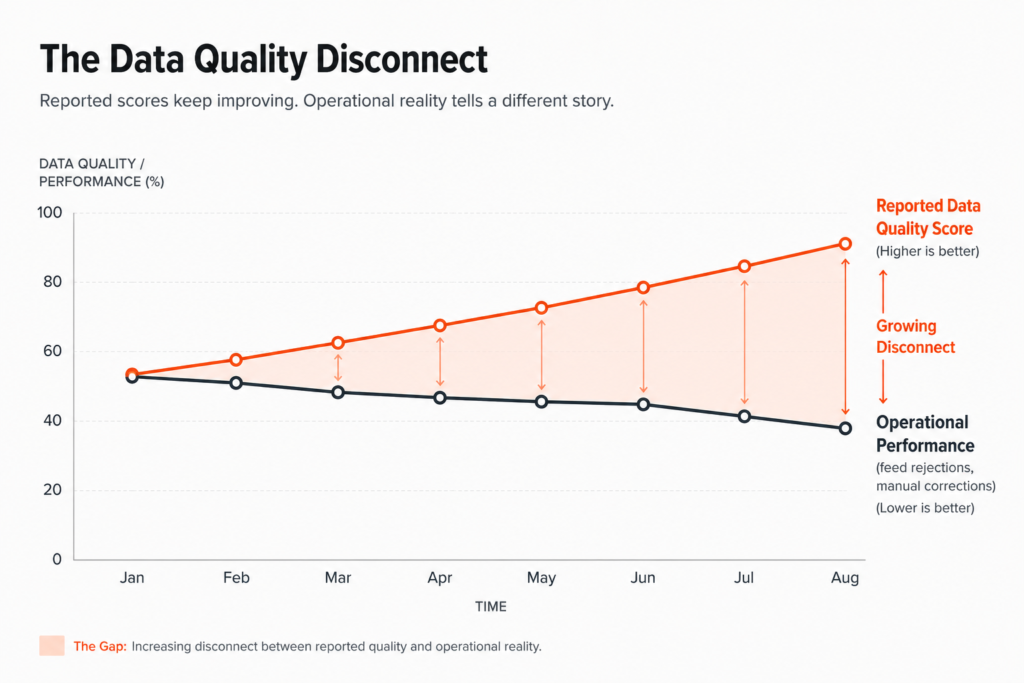
The assessment looks healthy because it was designed to look healthy against the standards it was built to measure, and the gap between those standards and what the business actually needs the data to do is where the overestimation lives.
The IBM Institute for Business Value’s 2025 CDO study, based on 1,700 senior data leaders across 27 geographies, found that 81% of CDOs report their data strategy is integrated with their technology roadmap, while only 26% are confident their data can support new AI-enabled revenue streams. That 55-point gap between strategic alignment and operational confidence is not a coincidence, and it is what happens when Organizations measure readiness against internal strategy alignment rather than against what specific business outcomes actually demand from the data.
“81% of CDOs report their data strategy is integrated with their technology roadmap. Only 26% are confident their data can support new AI-enabled revenue streams. That 55-point gap is what overestimation looks like at scale.”
— IBM Institute for Business Value, 2025 CDO Study
The Three Ways Organizations Overestimate Their Data Readiness
Overestimation is not a single failure. It happens in three specific and distinct ways, and most Organizations are experiencing at least one of them without recognizing it as overestimation rather than simply as an unexpected gap.
Overestimation 1: Confusing Governance With Readiness
Having a governance framework is not the same as having data that is ready to perform. Governance defines the standard, and readiness means the data meets that standard in the specific context where it needs to be used.
Most governance assessments evaluate whether the framework exists — whether ownership is assigned, whether policies are documented, whether quality controls are in place — and they do not evaluate whether the data the framework governs is actually fit for the next initiative the business is about to build on top of it.
A governance Program that was designed to improve data consistency for internal reporting may produce data that is entirely consistent for that purpose and still inadequate for an AI initiative that requires different attribute completeness, different taxonomy consistency, or different cross-system coherence than the governance framework was ever designed to enforce.
The governance is real. The readiness it implies for the next use case may not be.
Overestimation 2: Confusing Clean Data With Usable Data
Data that passes internal quality checks is clean against the internal standard, and it is not necessarily usable for the purpose the next initiative requires.
A product catalogue that is 94% complete against internal thresholds may be significantly less complete against the specific requirements of an AI personalisation engine, a new retail channel, or a marketplace expansion, because the internal threshold was defined to reflect what the internal system needs while the external requirement reflects what the channel, the partner, or the AI model actually consumes.
In each case the completeness score reflects what was defined as quality when the measurement system was built, and the operational consequence reflects what the next initiative actually needs from the data — which is why the score can look healthy while the readiness gap remains significant.
Overestimation 3: Confusing Historical Readiness With Forward Readiness
A data quality assessment tells you how ready your data is today against the standards you defined in the past, and it does not tell you how ready your data is for what you are planning to build next.
The next AI initiative, the next platform migration, the next channel expansion, and the next market entry will each make specific demands on your data that your current assessment was never designed to evaluate. The question the assessment answered was whether your data is ready for what you are already doing, and the question that determines whether your next initiative succeeds is whether your data is ready for what you have not yet built.
A backward-looking metric tells you where you were. Genuine forward readiness requires asking specifically what the next initiative needs from your data and evaluating honestly whether the data can deliver it before the initiative has already committed to a timeline that assumes it can.
The Cost of Getting the Assessment Wrong
The consequences of overestimating data readiness are not always immediately visible, which is part of what makes the overestimation so persistent. The initiative launches, the platform goes live, and the AI model gets deployed, and the gaps in the data do not announce themselves as data readiness failures. They present as performance problems, as unexpected manual workloads, as AI outputs that do not match projections, and as channel launches that take longer than planned.
By the time the data readiness gap becomes undeniable, the initiative has already committed its timeline, its budget, and its leadership credibility to the assumption that the data was ready, and the cost of correcting the gap at that point is significantly higher than the cost of identifying it before the initiative began.
McKinsey’s research on AI data readiness found that more than two-thirds of high-performing companies identify data as the primary obstacle for enabling AI, and only 7% of companies have fully scaled AI across their Organizations. The Organizations that have scaled successfully are the ones that assessed what their AI initiatives actually needed from the data before committing to the initiative, and closed the gaps they found before the initiative depended on data that was not yet ready to support it.
“More than two-thirds of high-performing companies say data is the primary obstacle for enabling AI. Only 7% of companies have fully scaled AI across their Organizations.”
— McKinsey, AI Data Readiness: The Key to Scaling Impact, June 2026
The cost of overestimation is not just delayed ROI. It is the accumulated cost of initiatives that underperform because the data foundation they assumed was ready was not prepared for what the initiative actually demanded. Most data projects do not fail at implementation. They fail before the first line of code because the data was never genuinely ready for what the project required of it.
What Genuine Data Readiness Actually Requires
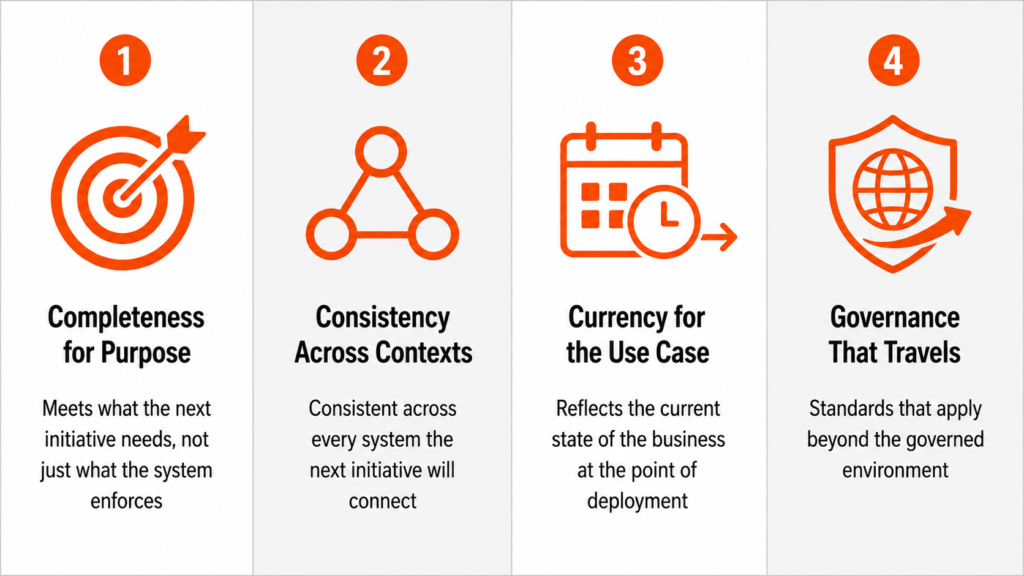
Genuine data readiness is not a status you achieve by completing a governance Program or passing a quality audit. It is a continuous assessment of whether your data can support the specific outcomes your organization is building toward, and it has four dimensions that most internal assessments do not capture.
Completeness for purpose, not completeness for the system.
Internal completeness measures whether required fields are populated against the thresholds the system was configured to enforce, and completeness for purpose measures whether the data contains what the next initiative specifically needs — the attributes an AI model will consume, the fields a new channel requires, the data points a platform migration will need to carry cleanly across systems. The threshold that matters is the one your next initiative depends on, and that threshold is rarely the same as the one your system currently enforces.
Consistency across contexts, not just within systems.
Data that is internally consistent within one system may be inconsistent across the systems a new initiative needs to connect, and cross-system consistency — the same entity described the same way in the PIM, the ERP, the commerce platform, and the analytics layer — is what enables new initiatives to work with your data as it exists rather than requiring a cleaning and normalisation project before the initiative can begin. Most quality assessments evaluate consistency within a system, and genuine readiness requires evaluating it across every system the next initiative will touch.
Currency for the use case, not just accuracy at the last assessment point.
Data that was accurate and current when the last assessment was conducted may have drifted since then, and the next initiative will work with your data as it is at the moment of deployment rather than as it was at the moment of the last review. Currency for the use case means the data reflects the current state of the business in the specific dimensions the next initiative depends on, assessed at the point of deployment rather than at the point of governance review.
Governance that travels with the data.
Governance frameworks typically govern data within a defined system or domain, and genuine readiness means the governance standards travel with the data as it moves between systems, is consumed by new tools, and is used in new contexts. When data leaves a governed environment and enters an AI model, a new platform, or a partner integration, the governance constraints that made it trustworthy in the original context need to apply in the new one, and most governance assessments do not evaluate whether the framework performs beyond the boundary it was built to govern.
How to Know Whether Your Data Is Actually Ready
Before committing to the timeline and budget of your next major initiative, these six questions will tell you more about your actual data readiness than any internal quality dashboard will.
On your current assessment practice:
Was the completeness threshold your last data quality assessment measured against defined by the requirements of your next initiative, or by the requirements of your current system?
Was your data tested against external consumption contexts — the AI model, the channel partner, the platform — or against internal storage and processing standards?
Was your governance framework evaluated for how it performs when your data moves between systems and is consumed by tools and partners outside the governed environment?
On your forward readiness orientation:
Do you know specifically which data attributes your next AI initiative, platform migration, or channel expansion will consume, and have you assessed whether your data delivers them at the quality level required?
Was your last data readiness assessment conducted by people who understand both the data estate and the specific business initiative it is supposed to support?
Has your data been tested in the actual conditions the next initiative will impose, rather than in a controlled assessment environment built against internal standards?
If your honest answers reveal that your assessments were defined against current system requirements rather than forward initiative requirements, and that your data has not been tested against the specific conditions the next initiative will impose, the gap between your reported readiness and your actual readiness is worth understanding before you commit to the next initiative’s timeline.
What Closing the Gap Looks Like in Practice
The Organizations that have moved from overestimating data readiness to genuinely achieving it did not do it by running better assessments of the same kind. They changed what the assessment was designed to answer.
They assessed readiness forward, not backward.
Starting from what the next initiative needs and working back to the data. That shift in direction changes every question the assessment asks, moving from “is our data clean?” to “is our data clean enough for what this initiative specifically requires?”
They tested data against external consumption contexts.
Running the data through the actual conditions the next initiative will impose before committing to the initiative timeline — the AI model consuming the actual data, the channel partner receiving the actual feed, the platform ingesting the actual records. The gaps that surface in this test are the gaps that would have appeared at deployment, surfaced early enough to close them before they cost anything beyond the time to fix them.
They made readiness assessment a continuous practice.
Moving from a pre-project checklist completed once before the initiative launches toward an ongoing evaluation of whether the data estate is keeping pace with what the business is building toward. As the business adds new products, enters new markets, adopts new platforms, and pursues new AI use cases, the readiness question changes, and the Organizations that stay genuinely ready are the ones that keep asking it rather than relying on the answer from the last time they asked.
Before your next platform decision, AI initiative, or channel expansion, the question worth answering is not whether your data passed the last quality review. It is whether your data is genuinely ready for what comes next.
That is the assessment ThoughtSpark helps enterprise data and commerce teams conduct and act on. The Data Readiness Hub is where that conversation starts, identifying the specific distance between where your data currently performs and where your next initiative needs it to perform, and building the path between the two.
What if the correction sprint is not a sign that your data quality programme is failing?
What if it is a sign that your programme was never designed to prevent it in the first place?
That is an uncomfortable question if you have spent the last two years building governance frameworks, assigning data ownership, migrating to a new platform, and watching quality scores trend in the right direction. Because it implies that the problem is not in how well you executed those things. It is in what those things were built to do.
Most data quality programmes are built to manage the correction cycle more effectively. Better tools to catch errors faster. Better ownership to ensure someone is accountable when errors occur. Better metrics to track whether the volume of errors is decreasing. These are all reasonable responses to a visible operational problem and they produce real improvement.
But they are designed around the assumption that errors will keep occurring and that the job is to manage them better.
The organisations where product data quality is genuinely stable made a different assumption. They asked a different question. Not “how do we manage errors more effectively” but “how do we build an environment where errors are significantly harder to create in the first place.”
That question leads somewhere different. And the answer to it is what this blog is about.
Key takeaways
Stable product data quality is not achieved by fixing bad data better. It is built by making bad data significantly harder to create and progress through your system in the first place.
Getting there requires two shifts simultaneously: system design that enforces quality at the point of creation, and cultural ownership that makes data quality part of how your team thinks about their work every day.
Neither shift holds without the other. System enforcement without cultural ownership gets worked around. Cultural ownership without system enforcement decays under deadline pressure.
Wavestone’s 2024 Data and AI Leadership Executive Survey of Fortune 1000 leaders found that 78% identify culture, people, and process as the greatest barrier to becoming data-driven — above any technological limitation. Only 37% have improved data quality despite significant investment.
The organisations that have made this shift stopped treating data quality as something a project achieves and started treating it as something the operational environment maintains continuously.
What a Stable Product Data Operation Actually Looks Like From the Inside
What the week before a campaign launch looks like in a correction-cycle operation versus an organisation where product data quality holds
Before getting into what changes, it is worth being specific about what you are building toward, because “better data quality” is too abstract to be useful as a destination.
Here is what it looks like when product data quality is genuinely stable in your operation.
Your product manager finishes building a new range. The records go live already complete — not complete enough to pass a manual review later, complete against the actual requirements of every channel the products will be sold through. They were built that way because your system made building them any other way slower than building them right.
Your supplier sends a data file. It goes through automated validation on ingestion. The records that meet the standard enter the active catalogue. The records that do not are quarantined immediately, flagged for resolution, and never reach a state where they could cause a feed rejection six weeks from now.
Your team opens the readiness report the week before a campaign. It is a confirmation, not a discovery. There is no sprint. There is no last-minute escalation. There is no quiet agreement to submit with known gaps because the window is closing.
That is not a description of a perfect organisation with unlimited resources and a decade-long transformation behind it. It is a description of what becomes operationally normal once two specific shifts have been made — and it is achievable faster than most data leaders expect once both shifts are being made simultaneously.
The Two Shifts That Separate Stable Quality From the Correction Cycle
If you have run a governance initiative, a platform migration, a data ownership programme, or a quality improvement project and still find yourself in the same correction cycle six months later, the reason is almost always the same.
You made one shift. You needed two.
Most investments in product data quality address either the system or the culture. A new PIM, a governance framework, a data stewardship structure, a measurement programme — each one addresses something real and produces some improvement. None of them produces stability on its own, because stability requires both dimensions to hold simultaneously.
The first shift is system design that enforces quality at the point of creation.
Your system needs to make it structurally difficult to create or progress data that does not meet the standard. Not difficult to remember. Not dependent on the right person catching it at the right moment. Structurally difficult, meaning the record cannot move forward until it is compliant, the taxonomy field cannot accept a locally invented value, and the channel-specific requirement is surfaced at creation rather than discovered at submission.
The second shift is cultural ownership of data quality as part of daily work.
Everyone who touches product data — product managers, category teams, supplier management, marketing operations — needs to understand that data quality is part of their job, not a compliance check that happens somewhere downstream. That understanding needs to be established at onboarding and reinforced consistently enough that it holds under deadline pressure, not just when things are calm.
Wavestone’s 2024 Data and AI Leadership Executive Survey, the longest-running survey of Fortune 1000 data leaders, found that 78% of organisations identify culture, people, and process as the greatest barrier to becoming data-driven, placing it above any technological limitation, and only 37% have been able to improve data quality despite significant and sustained investment. The gap between what organisations invest in and what they actually achieve sits almost entirely in the second shift — the one most quality improvement programmes never fully reach.
“78% of Fortune 1000 data leaders identify culture, people, and process as the greatest barrier to becoming data-driven — above any technological limitation. Only 37% have improved data quality despite significant investment.” — Wavestone, 2024 Data and AI Leadership Executive Survey
What System Design for Data Quality Actually Looks Like
Where quality enforcement happens in a correction-cycle operation versus an organisation with system design for data quality embedded at the point of creation
The most important question about your current system is not which platform you are using. It is where in your process the quality standard actually gets applied.
In most organisations, the honest answer is at the end. The record gets created, enriched, categorised, and submitted. The quality gap becomes visible at submission — or at the retailer rejection that follows. By that point the record has been live in your system for weeks, possibly longer, and fixing it means going back to correct something that should never have been allowed to progress.
In an organisation where quality holds, the standard is applied at the beginning. The record cannot be created without the mandatory fields completed against the actual channel requirements. The taxonomy field is a controlled vocabulary, not a free-text entry point. The enrichment threshold is a validation rule that blocks activation, not a guideline that gets checked later. The quality gap surfaces at creation, when it is fastest and cheapest to close.
Getting your system to that state requires four specific configuration decisions:
Mandatory field validation that prevents record activation rather than flagging for review. The record cannot go live until the required attributes are present and within the accepted values for each channel it is assigned to.
Controlled vocabulary for taxonomy classifications. Category, subcategory, and attribute fields are selected from an approved list. Locally invented values cannot enter your taxonomy because the system does not accept them.
Channel-specific completeness profiles applied at creation. When a product is assigned to a channel, your system surfaces what that channel requires immediately — not when the feed is generated, when the record is being built.
Supplier data validation on ingestion. Incoming files are checked against your quality standard before records enter the active catalogue. Non-compliant records are quarantined for resolution, not allowed to flow through and create correction work downstream.
None of these require a new platform. Most PIM systems can support all of them with the right configuration decisions. The reason most organisations have not implemented them is not technical. It is organisational — the short-term friction these controls create in the creation workflow feels significant in the moment, and quality improvement programmes rarely have enough sustained authority to push through that friction. The organisations that have made this shift found the friction smaller than expected and the operational improvement larger than projected.
What Cultural Ownership of Data Quality Actually Looks Like
System design is the more tractable of the two shifts because it is definable, configurable, and delegatable. Cultural ownership is harder to define and impossible to delegate, which is why most organisations underinvest in it and then wonder why the system enforcement gets worked around.
Cultural ownership is not a training programme or a data literacy campaign. It is a change in how your team understands their own role. Specifically it is the shift from “I create product records and the data team checks them” to “I am responsible for the quality of the data I create, and the system is there to help me meet the standard.”
That shift requires changing several things simultaneously — what your onboarding process establishes from day one, what gets measured and recognised in team performance, how conversations happen when deadline pressure creates temptation to cut a corner, and how your leadership responds when the quality checkpoint slows something down.
Harvard Business Review research examining a two-year data culture programme at Gulf Bank found that building a data-driven culture requires getting everyone involved, not just the data team, and that data quality is the right place to start — not governance frameworks, not technology investment, not data literacy in the abstract. The organisations that successfully established data cultures started by making data quality a shared operational responsibility rather than a specialist function.
“Cultural change requires getting everyone involved, not just the data team. Give data quality strong consideration as the place to start.” — Harvard Business Review, What Does It Actually Take to Build a Data-Driven Culture?
In your operation, that translates into something concrete. The product manager who enters an unapproved taxonomy classification needs to understand — specifically, not theoretically — that this decision is the beginning of a drift that will show up as a feed rejection six weeks from now, attributed to the data team, costing hours nobody planned for. That understanding does not come from a policy document. It comes from an onboarding process that makes the connection clear from day one, from a team environment where individual data decisions and their downstream consequences are visible and discussed regularly, and from leadership that holds the standard consistently rather than approving exceptions under deadline pressure.
The organisations that have established this culture did not achieve it through a formal programme. They achieved it through consistent reinforcement of the same standard across enough situations and enough time that the standard became the default expectation rather than an additional requirement layered onto the role.
Why Neither Shift Works Without the Other
Four operational outcomes determined by the combination of system enforcement and cultural ownership — only the top right quadrant produces stable product data quality
If your system enforces quality standards that your teams have not accepted as their own, watch what happens under pressure. Teams find the fastest path to satisfying the system requirement without changing the behaviour the system was designed to change. The mandatory field gets populated with placeholder text. The controlled vocabulary classification gets selected based on what is closest rather than what is correct. The validation rule that blocks activation gets escalated as an exception rather than resolved at source. Your system is technically satisfied while your quality problem persists in a different form — and your teams have learned that the standard is navigable if you know the right path around it.
If your teams genuinely own data quality as part of their role but your system does not enforce the standard at creation, that ownership holds until the first significant deadline. Then the path of least resistance — submitting the incomplete record, using the unapproved classification, bypassing the review step — becomes the rational choice under time constraint. The cultural commitment was real. The operational environment did not protect it when it mattered. And repeated exceptions under pressure erode the cultural ownership itself, because a standard that is not enforced is not really a standard.
If neither shift has been made, you are running the correction cycle. Data quality is addressed periodically, in response to visible failures, by a specialist team. The sprint runs before every campaign. The rejection triggers an investigation. The quality initiative runs every eighteen months and produces the same result. Nothing has changed structurally and nothing has changed culturally, so the same problems return on the same schedule.
When both shifts have been made simultaneously, your system enforces the standard at creation and your teams understand why the standard exists and accept it as part of how their role is defined. When deadline pressure creates temptation to bypass the checkpoint, cultural ownership makes escalation more likely than workaround. When a new product category creates a situation the system did not anticipate, cultural ownership means your teams raise the gap rather than inventing a local solution that drifts from the standard. The two shifts reinforce each other continuously, and that reinforcement is what makes the quality stable rather than episodically improved.
You cannot make one shift and then add the other. Each one creates the conditions that make the other sustainable. System enforcement without cultural ownership gets worked around from day one. Cultural ownership without system enforcement decays the first time it is tested under pressure. They need to develop together, and that simultaneity is what makes this structurally different from every governance initiative or platform migration you have already run.
How to Know Which Shift Your Organisation Has Actually Made
Six diagnostic questions to identify which shift your organisation has actually made — and which quadrant your current operation sits in
Before deciding what to invest in next, it is worth being honest about where you actually are. These six questions will place you in one of the four quadrants more accurately than any governance audit or quality dashboard will.
On system enforcement:
When a product record is created in your PIM with incomplete mandatory attributes, does your system prevent activation or flag it for later review while allowing it to progress?
When a team member enters a taxonomy classification that does not exist in your approved vocabulary, does your system reject the entry or accept free text alongside controlled values?
When a product is assigned to a retail channel, does your system surface the channel-specific attribute requirements immediately at creation or does the compliance check happen later in the process?
On cultural ownership:
When a supplier data file arrives with attributes that do not match your taxonomy standard, does your receiving team resolve the gap before records enter the active catalogue or do the records go live with the expectation that corrections happen before the next submission?
When deadline pressure makes it faster to bypass the quality checkpoint than to resolve the underlying gap, what does your team typically do — and what does their manager reinforce?
When a new team member joins and begins creating product records, does their onboarding establish data quality as part of their role from day one or does it focus on the workflow and leave quality standards as something they learn from the data team over time?
If your honest answers to the first three questions reveal that your system allows non-compliant data to progress, and your honest answers to the second three reveal that quality decisions are made by your data team rather than by the people creating the data, the correction cycle is the predictable outcome. Both shifts are still ahead of you — and your next quality initiative will not change that until you address them simultaneously.
What Changes When Both Shifts Are in Place
Most organisations treating data quality as a problem to solve keep discovering that the solution does not hold. The governance framework produces results while it is being actively managed and then degrades when attention moves elsewhere. The platform migration improves the environment but the correction cycle returns within two campaign cycles because the data being created in the new environment is no different from the data that was created in the old one. The ownership assignment creates named accountability that never translates into operational behaviour because the system does not enforce it and the culture does not reinforce it.
The pattern is consistent across organisations of different sizes, different industries, and different platform environments. The investment is real. The intention is genuine. The result is always the same because the approach is always the same — treating data quality as something you achieve through a well-executed project rather than something your operational environment maintains continuously.
What changes when both shifts are in place is not a specific metric or a single operational outcome. What changes is the fundamental posture of the organisation toward product data quality. It stops being a problem your data team manages and starts being a condition your operational environment maintains. The correction sprint stops being a standard phase in your campaign planning and starts being an exception that signals something in the system or the culture needs attention.
That shift in posture is what separates the organisations that keep running quality initiatives from the organisations that stopped needing them. And it is available to any organisation willing to address both dimensions simultaneously rather than continuing to invest in one while the other remains unaddressed.
If the questions in this blog surfaced gaps in either shift — or both — the conversation worth having is about what it would actually take to build them simultaneously in your operation. That is the work ThoughtSpark does with enterprise data and commerce teams: identifying the specific distance between where your product data quality currently operates and the conditions that would make it stable, and building the path between the two.
What would you do if your data quality score improved by twelve points over two quarters and your retailer rejection rate did not change at all?
Most data and commerce leaders have been in that room, where the dashboard looks healthy, the governance programme is showing results, and leadership is satisfied, while somewhere in the background the commerce team is still building the same correction spreadsheet they built last quarter and the quarter before that, before the same seasonal submission deadline.
The score improved while the operation kept running exactly as it had before.
That is a measurement gap, and it tends to be one of the most expensive gaps in a commerce operation because it creates confidence in a situation that deserves scrutiny.
Most organisations tracking product data quality invested in measurement for the right reasons, including visibility, accountability, and a way to demonstrate that governance work was producing results.
The metrics most organisations use measure the condition of data inside their systems against internal standards, and they rarely extend to whether that data performs reliably in the operational environment it was actually created for.
That distinction is where the false sense of progress lives, and understanding where that gap comes from and why it tends to grow quietly over time is what this blog covers.
Why Data Quality Scores Improve While Operational Problems Persist
A completeness score measures whether a field has a value, leaving aside whether that value is correct for the channel the product is being submitted to.
An accuracy score measures whether data matches an internal reference, leaving aside whether that reference reflects what a specific retailer, marketplace, or syndication partner actually requires.
A data quality dashboard aggregates scores across thousands of records and surfaces a number representing average performance against internally defined thresholds, and it rarely surfaces the forty SKUs that will fail tomorrow’s submission because their taxonomy classification does not match what a specific channel accepts.
The score goes up while the operational problem continues, because the score is measuring something real, just not what determines whether the data performs when it reaches the channel.
The Data Quality Disconnect: reported scores rising while operational performance declines
That gap has a financial consequence that most organisations have never attributed to their measurement framework. Forrester’s research found that more than one quarter of global data and analytics professionals estimate their organisations lose over $5 million annually due to poor data quality, with 7% estimating losses of $25 million or more. These are organisations with measurement frameworks in place. The measurement is not preventing the loss because what is being measured and what is actually going wrong are two different things.
“More than one quarter of global data and analytics professionals estimate their organisations lose over $5 million annually due to poor data quality. These are organisations with measurement frameworks already in place.”
— Forrester Research
The Three Measurement Gaps That Create False Progress
What the metric measures vs. what determines performance
Gap 1: Internal Standards vs Channel Requirements
Most product data quality frameworks define standards based on what the internal system requires, so a record is considered complete if the mandatory fields in the PIM are populated and accurate if it matches the master data reference.
The operational environment is not the internal system. It is the retailer portal, the marketplace listing, the syndication feed, and the customer-facing product page, each of which has its own requirements that can change without notice, are often more granular than the internal standard, and sometimes require attribute combinations that the internal completeness check never evaluates.
A product record that scores 100% complete internally can still fail a retailer submission because a required channel-specific attribute was never part of the internal completeness definition.
Gap 2: Populated Fields vs Usable Values
Completeness metrics count whether a field has a value, and they rarely evaluate whether that value is usable for the purpose the field serves.
A product description field containing “TBD” is technically complete, and so is a category field populated with a legacy classification that no current retailer accepts, and so is a weight field containing a value in the wrong unit for the destination channel.
In each case the completeness score counts the field as populated, even when the value it contains is not fit for the purpose the field was created to serve, which is why the score can show improvement while the correction sprint still runs before every submission.
Gap 3: Snapshot Quality vs Continuous Quality
Data quality scores are typically calculated at a point in time, whether that is a weekly report, a monthly dashboard, or a quarterly review presentation, and product data does not stay static between those measurement points.
New products are added, existing records are updated by different teams following different working assumptions, and supplier data arrives in formats that pass the ingestion check and then drift from the taxonomy standard over time, which means a record that scored well on last month’s report may have been modified three times since then by three different people.
The score reflects the state of the data at the point of measurement, which is rarely the same as the state of the data at the point of execution, and that gap is where feed rejections tend to originate.
Why Organisations Keep Measuring the Wrong Things
Understanding why this measurement gap persists is more useful than simply identifying that it exists.
The metrics most organisations use were designed to be measurable rather than comprehensive, because completeness is straightforward to calculate, accuracy against an internal reference is easy to automate, and a dashboard that aggregates those scores and shows a trend over time is something leadership can understand and act on.
The metrics that would actually reflect operational performance are harder to build and harder to present, because feed acceptance rates by retailer, attribute compliance rates by channel, and the percentage of products submittable to a given marketplace without manual intervention all require connecting internal data quality measurement to external operational outcomes, a connection that is technically harder to build and tends to surface numbers that look worse than the completeness score, which makes it harder to present to leadership that has been receiving an improving trend for two years.
So organisations measure what is easy, the easy measurement shows improvement, the operational teams continue running correction sprints, and the gap between the two realities widens quietly.
Most product data quality measurement programmes were defined when the governance initiative was established and have not been revisited since, so the metrics report on a data environment that has continued evolving while the framework has not evolved with it. MIT Sloan Management Review research on KPI governance confirms this as a documented organisational pattern, finding that it takes effective governance to ensure KPIs evolve, remain aligned with strategic aspirations, and are trusted by workers and managers alike, and that the organisations that sustain effective measurement treat their frameworks as living systems rather than infrastructure decisions made once and reported against indefinitely.
“Effective measurement is a living system. Most product data quality programmes were defined once, when the governance initiative launched, and have not been revisited since.”
— Adapted from MIT Sloan Management Review, Governance for Smarter KPIs
What the Dashboard Does Not Show
What sits beneath a healthy reported score
When a data quality dashboard shows a score of 87% and an upward trend, it is telling a specific story about a specific set of measurements, and what it is not showing is equally important to understand.
It is not showing the product manager who reviewed forty records manually before last week’s submission because the completeness check passed and the channel compliance check did not exist, and it is not showing the retailer relationship strained for two quarters by recurring feed rejections that the internal quality score never registered as a problem.
It is not showing the new product introduction that took three weeks longer than planned because the enrichment required for the primary launch channel was not part of the standard quality threshold and was only discovered during the final submission review, and it is not showing the AI initiative underperforming because the product data it works with scores well on internal completeness and carries taxonomy inconsistencies that the measurement framework never caught.
A score of 87% with an upward trend is real information and incomplete information simultaneously, and incomplete information about data quality is particularly costly because it creates confidence where scrutiny would be more useful.
How the False Sense of Progress Compounds Over Time
The measurement gap would be a manageable problem if it stayed contained, and it tends not to.
An organisation that believes its data quality is improving will underinvest in the root cause work that would actually improve operational performance, because the dashboard justifies the current investment level while the correction cycles continuing beneath it get treated as operational friction rather than as evidence that the measurement framework is missing something important.
How the gap compounds: score improves, investment shifts elsewhere, correction cycles continue, the gap widens
Leadership makes decisions based on the reported progress, resources get allocated elsewhere, the governance programme is considered mature, and the focus moves to the next initiative, while the operational teams are still correcting data before every campaign, the retailer rejection rate has not improved, and the data foundation that every subsequent initiative will be built on is not as strong as the dashboard suggests.
By the time the gap becomes undeniable, usually at a moment of significant operational failure, the distance between the reported progress and the operational reality is much larger than it would have been if the measurement gap had been identified and addressed earlier.
What Measurement Actually Needs to Capture
The shift required is straightforward to describe, though genuinely difficult to execute because it asks organisations to accept that their current measurement may be telling them less than they think.
Effective product data quality measurement connects internal standards to external operational outcomes, measuring whether the data in those fields enables the business to execute without manual intervention at the point of execution.
In practice that looks like:
Feed acceptance rates tracked by retailer and channel rather than internal completeness scores tracked in aggregate
Attribute compliance rates measured against each channel’s actual requirements rather than against a single internal standard
New product introduction cycle time tracked from record creation to first successful channel submission
Manual correction volume tracked per campaign and per submission window rather than absorbed into general operational activity
The percentage of active SKUs submittable to the primary channel without any manual intervention, measured regularly rather than at a governance review point
These take more effort to build than completeness scores, and they reflect the operational reality that internal scores often obscure, and they give leadership a measurement framework that actually connects to what the commerce team experiences before every deadline.
The Connection to the Broader Pattern
This series has traced a consistent pattern across five blogs, and the measurement gap is the final layer of it.
The replatforming investment moved the data without fixing its foundation, the governance initiative produced a framework without changing operational behaviour, the ownership assignment created accountability on paper without enforcing it in the system, and the workaround cost accumulated invisibly while the operation declared itself functional.
Now the metrics measuring progress are creating confidence in a situation where the underlying problems have not been resolved, just reported around, and the data quality score is the last place this pattern hides because once an organisation believes its data quality is improving it stops looking for evidence that it is not.
The Question Worth Asking About Your Current Measurement
Before presenting the next data quality dashboard to leadership, one question is worth sitting with.
If every data quality metric your organisation currently tracks showed a perfect score tomorrow, would your commerce and product data teams be able to launch a major campaign, onboard a new retailer, and expand to a new channel without any manual correction work?
If the answer is no, the metrics are measuring something other than what determines operational performance, and they measure something real and useful in its own way, just not the thing that will tell you whether the product data foundation is actually working.
That gap between what the score says and what the operation requires sits at the strategic level, because every investment decision made on the basis of an improving score that does not reflect operational reality is a decision made on incomplete information.
The conversation worth having starts with understanding what the current dashboards are not showing, and that is the gap ThoughtSpark helps enterprise data and commerce teams identify and address: the distance between data quality as it is measured and data quality as it actually performs in the operational environment.
The week before a major seasonal campaign, someone on the commerce team pulls the product readiness report.
Of the 3,400 SKUs going live across seven retail channels, around a third need manual attribute corrections before the feeds can go out. Some are missing required fields for specific retailers. Some have taxonomy values that do not match the channel’s accepted classifications. Some were created by the supplier data team using a template that has not been updated to reflect the current channel specifications. A handful have conflicting values across the PIM, the ERP, and the commerce system, and nobody is certain which version is correct.
The team knows what happens next. Someone builds a spreadsheet. Responsibilities get divided. People work through it over the following three days, alongside everything else they were supposed to be doing that week. The feeds go out on time. The campaign launches. Leadership sees the launch date met and the channel coverage achieved.
What leadership does not see is the invoice.
Not a literal invoice. There is no line item in the budget that reads “cost of correcting product data before campaign launch.” The cost is distributed. It lives inside the overtime hours, the delayed projects, the team members pulled away from higher-value work, the retailer relationships strained by late or incomplete submissions, and the quiet understanding across the commerce operation that this is just what the week before a major campaign looks like.
It has always looked like this. It will look like this again before the next one.
Why Product Data Workarounds Stay Invisible Until They Are Enormous
The reason workaround costs rarely get calculated is structural. They are distributed across teams, time periods, and activities in a way that makes them impossible to see on a single report or dashboard.
A product manager spending three hours correcting attribute values before a retailer submission records that time as product management work. A commerce operations lead spending two days building and maintaining a master correction spreadsheet before a seasonal launch records that time as campaign preparation. A data team member investigating a rejected feed to identify which attribute caused the rejection records that time as operational support.
None of these are recorded as what they actually are: the cost of product data quality problems that were never resolved at source.
According to PwC’s 2026 Digital Trends in Operations Survey, based on 767 operations and supply chain leaders at US companies, 89% of organisations say their technology investments have not fully delivered expected results, and poor data quality is specifically identified as impacting organisations’ ability to achieve value from digital initiatives. The survey surfaces a paradox that most commerce operations leaders will recognise: 84% of leaders say they have become comfortable making decisions even when data is not perfect, while simultaneously acknowledging that poor data undermines outcomes.
That paradox has a name in daily operations. It is called a workaround.
The workaround is the gap between what the data should be and what it actually is, filled in by human effort at the point of execution. And because the effort is distributed across many people making many small corrections continuously, it rarely accumulates into a number that anyone calculates.
MIT Sloan Management Review research by Thomas Redman found that poor data quality costs organisations between 15% and 25% of revenue. The most significant component of that cost is not the errors themselves. It is the human effort spent accommodating those errors — correcting them, working around them, seeking confirmation in alternative sources, and dealing with the downstream consequences when neither correction nor workaround is sufficient.
That accommodation cost is what most commerce and product data teams are carrying. Silently. Continuously. At scale.
The Three Categories of Product Data Workaround Cost
Most organisations think about workaround cost as a single type of problem: people doing manual work that should be automated. The actual cost structure is more complex than that and more expensive. Product data workarounds create cost in three distinct categories simultaneously, and all three are running at the same time in most commerce operations.
Direct Labour Cost — The Hours That Should Not Exist
The most visible component of workaround cost is the direct labour required to perform the correction.
A feed enrichment sprint before a major retailer onboarding. A taxonomy reconciliation exercise before a marketplace expansion. A data cleaning project triggered by a channel compliance audit. An attribute correction cycle before every seasonal campaign.
Each of these consumes hours from people whose time carries a cost. In most organisations, the people doing this work are product managers, commerce operations specialists, or data stewards — roles that are not cheap and are not supposed to be spending their time correcting records that should have been complete when they were created.
The direct labour cost of a single correction cycle is calculable: hours spent multiplied by the loaded cost of the people involved. What makes this cost structurally invisible is that it is never calculated. It is absorbed into the role’s general activity and reported as operational work rather than as a cost of poor data quality.
Across a year, across every campaign, every retailer onboarding, every channel expansion, every new product introduction cycle — the accumulated labour cost of these corrections represents a significant operational expense that most organisations have never seen on a single report.
Opportunity Cost — The Work That Did Not Happen
The second category is less visible and more expensive over time.
When a product manager spends three days correcting attribute values before a retailer submission, those three days were not spent on something else. The channel expansion analysis that was supposed to happen that week was deferred. The product content improvement project that had been scheduled got pushed. The competitive pricing review that needed to be completed before the end of the quarter was deprioritised.
Workarounds do not just consume time. They consume the capacity for the higher-value work that the people doing them were hired to do.
In a commerce operation running continuous correction cycles — which is most commerce operations — the opportunity cost compounds. Teams become perpetually reactive, organised around the next correction cycle rather than around strategic product data improvement. The work that would prevent the correction cycle from being necessary never gets done, because the correction cycle consumes the capacity that would have been used to do it.
This is the mechanism MIT Sloan Management Review describes as organised cleanup mode: a state in which organisations have formalised their response to bad data without addressing the conditions that create it. As MIT Sloan research on proactive data quality management explains, companies that remain in organised cleanup mode find the gains are generally small. Finding errors is straightforward. Fixing them without understanding the business context is not. And the cycle continues because the root cause — data being created without quality standards enforced at source — is never addressed.
The opportunity cost of remaining in this mode is not just the time lost. It is the strategic progress that never happened.
Downstream Execution Cost — What Goes Wrong Despite the Workaround
The third category is the cost that accumulates when the workaround is insufficient, late, or simply missed.
A retailer feed goes out with a corrected set of attributes, but the correction was based on last quarter’s specification. The retailer has updated their requirements. The feed is rejected. The team investigates. A resubmission is prepared. The window for the promotional placement was missed. The product does not appear in the retailer’s seasonal campaign at the planned position.
A marketplace expansion onboarding is delayed because the enrichment sprint that was supposed to clean the data before submission was not completed on time. The delay costs two weeks of channel availability during a peak trading period.
A new product launch goes live across four retail channels with incomplete specifications because the correction cycle ran out of time before the launch deadline. Customer-facing pages show incomplete product information. Conversion rates for those SKUs underperform against the campaign forecast.
These are downstream execution costs: revenue impact, channel relationship damage, and operational disruption that occur because the workaround either failed to compensate fully for the underlying data problem or was not completed in time to prevent the consequence.
Deloitte’s research on manual adjustments in the data supply chain identifies exactly this dynamic: manual adjustments across the data supply chain increase complexity and operational risk with a cumulative impact on business outcomes. The cumulative nature of that impact is the critical observation. Each workaround that partially compensates for a data problem leaves residual risk. That residual risk accumulates across every correction cycle, every campaign, every channel, and every product category that is being maintained through manual intervention rather than through a data foundation that performs reliably without it.
Why Workarounds Feel Like Problem-Solving When They Are Actually Problem-Deferring
There is a reason workarounds persist in organisations that have the resources and the intention to fix the underlying data problems. They work. In the short term, for the immediate deadline, the workaround delivers the result that was needed. The feed goes out. The campaign launches. The onboarding completes.
That short-term success is what makes workarounds so expensive over time.
Every time a workaround delivers the immediate result, it reinforces the belief that the situation is manageable. The campaign launched. The retailer accepted the feed. The quarterly targets were met. The underlying data problem is still there, but the evidence of its cost was absorbed by the team that corrected it and distributed across time and activity in a way that never produced a visible number.
The next correction cycle begins with the same data foundation the last one started with, because the workaround addressed the symptom and the root cause was deferred to a point when things are less busy, when there is more resource available, when the next governance initiative gets prioritised.
That point rarely arrives. Because the next correction cycle is already consuming the capacity that would have been used to address the root cause.
This is the pattern MIT Sloan identifies as the common trap: organisations see themselves as data customers who consume data created elsewhere, correcting errors as they encounter them. They do not see themselves as data creators who are responsible for the quality of the data at the point it enters the system. The correction cycle perpetuates itself because the mindset that would break it — every person who creates or modifies data is responsible for its quality at source — never gets established.
The workaround culture and the data quality problem are self-reinforcing. Workarounds make it possible to operate without addressing the root cause. Operating without addressing the root cause guarantees that workarounds will always be necessary.
The Compounding Effect — Why Workaround Costs Grow Faster Than the Business
The most dangerous characteristic of product data workaround costs is that they compound.
As a commerce operation grows — more products, more channels, more retailers, more campaigns, more regions, more supplier relationships — the volume of data that needs to be maintained grows with it. If that data is being maintained through correction cycles rather than through a quality foundation, the correction work grows proportionally with the business. More products means more records to correct. More channels means more channel-specific requirements to accommodate. More retailers means more feed specifications to manually maintain.
The business scales. The workaround cost scales with it.
In an organisation managing product data well — with governance embedded in the systems where data is created, with ownership enforced through workflow checkpoints, with quality standards applied at the point of entry — business growth does not proportionally increase the correction workload. The foundation absorbs the growth because the standards and controls apply to new products and new channels through the same system logic that applies to existing ones.
In an organisation managing product data through workarounds, growth creates more workarounds. The correction team grows. The correction sprints get longer. The tools built to manage the corrections — the master spreadsheets, the validation macros, the pre-submission checklists — become increasingly complex. The institutional knowledge of how to run the correction cycle becomes a critical operational dependency, concentrated in a small number of people who know which retailer requires which format and which product category needs which manual override.
That concentration of knowledge in individual people rather than in documented, system-enforced standards is itself a risk that most organisations have not priced. When those people leave, or change roles, or are unavailable during a critical launch window, the correction capability temporarily disappears and the consequences arrive immediately.
What the Workaround Budget Would Look Like If Anyone Built It
Most organisations have never tried to calculate the total cost of their product data workarounds. The distributed nature of the cost makes it genuinely difficult to aggregate. But the exercise is worth attempting, because the number that emerges is almost always larger than expected and almost always larger than the investment that would be required to address the root cause.
A workaround budget for a typical commerce operation would need to account for:
Direct correction labour: The hours spent by product managers, commerce operations specialists, data stewards, and marketing operations teams on attribute corrections, taxonomy reconciliations, feed reformatting, enrichment gap filling, and data conflict resolution — multiplied by the loaded hourly cost of those roles — across every campaign, every retailer onboarding, every channel expansion, and every new product introduction cycle in a twelve-month period.
Management oversight of corrections: The time spent by team leads and managers planning correction sprints, allocating resource, reviewing outputs, managing escalations, and reporting on readiness status — all of which exists because the correction cycle exists.
System and tooling cost: The licences, build time, and maintenance cost of the tools built to manage corrections — validation spreadsheets, data cleaning scripts, pre-submission checklists, custom integrations designed to compensate for data quality gaps between systems.
Downstream execution failures: Lost revenue from retailer feed rejections, delayed channel launches, incomplete product pages, missed promotional placements, and onboarding delays — each of which can be partially or fully attributed to product data quality gaps that workarounds failed to compensate for in time.
Opportunity cost: The value of the strategic work that was deferred because the correction cycle consumed the capacity that would have been used to do it. This is the hardest to calculate and the most significant over time.
Most organisations that have attempted this calculation have found the total exceeds the cost of the governance, system, and process investment that would address the root cause. The workaround is more expensive than the fix. It is simply more visible as individual corrections and less visible as an aggregate cost.
Why Workarounds Survive Governance Initiatives and Platform Migrations
The previous blogs in this series established two specific patterns. Replatforming rarely eliminates product data problems because the migration moves the data without changing the conditions that create the problems. Governance initiatives rarely produce lasting operational change because the frameworks they produce sit above the operational workflows where data decisions actually happen.
Both patterns produce the same consequence: the workaround survives.
After a platform migration, the correction cycle continues in the new environment because the data foundation that was migrated was the same data foundation that required corrections before the migration. The platform changed. The correction workflow transferred with the data.
After a governance initiative, the correction cycle continues because the governance framework defined the standards without embedding them in the systems where records are created. The standards exist in the documentation. The correction workflow continues because the system does not enforce the standards at the point of data creation.
This is why workaround costs are so persistent. They are not caused by any single failure. They are the cumulative consequence of a series of investments — platform, governance, ownership — that each addressed a visible aspect of the product data problem without reaching the root cause: the absence of quality enforcement at the point where data enters the system and at every point where it is subsequently modified.
Until that enforcement exists — in the form of validation rules, required fields, controlled vocabularies, automated completeness checks, and workflow checkpoints that prevent non-compliant records from progressing — the workaround will fill the gap. Because something has to.
How to Calculate What Your Workarounds Are Actually Costing
Before scoping the next data quality initiative, technology investment, or governance programme, one exercise is worth completing.
Map every correction cycle your commerce and product data teams run in a typical quarter. For each one, record:
Who performs it and how many hours it takes
What triggers it — a campaign, a retailer submission, a channel onboarding, an audit
What the consequence would be if it were not performed
Whether it addresses the same underlying issue as the previous cycle
Then apply a loaded cost to the hours. Add an estimate of the downstream revenue impact of the correction cycles that were incomplete or late. Add the management time spent planning and overseeing them.
The number that results is your current workaround budget. It is what you are already spending, distributed invisibly across roles and activities, to compensate for a data foundation that does not perform reliably without human intervention.
Compare that number to the cost of the investment that would reduce it. In most commerce operations, the comparison is instructive. The workaround budget is larger. Often significantly larger. And unlike an investment in fixing the root cause, the workaround budget does not decrease over time. It grows with the business.
What would it take for your largest seasonal campaign to launch without a correction sprint in the week before it? If the answer is unclear, the workaround budget is doing more work than the data foundation, and the gap between them is costing more than most organisations have calculated.
What Organisations With Low Workaround Costs Do Differently
Organisations that have genuinely reduced their product data correction workload share a characteristic that is less about the sophistication of their technology and more about where quality is enforced.
In a low-workaround commerce operation:
Product records cannot be activated until completeness thresholds are met for every configured channel. The incomplete record does not reach the submission queue. It gets flagged at creation, not at launch week.
Taxonomy classifications are controlled vocabularies in the PIM. A product manager cannot enter a free-text category. They select from approved values. The taxonomy drift that creates downstream feed rejections does not accumulate because the system does not permit the local classifications that cause it.
Supplier data goes through an automated validation on ingestion. Records that do not meet the quality threshold are quarantined before they enter the active product catalogue. The enrichment gap sprint before every campaign launch does not exist because the gap is identified and resolved before the record is ever live.
Channel-specific attribute requirements are mapped to product creation workflows. When a product is assigned to a channel, the system surfaces the required attributes for that channel and flags gaps immediately. The channel compliance discovery that currently happens during pre-submission review happens at the point of product creation instead.
None of these require extraordinary technology. They require the quality standards that governance initiatives typically document to be translated into system logic — validation rules, required fields, workflow triggers, automated checks — rather than left as policies that teams are expected to remember and apply manually.
The translation is the work. And it is the work that most organisations defer because it comes after the governance initiative closes and the project has already been declared complete.
ThoughtSpark works with enterprise data and commerce teams to identify where product data workaround costs are accumulating and what it takes to build the operational foundation that reduces them. If the correction cycles described in this article are a recognised part of your commerce operation, the conversation worth having is about the cost of continuing them versus the investment required to address what is causing them.
There is a moment most data and commerce leaders recognise.
A product record arrives in the wrong state. An attribute is missing. A classification is inconsistent with what three other records in the same category use. Someone investigates. The record has a named owner in the governance framework. That person is contacted. They did not know the record existed. Or they knew it existed but did not know they were responsible for its quality. Or they knew both of those things but had no clear way to act on the responsibility within the systems and workflows they use every day.
The ownership was assigned. The accountability never arrived.
Most organisations that have invested in product data governance have also invested in defining ownership. It appears on the framework as one of the foundational elements — stewards named, domains scoped, responsibilities documented. In practice, ownership tends to be the part of the governance framework that looks most complete on paper and functions least reliably in operations.
Understanding why that gap persists, and what it takes to close it, is what this blog works through.
Why Product Data Ownership Breaks Down After Governance Initiatives
Ownership is assigned during governance initiatives because the initiative creates the right conditions for that conversation to happen. Stakeholders are engaged. The question of who is responsible for what gets raised in workshops and working groups. Decisions get made and documented. A steward is named for each domain or product category. The framework reflects genuine organisational agreement.
The initiative then closes.
What the initiative produced was a record of who is responsible. What it did not produce was a change to the environment where those responsible people actually work. The systems they use day to day, the workflows they follow, the approval processes they operate within — none of these changed because of the ownership assignment.
According to Cynozure’s 2026 State of the Industry Report, based on insights from 60 senior data and AI leaders across sectors including retail, consumer goods, and financial services, 40% of organisations still split data strategy ownership across multiple executives, and 17% report no clear owner at all. These are not small organisations with immature data practices. Nearly half of respondents reported revenue over £1 billion. Ownership fragmentation at that scale is not a resourcing problem. It is a structural one.
The governance framework named a steward. The operational environment kept running without them.
The Difference Between Assigned Ownership and Operational Accountability
What Ownership Assignment Produces
When governance initiatives define data ownership, they typically produce:
A named steward for each data domain or product category
A documented scope of responsibility
An escalation path for resolving data conflicts
A RACI or equivalent matrix showing who is responsible, accountable, consulted, and informed
Governance meetings where ownership decisions get made
These are real outputs. The conversations that produced them required genuine organisational alignment. The ownership structure reflects something that was agreed.
Why Operational Accountability Does Not Follow Automatically
A named steward can only influence product data quality at the moments when the system or workflow routes a decision to them. If those moments do not exist — if the product creation workflow does not require steward approval, if the enrichment process does not trigger a review, if the taxonomy update does not notify the domain owner — then the steward is responsible in the governance framework and invisible in the operational process.
That distinction is where most product data ownership structures break down. The steward was named in the workshop. The system never learned their name.
How Ownership Confusion Creates the Operational Problems Teams Experience
When ownership exists nominally rather than operationally, the consequences are specific and recurring. They tend to show up in a consistent set of situations.
Conflicting Product Records Across Systems
When multiple teams can update the same product record without a stewardship checkpoint, the record reflects whoever updated it most recently. The merchandising team updates the product description for a promotional campaign. The supply chain team updates the same record with logistics attributes. The digital team updates it again with channel-specific content. No single version is authoritative. No one is sure which one should be.
The governance framework has a named owner for this product category. That owner was not consulted during any of these updates. They find out about the conflict when a retailer rejects the feed.
Taxonomy Inconsistency That Governance Did Not Prevent
A product manager introduces a new subcategory for an incoming range. The taxonomy owner exists on the governance framework. The product creation workflow does not require their approval before the classification is saved. Three months later, the same product type has been classified under four different values by four different team members who each created what made sense to them at the time.
Enrichment Gaps That Surface at the Wrong Moment
A new marketplace requires a set of attributes the existing product records do not carry. An enrichment owner is named in the governance framework. The workflow for adding new channel requirements does not loop them in. The gap is discovered during onboarding, not during product creation when it would have been far cheaper to address.
In each of these situations, the ownership structure was in place. The operational process ran around it.
Why Ownership Breaks Down More Predictably in Complex Organisations
The governance initiative assigned ownership at a point in time, for a data environment that existed during the initiative. Organisations are not static. Ownership structures degrade as the organisation around them evolves.
New product categories get created that the original ownership matrix never anticipated. Teams are restructured and named stewards move to different roles or leave the organisation. Systems get added or replaced and the integration between the new environment and the governance framework is never fully established. Commercial urgency produces decisions that bypass the stewardship process because the deadline is today and the steward is available next week.
Gartner’s research on data governance platforms consistently identifies the gap between governance maturity as measured by framework completeness and governance effectiveness as measured by actual data quality outcomes. Organisations with documented ownership structures and organisations with operationally enforced accountability produce measurably different results, and the gap between them grows over time as business complexity increases.
The ownership framework was built for the organisation as it existed. The organisation kept changing. The framework did not adapt with it.
What Operational Accountability Actually Requires
Organisations where product data ownership produces real accountability tend to have made one decision that others have not. They stopped treating ownership as a governance artefact and started building it into the operational environment where data decisions get made.
In practice, that looks like:
A product record in a given category cannot be activated without a review step that routes to the named domain owner
A taxonomy classification outside the approved vocabulary triggers an automatic flag before it can be saved
An enrichment gap against a channel’s required attribute set surfaces as an alert to the owner before the product reaches syndication
When a steward changes roles or leaves, the system flags the orphaned records and the ownership gap gets resolved before it produces downstream problems
None of these require an extraordinary governance programme. They require the ownership decisions made during the governance initiative to be translated into system logic rather than left in a document.
That translation is the work that most organisations defer, or never resource, because it comes after the initiative closes and the governance project has already been declared complete.
The Question Worth Asking About Your Current Ownership Structure
Before the next governance initiative adds more names to an ownership matrix, one question is worth sitting with.
For each named data steward in your governance framework, can you point to a specific system step, workflow trigger, or approval checkpoint that makes their ownership operational? Or does their responsibility exist primarily in the documentation?
If the answer is documentation for most of them, the ownership structure is more complete on paper than it is in the systems where product data actually gets created, updated, and submitted.
That gap is not resolved by adding more stewards or running clearer workshops. It is resolved by connecting the ownership decisions the governance initiative made to the operational environment those decisions were meant to govern.
If the patterns feel familiar, the starting point is usually not a new ownership framework. It is understanding where the existing one stops influencing what actually happens to the data.
That is the gap ThoughtSpark helps enterprise data and commerce teams identify and address: the distance between ownership as it was assigned and accountability as it needs to operate.
If you have ever pulled a product readiness report ten days before a major launch and discovered the data is not where it needs to be, you would find this blog insightful.
Forty percent of SKUs with attribute gaps. Three new product subcategories created during the past quarter are classified differently across the PIM, the ERP, and the commerce system. The digital team is using one taxonomy value while the merchandising team is using another, and neither matches what two of the retailers require in their submission templates.
The next ten days get spent correcting this manually. A spreadsheet appears. Teams work through it in parallel, overwriting each other’s corrections without realising it. The launch happens, probably on time, with most of the data close enough to pass.
And somewhere in the back of most people’s minds is the same quiet thought: we already fixed this.
Most organisations that experience this pattern have run a governance initiative at some point. They aligned on taxonomy, defined ownership, and built the framework. The work was real.
This pattern tends to repeat because of a structural gap between what governance initiatives are designed to deliver and what sustained product data quality actually requires. Understanding that gap, and where it shows up most in day-to-day operations, is what we have highlighted ahead.
Why Product Data Problems Persist After Governance Initiatives End
A governance initiative has a defined lifecycle. A working group forms, workshops run, a framework gets produced, and leadership signs off. The project closes.
The operational environment the framework was meant to govern keeps running.
New products enter the catalogue, retailer requirements shift, and channels expand. Suppliers send data in formats that sit outside the agreed taxonomy. Someone in the regional team creates a product classification that fits the submission deadline better than the approved option does. These situations arise constantly, in every commerce organisation, at a pace the governance project never accounted for.
This is not an unusual outcome. Gartner projects that 80% of data and analytics governance initiatives will fail by 2027. The explanations that come up most often, including executive sponsorship, change management, and organisational silos, point at real contributing factors, though they tend to describe what happens rather than why it keeps happening.
Governance initiatives produce outputs:
A taxonomy framework
A data ownership model
Quality standards
A stewardship structure
These outputs are produced in a project environment, during a defined period, with stakeholders engaged specifically for that purpose. When the project ends, the outputs exist. The operational environment continues on its own terms.
The Gap Between What a Governance Initiative Delivers and What It Changes Operationally
What Governance Initiatives Typically Produce
A governance initiative produces tangible, valuable outputs:
A taxonomy document with agreed classifications
An ownership matrix with named stewards and defined scope
A data dictionary establishing shared definitions
Quality thresholds for completeness and accuracy
A process for escalating and resolving data conflicts
Getting to these outputs requires genuine work. The conversations involved, about ownership, classification standards, and quality definitions, are difficult to have in most organisations. The initiative produced something meaningful.
The harder question is whether any of it changed how product data gets created and maintained once the project team dispersed.
Why Operational Workflows Continue Unchanged After Governance Projects
Here is what tends to happen in practice:
The product manager creating a new record in the PIM selects a category based on what looks right, working from memory or habit
Supplier data arriving through the portal moves into the system before anyone checks it against the quality thresholds
The merchandising team building a seasonal catalogue creates new attribute values for a promotional range without a stewardship review
None of this reflects carelessness. People operate at the speed the commercial calendar demands. A governance document sitting in a shared folder, rather than embedded in the system as a validation rule, a required field, or a workflow step, becomes something teams consult in a crisis rather than something shaping daily decisions.
The framework was delivered and the workflows continued as before. That distance between the two is where product data problems find room to grow back.
Why Taxonomy Drift Keeps Returning After Data Governance Cleanup
When taxonomy drift reappears after a governance initiative, the instinct is often to treat it as a compliance failure. The standard was set. Teams moved away from it.
Drift builds through individually rational decisions made under operational pressure:
A product manager receives a new range from a supplier that sits outside the existing category structure. They find the closest fit or create something workable for the submission.
A regional team faces a retailer requiring a classification their internal taxonomy does not support. They build a local solution that gets the feed accepted.
A campaign goes live using attribute tags the approved taxonomy was too broad to accommodate. Someone creates what the promotion requires.
In each situation, the person made a reasonable call given what the governance standard had not anticipated.
Over time, these decisions layer on top of each other. The taxonomy develops inconsistencies that look systematic on audit, though they arrived one reasonable decision at a time.
The governance framework captured the data environment as it existed during the project. The business kept generating complexity the model never anticipated. Drift is the natural result of that distance.
Why Governance Initiatives Are Designed to End When Data Quality Problems Are Not
Research from Harvard Business Review and Bain, published in 2024, found that only 12% of large-scale transformation programmes produce lasting results. That figure has remained flat for two decades. The organisations that do sustain meaningful change share a common practice: they treat the change as continuous and embedded into how the organisation operates, rather than as a programme with a defined scope and completion date. For product data governance, that distinction matters considerably. An initiative that produces a framework and closes is structurally different from a discipline that operates continuously alongside the business.
Governance initiatives are almost universally designed as projects. There is a budget, a timeline, a set of deliverables, and a point at which success gets declared. Success is measured against delivery of the output, rather than against whether that output influenced operational behaviour six months later.
This pattern shows up consistently at scale. In McKinsey’s research on operating model transformations, leaders describe programmes that became “marginalised into something that has barely affected how the company operates.” The programmes hit their milestones. The operational reality they were meant to address stayed largely the same.
For product data governance, the challenge goes a layer deeper. Data quality requires continuous maintenance against real operational conditions:
New products added to the catalogue without complete enrichment
New channels with attribute requirements the existing data does not meet
Supplier data arriving in inconsistent formats
Team members making data decisions without full awareness of the governance standards
A framework addresses the data as it existed when the project ran. Most organisations invest in building the framework and expect the results that only an ongoing operational discipline can sustain.
What Organisations With Sustained Product Data Quality Do Differently
Organisations where product data governance holds over time tend to share one observable characteristic. It is less about the sophistication of the framework they designed and more about where that framework sits relative to daily operational decisions.
In practice, embedded governance tends to look like:
The taxonomy is a controlled vocabulary field in the PIM. Product managers select from approved classifications rather than entering free text, so the standard applies without requiring active recall of a document.
The attribute standard lives as a validation rule. Records with incomplete fields get flagged before activation, so quality issues surface at the point of creation rather than at the point of submission.
Data ownership is a workflow step. Before a record in a given category goes live, a review is triggered automatically, making stewardship part of the process rather than an optional escalation.
When governance is built into the system this way, operational behaviour shifts because the system shifts. A product manager joining six months after the initiative closed follows the governance standard without knowing it came from an initiative. The fields the system requires do the work.
Embedding the framework into the operational environment is the work that follows the initiative, and it rarely receives the same investment because by the time it matters most, the initiative has already closed.
The Question to Ask Before Launching Another Product Data Governance Initiative
Before scoping the next governance programme, one question is worth sitting with.
If the framework produced by the last governance initiative were removed tomorrow, the documents archived and the stewardship roles dissolved, would the operational behaviour of your product, commerce, and data teams change in any meaningful way?
If the answer is yes:
The governance has become embedded in how the work gets done
The taxonomy holds because the system enforces it
Ownership has real operational weight because the workflow requires it
If the answer is no:
The governance lives primarily in documentation
Operational decisions are being shaped by deadline pressure and team habits more than by the standards the initiative established
The next launch will likely surface the same gaps as the last
Organisations running governance programmes periodically and rediscovering the same taxonomy drift and enrichment gaps and ownership confusion each time are usually already aware of this, at least in private. The initiative was executed well. The governance held for a period. Then the operational environment kept moving and the framework stayed where it was.
The organisations that make progress are usually the ones that stopped treating governance as a separate initiative and started building the actual standards into how product data gets created, reviewed, and updated every day.
If the patterns feel familiar, the starting point is usually not another governance initiative. It is understanding where the existing framework stops influencing day-to-day decisions and where operational teams have been forced to work around it.
That is the gap ThoughtSpark helps enterprise data and commerce teams identify and address: the distance between governance as it was designed and governance as it actually operates.