Scope an AI Problem Before Any Data Work Starts

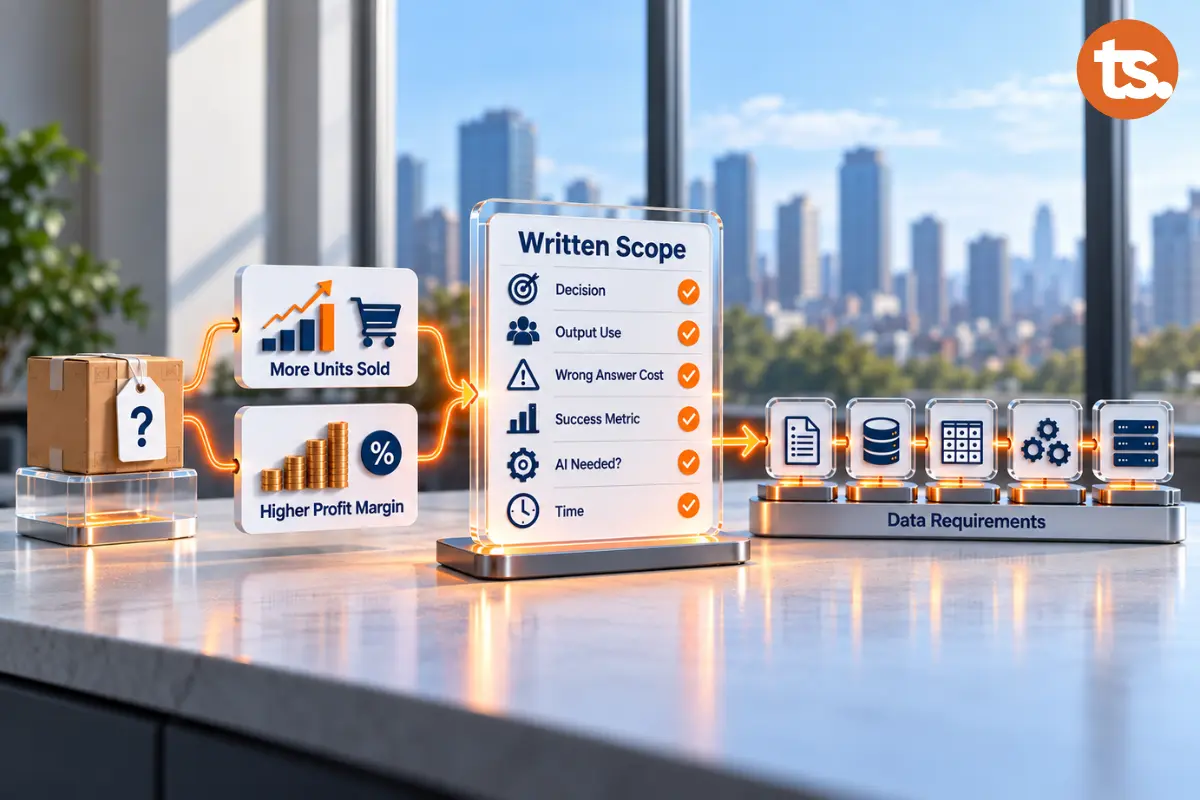
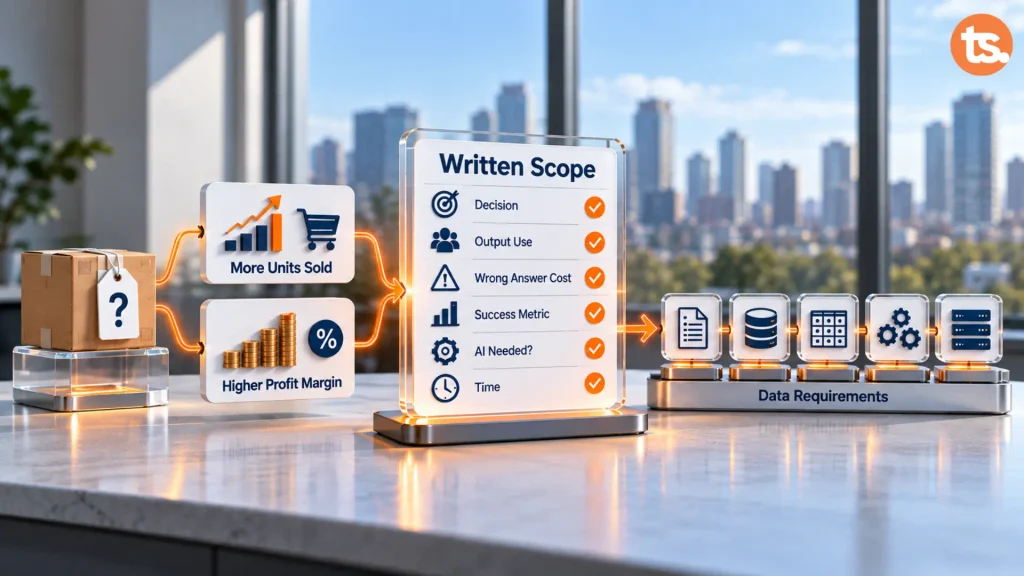
Diagram showing how to scope an AI problem, from a vague product request to a six-part written scope and its data requirements.

A business leader asks the data team for a model that sets the right price for a product. The team builds a model that finds the price that sells the most items, delivers it on schedule, and confirms that it performs exactly as designed. The leader wants the price that earns the greatest profit margin, so the model answers a question that nobody needed answered.

That example comes from RAND’s study of failed AI projects, which draws on interviews with experienced data scientists and engineers, and it shows the pattern at its simplest. The request means one thing to the person who makes it and another to the person who builds it, and nobody finds out until the work is finished. A short written scope, agreed in one working session before any data work begins, closes that gap. It also produces the list of data requirements that every later decision depends on.

In Brief

  • A written AI scope is a one-page statement, agreed by the business owner and the technical lead, that fixes what the model decides, who uses its output, and how success is measured.
  • RAND’s research ranks miscommunication about a project’s purpose above every other cause of AI project failure.
  • The scope has six parts: the decision, the use of the output, the cost of a wrong answer, the success metric, whether AI is needed at all, and the time commitment.
  • The scoping session follows a set order and ends with a signed one-page scope, which the team reviews whenever priorities or data change.
  • Each part implies data requirements, and the team assesses the data against those requirements.
  • A scope is ready when the business owner and the technical lead, asked separately, describe the same model.

Why AI Scoping Comes Before Data Work

Data work is the most visible and most expensive part of an AI initiative, which is where teams naturally start. Cleaning, integrating, and labeling data all feel like progress, and all of them pay off only if the model they feed answers the right question.

RAND interviewed 65 experienced data scientists and engineers about why AI projects fail, and its authors conclude that misunderstandings and miscommunications about the intent and purpose of a project cause more AI projects to fail than any other factor. The study’s recommendation for business leaders is specific. They need to help technical staff understand what the project must achieve and how the finished product will be used, because they cannot assume the engineering team will discover on its own which design choices make the product useful in its business context.

A scope is the written form of that explanation. It is a statement of the problem the model solves, short enough to fit on one page and specific enough that two people reading it separately would describe the same model. Without one, teams spend a data budget against a problem nobody has defined, which is the precondition failure that sits upstream of every data readiness decision.

Who Needs to Attend an AI Scoping Session

A scope written by one person is a guess. The session works because four perspectives meet in the same room, and each one holds information that the others lack.

  • The business owner is accountable for the result and can say what the business actually needs from the model.
  • The technical lead is the data scientist or machine learning engineer who will build the model, translates the request into what can be built, and flags what cannot.
  • The person who acts on the output is the dispatcher, analyst, or agent whose daily work changes when the model gives an answer, and who knows how the output would really be used.
  • The data owner knows where the relevant data lives and who maintains it, and can say early whether the data exists at all.

RAND notes that leaders can do without deep technical knowledge of AI themselves as long as they employ staff with a strong data science background when selecting objectives for AI product teams. That is why the technical lead sits in the room while the objective is still being shaped.

The aim is a single working session. When the group cannot agree on the decision or the metric during the session, that disagreement is the most useful finding it produces, because it would otherwise surface much later and at a much higher cost.

The Six Parts of a Written AI Scope

A written scope has six parts. Each part has an answer of a few sentences in plain business language, and a part that nobody can answer marks the work that remains before data work should begin.

The Decision the Model Informs

The first part names the specific decision that changes because the model exists. A usable statement sounds like “release a shipment as planned or hold it for document review”, and an unusable one sounds like “improve logistics performance”. The decision needs a moment when it is made and a person who makes it, because a model without a named decision has no job to do.

The opening pricing example shows why this part comes first. A request for “a model that sets the price” hides a choice between maximizing volume and maximizing margin, and naming the decision forces that choice into the open before anyone builds anything.

How the Output Gets Used

The second part describes where the model’s output appears, who sees it, what they do differently because of it, and what happens when they ignore it. RAND places this on the business leader, who needs to explain how the completed product will be used and cannot assume the engineering team will work it out.

This part also states the value pathway, which is the route by which the output turns into higher revenue or lower expense. A May 2026 MIT Sloan article on research from its Center for Information Systems Research names launching projects without clear value pathways as one of five common mistakes in AI initiatives. A model whose output reaches nobody who can act on it has no pathway, however accurate it is.

The Cost of a Wrong Answer

Every model gives wrong answers some of the time, because AI algorithms are inherently probabilistic. RAND’s interviewees point to the inflated expectations that senior leaders hold about what AI can achieve, often driven by hype, as a recurring cause of failure. The third part states what a wrong answer costs in each direction. A model can say yes when the answer is no, or no when the answer is yes, and the two errors rarely cost the same.

Writing both costs down in business terms decides how the model is tuned and which success metric fits. It also gives the person who acts on the output an honest picture of how often the model is expected to be wrong, which protects trust in the model on the first day it makes a visible mistake.

The Success Metric in Business and Model Terms

The fourth part defines success twice, once in the language of the business and once in the language of the model. RAND describes failed projects in which business leadership did not realize that the metrics measuring the success of the AI model did not represent the metrics of success for its intended purpose, and the opening pricing example is the plain case, where items sold stands in for profit margin.

The business owner writes the first definition, such as fewer shipments held up at the border each month. The technical lead writes the second, naming the model measurement that approximates it, and states the conditions under which the two diverge. Both people sign both lines, so a good model score is never reported as business success without the link between the two being visible.

Whether the Problem Needs AI at All

The fifth part tests whether a simpler tool already answers the decision. RAND reports interviewees who received instructions to apply AI to datasets with a handful of dominant patterns that a few if-then rules could have captured quickly.

If a rule or a standing report answers the decision acceptably, the team builds the rule and stops there. If the rule answers it only partly, the rule becomes the baseline that any model must beat to justify its cost, and for problems whose data is still being captured it can serve as the first stage of a staged build, an approach in which a rule runs first and a trained model replaces it as the data accumulates.

The Time Commitment for an AI Problem

The sixth part states how long the organization commits to the problem and who funds it for that period. RAND reports that leaders underestimate the time and cost of acquiring, cleaning, and exploring data, and that shifting priorities lead to projects being abandoned before they can show results. Its recommendation is that leaders be prepared to commit each product team to a specific problem for at least a year, and that a problem unworthy of that commitment is probably not worth pursuing at all.

A problem whose data has not been captured yet takes longer to reach a trained model, and the written commitment is what keeps that effort from being cut short when priorities shift.

How to Run an AI Scoping Session

A scoping session has three stages, and the preparation and the sign-off matter as much as the meeting itself.

What to Prepare Before the Session

Preparation is what makes one working session enough.

  • Send the original request, in the words it was first made, to all four attendees.
  • Ask each attendee to write down, separately, the decision the model should change and how they expect its output to be used. The differences between those answers become the agenda.
  • Ask the data owner to list the systems that might hold the data the decision depends on, without judging its quality.

The Order to Work Through the Six Parts

The parts build on each other, so the order matters.

  1. The decision comes first, because every other part depends on it.
  2. The use of the output comes second, because it shows whether the decision can actually change.
  3. The cost of a wrong answer comes third, because it sets what the success metric must protect.
  4. The success metric comes fourth, because it can only be chosen sensibly once the cost is in view.
  5. Whether AI is needed comes fifth, because it can only be judged once the decision, the use, and the metric are clear.
  6. The time commitment comes last, because it depends on everything above, including how much data the problem needs.

After each part, the technical lead restates the answer in their own words and the business owner confirms or corrects it. A misunderstanding corrected in the room costs little, and the same misunderstanding found during the build costs far more. When the two versions of an answer differ, the group records both and resolves the difference before moving on, with the business owner holding the final word on what the business needs and the technical lead holding the final word on what can be built.

Signing Off the Scope

One attendee writes up the scope on the template below soon after the session, and the business owner and the technical lead each confirm it in writing. The signed scope then lives where the build team works, and it becomes the reference for every later question about what the model is for.

A One-Page AI Scope Template

The template holds the six parts, the data requirements that follow from them, and the sign-off.

  • Decision. The decision that changes, who makes it, and when.
  • Use of the output. Where the output appears, who sees it, what they do differently, and what happens if they ignore it.
  • Cost of a wrong answer. The cost if the model says yes and is wrong, the cost if it says no and is wrong, and which one is worse.
  • Success metric. The business definition, the model measurement that approximates it, and the conditions under which the two diverge.
  • Simple alternative. The rule or report tried or ruled out, and the baseline the model must beat.
  • Time commitment. How long the organization commits, who funds it, and the dates when the scope is reviewed.
  • Data requirements. The inputs, the outcome records, the delivery needs, the quality priorities, and the history required.
  • Sign-off. The business owner, the technical lead, and the date.

Turning an AI Scope Into Data Requirements

Once the six parts are written, each one implies something about the data. Working through them in order produces the list of requirements that a data team can act on.

  1. The decision defines the inputs. The model can only use facts that are available at the moment the decision is made, so the scope lists what the decision maker could know at that point.
  2. The success metric defines the outcome records. Measuring success requires a record of what actually happened after each decision, such as whether a shipment was delayed.
  3. The use of the output defines freshness and delivery. It sets how quickly the output must reach the person and how current the inputs must be for the output to be useful.
  4. The cost of a wrong answer defines where data quality matters most. Errors in the fields that drive the costliest mistakes matter more than errors elsewhere.
  5. The time commitment defines how much history is available. It also shows how much must still be collected.

The team assesses the data against that list. The case for assessing readiness against a specific initiative depends on someone having stated what the initiative needs, and the scope is the document that states it. The assessment itself starts with the six-question diagnostic that separates data quality from data availability. A quality finding leads to scoping a data quality fix to the use case, and an availability finding leads to a staged build around new data capture.

A Worked Example of Scoping a Customs Delay Model

A logistics company that appears in the quality versus availability diagnostic and in the staged build example shows the whole sequence. Its operations leadership wants AI that forecasts which shipments will face customs delays before they are dispatched, and the first request in the room is “a model that predicts customs delays”. The scoping session turns that request into six answers.

  1. The decision. Whether the customs desk releases a shipment as planned or holds it for extra document review before it leaves. The customs desk makes the decision at dispatch.
  2. The use of the output. The model’s score appears next to each shipment in the dispatch queue, and the customs desk reviews flagged shipments before they go out. The dispatch coordinator points out that a flag with no reason attached will be ignored, so the scope requires each flag to show the shipment attribute that drove it.
  3. The cost of a wrong answer. A missed delay leaves a shipment stuck at the border with a customer waiting. A false flag sends a shipment to extra review, which costs desk time and can delay a shipment that would have cleared. The group decides that missed delays hurt more, so the team tunes the model to flag generously, with desk capacity as the limit.
  4. The success metric. The business owner defines success as fewer shipments held up at customs each month among those dispatched. The technical lead names the model measurement, how well flagged shipments match the delayed ones, and records that it approximates the business outcome only while the desk has the capacity to review every flag.
  5. Whether AI is needed. A rule that flags routes with a history of delays exists today. The group agrees that this rule is the baseline the model must beat.
  6. The time commitment. The group commits to the problem for at least a year, because the model needs examples of delayed shipments to learn from, and those examples accumulate at the pace shipments are delayed.

Applying the requirements list to this scope gives the data team five requirements.

  • Inputs before dispatch. Route, shipment volumes, and the customs documentation that accompanies each shipment.
  • Outcome records. Whether each shipment was delayed at customs.
  • Delivery. A score and a reason visible in the dispatch queue before the shipment leaves.
  • Quality priorities. The customs documentation field and the delay outcome matter most, because a wrong or missing value in either one corrupts the examples the model learns from.
  • History. Enough delayed-shipment examples to train and evaluate a model, collected over the committed period.

Running the diagnostic against these requirements gives a clear result. The company holds years of clean data on volumes, routes, and delivery times, and it holds no record of customs documentation, because that information was never required before. The data does not exist, which makes this an availability-bottlenecked problem and points to a staged build around new data capture.

The scope does two jobs at once. It stops the team from building a general delay predictor that nobody at dispatch would use, and it exposes the data gap before anyone spends money on cleaning data that was never the constraint.

Keeping an AI Scope Current

A scope that the team writes once and files loses its value, because the problem, the priorities, and the data all change after the session, so four events call for a review.

  • Each gate in a staged build. A gate is the checkpoint where the team decides whether to move to the next stage, and the team rereads the scope at each one to confirm that the decision, the use of the output, and the success metric still hold.
  • A shift in priorities. RAND reports that rapidly shifting priorities lead to projects being discarded before they can show results, and to finished projects being ignored because they no longer address what leadership considers most important. A written scope makes the shift visible, because the business owner must either update the scope and the commitment or end the project on purpose.
  • A change in what the data allows. A missing field or an unreliable source discovered during the build is a reason to revise the scope, and a scope revised in the open keeps both sides describing the same model.
  • A sponsor who is hard to reach. RAND describes failed projects in which business leadership does not make itself available to discuss whether the technical team’s choices match its intent, and it advises technical teams to keep business stakeholders informed of progress and interim discoveries. The scope names the business owner as the person who answers, and its review dates are calendar commitments for that person.

Signs an AI Scope Is Not Ready

Any one of the following means the session is not finished, and data spending should wait.

  • The business owner and the technical lead describe the decision differently when asked separately.
  • The success metric exists only as a model measurement, with no business outcome attached to it.
  • Nobody who acts on the output has been consulted.
  • Nobody can say what a wrong answer costs in either direction.
  • A simple rule has been neither tried nor ruled out.
  • The project exists because a technology is available, and the team searches for a problem to fit it.
  • The commitment ends before the data collection does.

The simplest final check is to ask the business owner and the technical lead to describe the model independently, in writing. Matching descriptions mean the scope is ready, and differences mark exactly where the next conversation should happen.

Key Takeaways

  • Hold the scoping session before any data cleaning, integration, or labeling budget is committed.
  • Put the business owner, the technical lead, the person who acts on the output, and the data owner in the same room.
  • Prepare in writing, work through the six parts in order, and sign off a one-page scope.
  • Build the simple rule first when one answers the decision, and make the model beat it.
  • Derive the data requirements from the scope, then run the quality versus availability diagnostic against them.
  • Review the scope at every gate and whenever priorities or data change.
How to Stage an AI Build Around New Data Capture

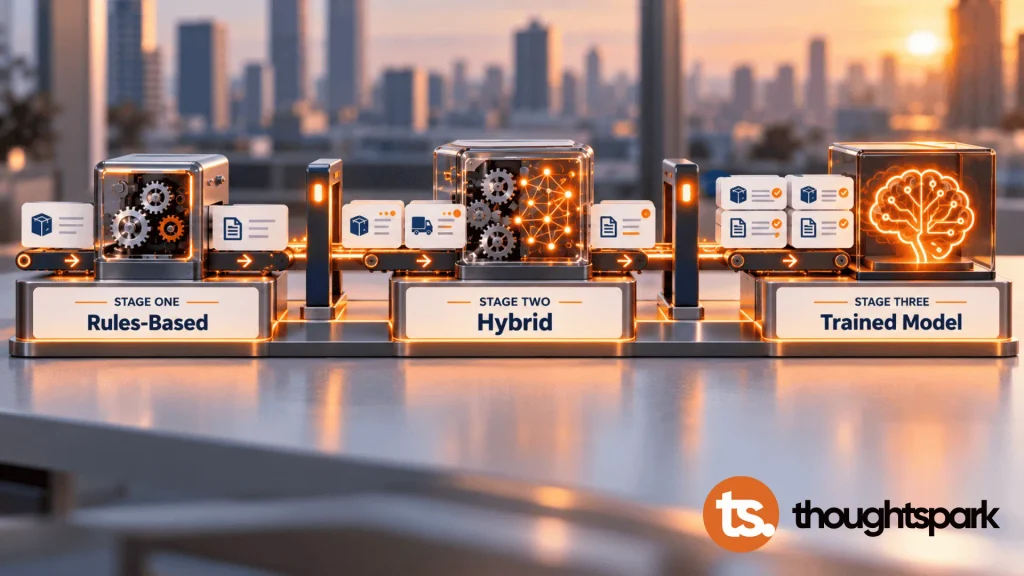
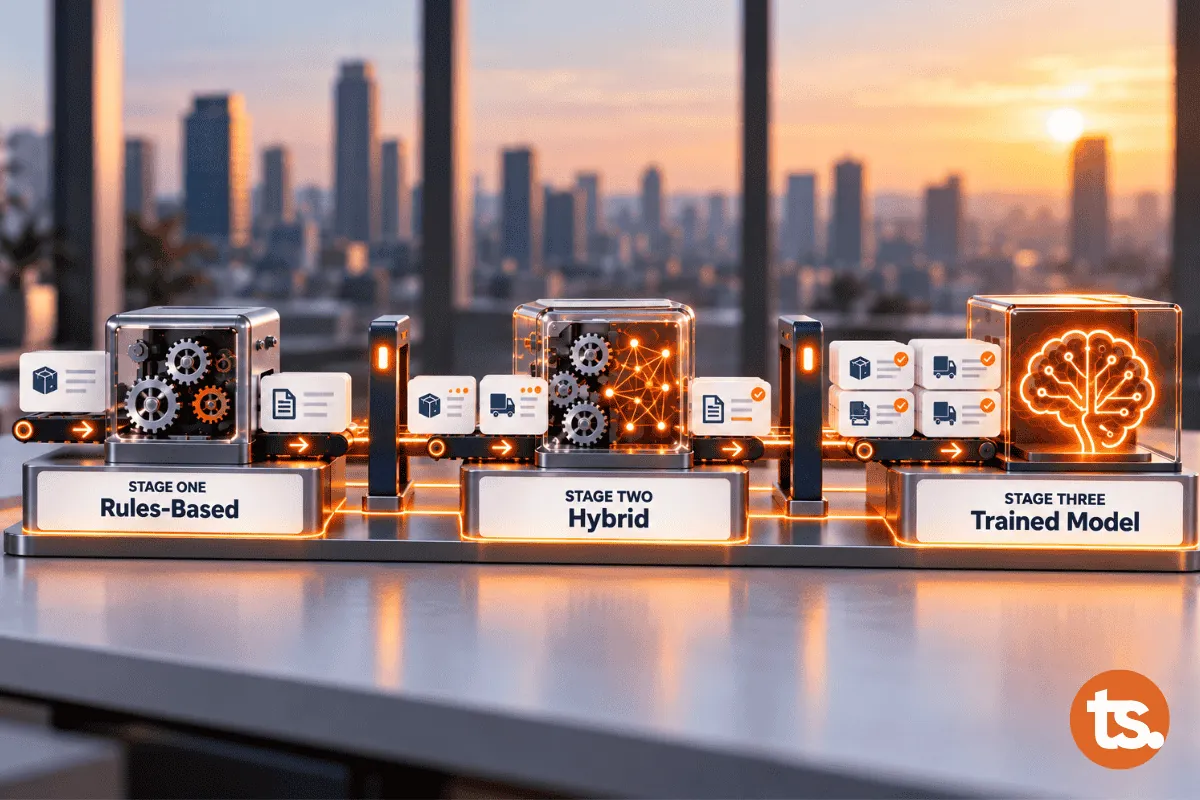
Three connected stages showing an AI build moving from a rules based system to a hybrid model to a fully trained model, with data cards increasing across each stage and gates marking the checkpoints between them.

If the data your AI initiative depends on has never been captured, how do you move the initiative forward? One answer is to wait until the data exists, which stalls the initiative for as long as that takes. The other is to build against a hand-prepared sample in place of the missing data, which produces a model that looks fine in testing and struggles on live records.

A staged build is a third option, and it works in three steps:

  1. Start capturing the missing data now.
  2. Launch a simple rules-based version using the data the organization already has. It follows fixed rules, such as flagging any route that has had delays before, so it does not need the new data.
  3. Launch an AI model trained on the new data once enough of it has been collected, then widen what the model covers as more data arrives.

The team agrees in advance what counts as enough, as a set of conditions that together form a gate.

Staging is worthwhile because this kind of data cannot be collected faster than the business produces it. A supplier’s lead-time history, a season of returns, or a quarter of customs outcomes each grows one record at a time, and no budget speeds that up.

This is why capture should start as early as possible: every day capture waits is a day of history the model never gets to learn from.

In Brief

  • Staging applies when the needed data is not being captured today. Data that existed once and has since disappeared is a recovery job.
  • The length of the wait depends on how often the outcome you want to predict occurs.
  • Capture starts with a one-page specification that lists each field, its source, its trigger, its format, and a coverage target.
  • Staging fits predictive use cases that learn from history. A generative use case needs the gap captured and does not need a history of outcomes.


Why Data You Are Not Yet Capturing Takes Time to Accumulate

Once capture is running, the data grows at a pace with two inputs. The first is how often the relevant events happen: shipments cleared, returns processed, deliveries received. The second is the share of those events the capture actually records. For illustration, a business that clears a thousand shipments a month with capture covering half of them gains five hundred usable records a month, and coverage is the input the team can raise.

Google’s own engineering guidance on machine learning advises starting early for this reason: track as much as possible in the current system before the machine learning system is formalized, since historical data on anything that might matter later is better collected now.

That makes the missing data a quantity that grows at a rate the team can estimate, and a quantity can be planned around in a way a yes-or-no condition cannot.

When Staging an AI Build Is the Right Approach

That growing-quantity view applies to one specific kind of gap: the data the use case needs is not recorded anywhere today, usually because nobody needed it until the AI initiative came along.

Data that exists but conflicts across systems is a quality problem with its own fix, and data that existed once and has since disappeared is a recovery job. Six diagnostic questions tell these cases apart, and a “never tracked” answer is what points here.

Staging fits predictive use cases, where a model learns from history to forecast a delay or score a risk, because that history has to accumulate. A generative use that reads attributes at the moment it answers needs the missing information captured for the records it reads. It does not need a history of past outcomes to learn from.

Take a logistics company that wants a model to predict which shipments will face customs delays. It holds years of clean data on volumes, routes, and delivery times, and it has never recorded which customs documentation goes with which shipment.

Working Out How Much Data the Use Case Needs

For that company, and for any use case in this position, the first task is defining what enough data looks like, since every later decision depends on it: what to record, when a stage is ready, and what to tell the business.

Which Attributes the Model Needs

Start from the decision the model will make and list what a person making that decision by hand would look at. Each item that is not already recorded becomes an attribute to capture.

In the logistics example, the model needs to know which documents accompany a shipment and when they were submitted. Suppose the outcome it predicts, whether a shipment faced a customs delay, can be read from delivery records the company already holds. That leaves the documentation as the missing piece.

How Much History the Use Case Needs

History length depends on how much the pattern changes across the year. If shipments behave differently in a peak season, a model trained only on quiet months has never seen the pattern it will be asked to handle, so the plan has to include a stretch of history that covers it. Ask the business which cycles matter for this use case, and treat the answer as a minimum.

How Many Examples of the Rarest Outcome You Need

What limits the model is the count of the outcome you want to predict. Each record whose outcome is known, such as a shipment marked delayed or on time, is a labeled example, and most records show the normal case. Only the rare outcomes show the model what it needs to learn.

MIT Sloan Management Review describes the same limit in its discussion of scarce data: when an outcome is uncommon, such as a rare cardiac event or defects from a factory that has produced few of them, labeled examples are few and cannot be increased on demand.

Your data science team can estimate how many examples of the rarest outcome the model needs. Divide that estimate by the number of usable examples of that outcome you expect to capture each month, and the result is a first read of how many months the wait runs, which you revise as real capture rates come in.

What Can Shorten the Wait and What Cannot

Data-efficient techniques, such as starting from a pretrained model (one already trained on a large body of similar data), can reduce how many labeled examples a model needs. The MIT Sloan Management Review article describes cases where a fraction of the usual number is enough. These techniques address a shortage of labels.

A field the organization never recorded is a missing input, and no technique supplies an input nobody wrote down. The article does not discuss inputs that were never recorded, so this limit is our own reading. It has a planning consequence: a pretrained model may shorten how long the outcomes take to accumulate, and capture still has to start on the same day.

Start Data Capture Before the AI Build Starts

Capture goes first because it sets the schedule, and a simple capture that starts now gives the eventual model more history than a thorough one that starts a quarter later. The team’s first deliverable is a capture specification, one page that says what gets recorded and how you will know it is working:

  • Field: each attribute the use case needs, taken from the attribute list above.
  • Source: the system, or the person at the moment of the work, where the value is first known.
  • Trigger: the event that causes the record to be written.
  • Format: a controlled set of values, so records can be compared months later.
  • Coverage target: the share of relevant events that must carry the field before it counts as usable.

Two design choices decide whether the captured data is usable:

  • Record the cases that seem easy to skip. Google’s guide describes logging only what a user saw, which leaves no examples of what was not seen. The same trap applies when documentation is recorded for delayed shipments and skipped for the ones that cleared.
  • Record at the point of the work. A value entered from memory a week later can carry errors the model then learns from.

Coverage needs watching once capture is running, since it can fall without any alarm. Google’s guide notes that a feature populated in most examples can drop sharply after an implementation change and go unnoticed, so a coverage figure reported on a set schedule belongs on the same page as the specification.

Staging an AI Build From a Rules-Based Version to a Trained Model

With capture running, the build itself proceeds in three stages. Capture and the build run at the same time, as our data readiness and AI sequencing guide recommends, and the release is staged, so the model at full scope goes live last.

A Rules-Based or Human-Assisted First Version

The first stage is a rules-based or human-assisted version that uses only the data the organization already holds. In the logistics example, a simple rule flags shipments on routes with prior delays, and a person reviews each flag before anything happens. Google’s guide is direct that machine learning requires data, and that a simple rule, or even human editing, can get a product out the door until that data exists.

This stage earns its place in three ways:

  • It gives the business something usable early.
  • It sets the baseline every later model has to beat.
  • Each reviewed flag, together with what happens to that shipment afterward, adds a labeled example the model will later learn from.

The value of this stage depends on the review being genuine, since checkpoints that handle more items than a person can examine become a formality.

A Simple Model Sized to the Data

The second stage introduces a trained model once the gate in the next section is met. Google’s guidance recommends a simple first model and a solid pipeline around it, and it links the complexity a model can support to how much data is available. A few carefully chosen attributes on a modest dataset are a sound start, and the rules-based version keeps running as the fallback and the baseline.

Wider Scope Once Coverage Holds

The third stage widens the scope as coverage holds: more attributes, more routes or product lines, and more automation of the decisions a person reviewed.

Where the model makes its errors, capture more examples from those areas first. The MIT Sloan Management Review article recommends this targeted approach, since errors tend to cluster in particular regions of the data. If the errors point to an attribute the model lacks, that attribute joins the capture specification, and each widening has to pass a gate again.

The Gates That Decide When to Move to the Next Stage

A gate is three conditions that must all hold. The same three apply before the trained model goes live and again before each widening.

Coverage, Volume, and a Test on Newer Records

  • Coverage: the capture specification’s target is met, and the figure has held there for a stretch you agree in advance.
  • Volume: the count of the rarest outcome reaches the estimate from the earlier section, revised with real capture rates.
  • A test on newer records: a model trained on records up to a chosen date is tested on records captured after it, and it has to beat the rules-based baseline on those newer records. Google’s guide recommends testing this way because it better reflects what happens in production. Testing only on hand-prepared samples can make a model look fine and then fail on live records.

What to Commit to on the Timeline

When the business asks for a date, the answer has two parts:

  • Dates for what you control: the day capture starts and the day the rules-based first version goes live.
  • Gates, with a forecast range, for what the data controls: build the range from the estimate of examples needed divided by the usable examples captured each month, and revise it monthly against actual capture.

Leadership gets firm dates for the parts within your control and a forecast that sharpens each month for the rest.

What Happens If a Gate Is Not Met

Sometimes a gate stays closed longer than the forecast. Three responses are available, and the right one depends on why:

  • Stay at the current stage. The rules-based version keeps delivering as the data builds, and nothing has to be withdrawn.
  • Widen the capture. If coverage is the problem, add sources or events to the specification. If volume is the problem, look for more places the outcome is recorded.
  • Narrow the use case. Scope the model to the routes or segments where the data is already sufficient.

Occasionally the outcome is too rare for a trained model to reach the volume it needs in any useful time. In that case the rules-based version may be the finished product, and Google’s guide says a team should choose the simple rule when it does better than the model on the metrics that matter.

A Worked Example of Staging a Customs Delay Model

Take the logistics company from earlier. The sequence starts with a definition of how much data is enough. The model needs the documents that accompany each shipment and when they were submitted, and suppose the delay outcome can be read from existing delivery records.

In this example customs delays are the uncommon case, so the count of delayed shipments sets the pace. The data science team estimates how many delayed shipments the model needs and divides by the number of usable delayed-shipment examples expected each month, which gives a forecast range for the second stage.

The capture specification then reads:

  • Field: the customs documentation that accompanies each shipment.
  • Source: the customs filing step.
  • Trigger: submission of the filing.
  • Format: a controlled list of document types.
  • Coverage target: the share of shipments that must carry the field, set with the business.

It records documentation for shipments that clear without delay as well as for the delayed ones. The build then proceeds in three stages:

  1. Stage one goes live once capture is running. A rule flags shipments on routes with prior delays, using data the company already holds, and a reviewer examines each flag. The business gets usable flags, and each reviewed flag adds a labeled example once the shipment’s outcome is known.
  2. Stage two opens when coverage holds at target, the count of delayed shipments reaches the estimate, and a model trained on shipments up to a chosen date beats the rule on shipments after it. A simple model then goes live for a limited set of routes, with the rule running beside it.
  3. Stage three adds more routes and attributes, with the same gate at each step, and the model’s errors show where capture focuses next.

The message to leadership has three parts:

  • Capture starts on one date.
  • The rules-based version goes live on another date.
  • Each later stage opens when its gate does, with a forecast that sharpens each month.

If delayed shipments turn out to be too rare for the second stage to open in a useful time, the rule stays in place and the company has a working process with a growing dataset behind it. That position is stronger than a model launched early on hand-prepared samples.

When the Foundation Has to Come First

Staging suits a narrow gap, one field from one source, like the customs documentation above. A gap that needs data integrated across many systems is a different project, and the foundation comes first. McKinsey’s article on scaling AI in manufacturing describes a pharmaceutical site that first built three integrated data platforms connecting about a dozen IT systems and more than 150 sensors, and then built applications on that base.

Three signals suggest the foundation has to come first. These reflect practitioner judgment, and no published threshold backs them:

  • Capturing the field means integrating several source systems.
  • Several use cases depend on the same missing data, which makes it a platform need.
  • The new records have no shared identifier that connects them to the records the organization already holds.

If none of these apply, the staged approach fits, and the first step is the capture specification.

Key Takeaways

  • The trained model goes live when its gate is met: capture coverage at target, enough examples of the rarest outcome, and a win over the baseline on newer records.
  • A rules-based first version delivers early value, sets the baseline, and produces the labeled examples a model later learns from.
  • Testing on records captured after the training window catches what hand-prepared samples hide.
  • Commit dates to what you control, such as the capture start and the first release, and commit gates with a forecast to what the data controls.
  • A pretrained model may shorten the wait for outcomes, and capture still has to start on the same day.
  • When the missing data requires integrating many systems, the foundation comes first.

How to Scope a Data Quality Fix to a Specific AI Use Case

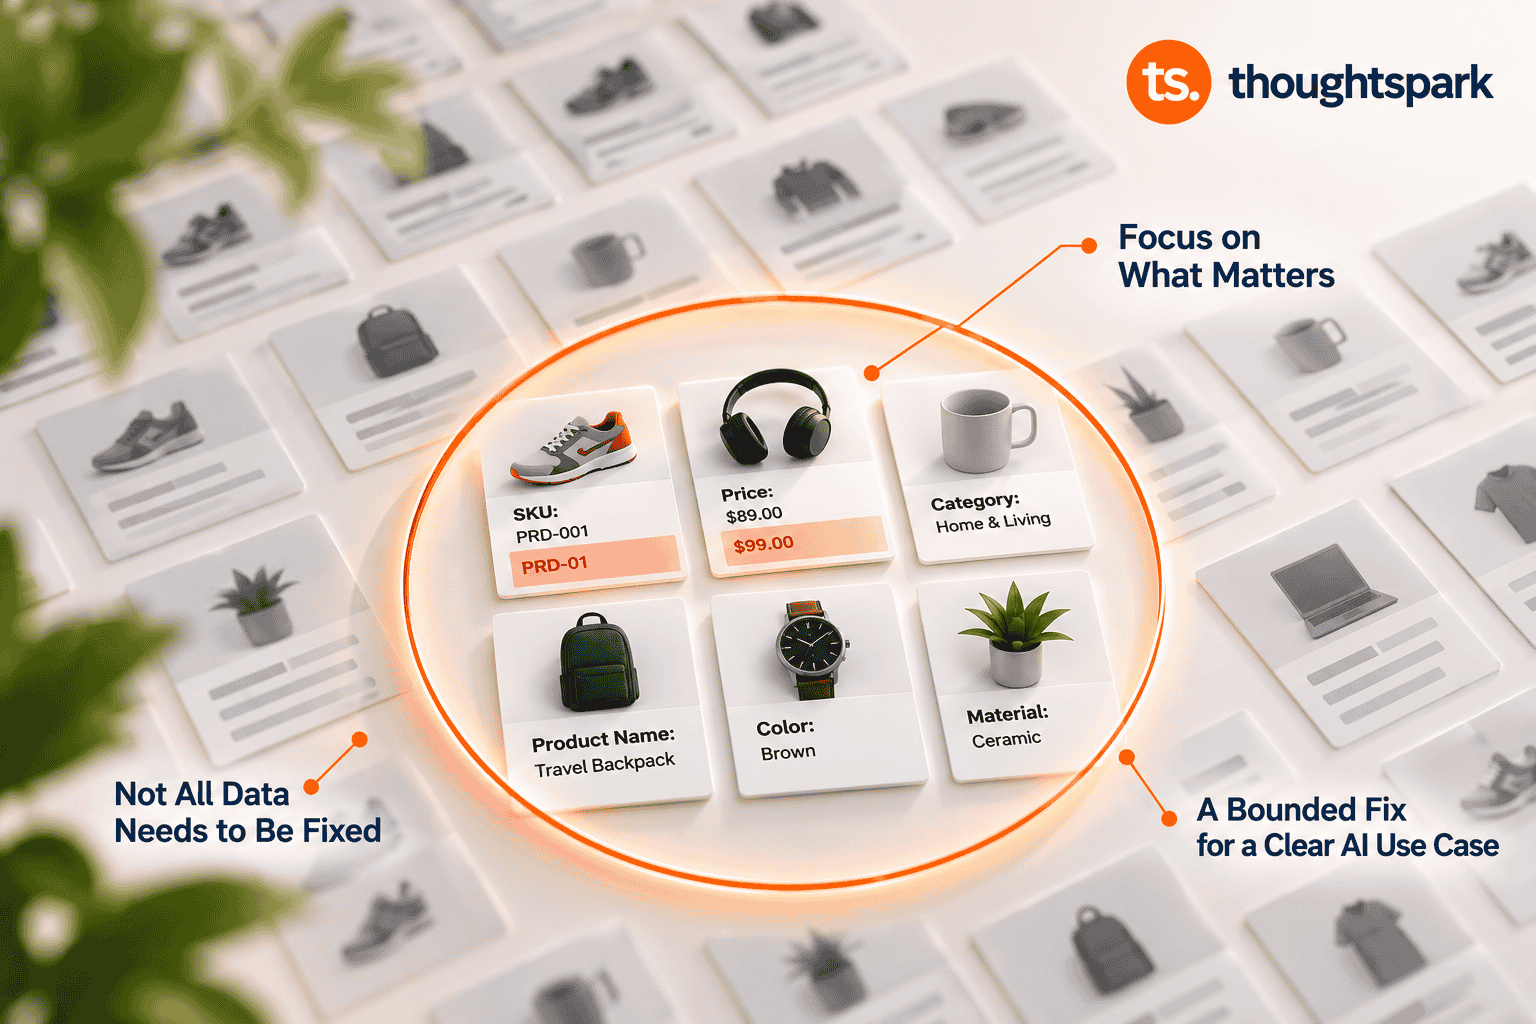
A glowing circle isolates six product data cards from a larger greyed-out set, two showing a formatting conflict in SKU and price values, with callouts reading focus on what matters and a bounded fix for a clear AI use case

Somewhere in the process of figuring out why an AI initiative is producing unreliable results, sometimes the problem narrows down to one specific type: the data it depends on exists, it is simply not accurate or consistent enough to trust yet, distinct from the other common cause, where the data needed was never captured in the first place. That distinction tells you what kind of problem you are dealing with, but it does not yet tell you which of your records actually need correcting, how far that correction has to go, or when the work is genuinely finished, and that gap is exactly where a fast, contained fix quietly turns into something much bigger than anyone planned or funded.

In Brief

  • A confirmed quality-bottleneck diagnosis names the problem. It does not scope the fix, and that is a separate decision most teams skip.
  • Gartner’s own guidance states directly that data quality efforts should never target everywhere at once, scope gets set by which specific use case actually needs it.
  • How widely a piece of data is shared across the organization, not just how broken it is, determines how large the fix should be.
  • This piece covers scoping the fix for one diagnosed AI use case specifically. A separate, larger question, building lasting organization-wide data quality, is covered elsewhere.

Why “Just Fix the Data” Is Not a Real Plan

That gap does not close itself, and it is not for lack of trying. Data and analytics leaders often reach for two familiar responses, starting with whichever records happen to look worst, or deciding the fix should touch every system that could conceivably feed the AI initiative, just to be safe. Neither response is wrong exactly, they are both just guesses standing in for a scope that was never actually set.

Gartner’s own guidance on data quality is direct about this: setting a program’s scope too wide taxes resources without producing business benefit, since not all data carries equal importance to your use case. Scoping determines whether your fix stays fast or becomes its own multi-quarter initiative, not something to settle informally before the real work starts.

Where This Fix Fits

Before scoping can start, it helps to be clear about where the diagnosis itself came from, since that shapes how much of this piece applies directly. Whether the distinction between data that exists but cannot be trusted and data that was never captured came from a structured set of diagnostic questions built for exactly this purpose, or from a different assessment entirely, a gut read, a retailer rejection that made the pattern obvious, the starting point from here is the same: a confirmed quality bottleneck, and a second question most teams skip, which of the records actually need attention, and which ones are simply sitting nearby the problem without being part of it. That second question is what this piece answers.

Why Fixing Everything Is the Wrong Default

The instinct to widen your fix comes from a reasonable place. If the customer records feeding your AI initiative are inconsistent, you can probably find that same inconsistency somewhere else in your organization too, so why not fix it everywhere while you are already looking.

That instinct produces a specific, predictable outcome: the fix stops being fundable as a fast, contained project and starts requiring the budget, timeline, and cross-functional buy-in a genuine organization-wide data quality initiative needs, the sustained, multi-year kind that changes how records get created in the first place, not just how the existing ones get corrected. Those are not the same project, and treating them as one guarantees your fast fix never actually finishes fast.

If your real goal is building lasting, organization-wide product data quality, system enforcement paired with genuine cultural ownership across every team touching the data is a real and worthwhile undertaking, and it deserves its own dedicated plan rather than becoming an accidental side effect of fixing one AI initiative’s data.

Mapping the Fix by Value and Risk

Once you decide to stay bounded to your use case, your next question is which records, inside that use case, actually need attention first, since even a scoped fix usually touches more data than you have time to fix all at once.

Gartner’s guidance gives you a direct way to sort this: map the data your use case touches along two dimensions, the value you get from getting it right, and the risk you take on from getting it wrong. A field that barely affects your model’s output but would cause real damage if wrong deserves your attention before a field that affects the output constantly but carries little consequence either way.

Applied to your quality-bottlenecked AI use case specifically, this looks like asking, for each data element your model actually consumes, what happens if this value is wrong when the model uses it. A wrong customer name might produce an awkward but harmless output. A wrong price or a wrong compliance attribute might produce a costly or even a legally risky one. Those two fields do not deserve equal priority from you, even if both currently show the same inconsistency rate.

How Widely Shared Is the Data You Are Fixing

Value and risk tell you what to prioritize, while a second question, how widely the data is actually shared, tells you how large the fix itself needs to be, a distinction Gartner draws between three categories.

Centralized Data

Shared master records used across many teams and systems fall into this category, and they hand you an inherently larger fix. Correcting centralized data well means coordinating with everyone else who also depends on that data being right, since a change made without their knowledge can break something downstream that has nothing to do with your AI initiative. This is the category that most often turns a fast fix into a slower one, not because the correction itself is harder, but because the coordination is.

Regional Data

Data shared within one business unit sits in the middle. The fix is smaller and more contained than centralized data requires, and it is usually one you can lead yourself if you already own that team’s data, without needing sign-off from stakeholders outside your immediate group.

Local Data

Data used by a single process or a single team is the smallest and fastest category to fix. One person can usually own the correction from start to finish, since nothing outside that one process depends on the data staying a particular way while the fix is underway.

If your quality-bottlenecked use case turns out to depend on centralized master data, you are looking at a genuinely bigger undertaking than one depending on a single team’s local records, even if the inconsistency itself looks identical on paper. Knowing which category you are in before you start is what keeps your estimate honest.

What the Fix Actually Involves Day to Day

With priority and scale set, the actual work in front of you is more concrete than it sounds standing outside it. Gartner’s own methodology names two practical steps worth borrowing directly: profiling and dimension selection.

Column-Based Profiling

This gives you a statistical read on the data as it currently stands, patterns of missing values, formatting inconsistencies, and outliers across a given field. It tells you what the data looks like, without necessarily telling you whether it is correct against any specific business rule.

Rule-Based Profiling

This checks your records against the specific business logic your use case actually depends on, rather than against general statistical patterns. It is usually the more useful of the two for a scoped fix, since it tests the exact thing your AI initiative needs to be true, not just whether the data looks internally consistent.

Dimension selection means resisting the urge to fix every possible kind of data problem you find. Out of the nine recognized data quality dimensions, accuracy, completeness, consistency, and the rest, your use case genuinely only needs two or three addressed to get unblocked. If your use case is bottlenecked by conflicting customer names, you need consistency and accuracy fixed. You do not need a full audit of timeliness or precision unless those are also demonstrably part of what is breaking your model’s output.

Scoping One Fix, Start to Finish

Take the retailer whose return-prediction model was struggling because customer records disagreed across three systems and product listings carried duplicate SKUs with conflicting prices. The diagnosis already confirmed this as quality-bottlenecked. Scoping it starts with the value-and-risk question: a wrong customer name is awkward but low-stakes, while a wrong price feeding into a return-prediction model risks the model justifying refunds based on figures that were never accurate to begin with. The price and SKU inconsistencies get priority. The customer-name variants can wait.

Next comes the data-expanse question. Product pricing at this retailer lives in a system shared across the catalog, e-commerce, and returns teams, centralized data, not something one team can correct alone. That single fact changes the shape of the fix: this is not a task one person finishes in an afternoon, it needs sign-off from whoever else depends on that pricing data staying stable while it gets corrected.

That leaves two dimensions worth actually working on, accuracy and consistency, not all nine. The scope, once written down, reads as something concrete: correct pricing and SKU records for the specific product lines feeding the returns model, coordinated with the catalog and e-commerce teams that also touch that data, timeline measured in weeks. Customer-name formatting stays out of scope entirely, it does not affect the model this fix exists to support.

That is what a properly scoped fix looks like once the frameworks have actually been applied to something real, rather than staying at the level of principle.

How to Know the Fix Is Actually Bounded, Not Creeping

Prioritizing by value and risk, sizing the fix by how widely the data is shared, and narrowing the work to two or three dimensions all point toward the same outcome, a fix that stays fast because it stayed small. Holding that shape once work is underway is its own separate discipline, since scope drift is quiet, it rarely announces itself as a decision, and instead shows up as a series of small, reasonable-sounding additions that each make sense on their own and add up to a different project than the one you started.

The Use Case Still Has a Name

You can still name the specific use case the fix serves, without needing to reference other initiatives to justify the work. The moment the justification shifts from “this fix supports X” to “this fix supports X and also helps with Y and Z,” the scope has already started moving.

The Records Match the Mapping

The records you are correcting are the ones your value-and-risk mapping actually flagged, not every record that happens to look messy to you along the way. Fixing an unrelated inconsistency just because it is visible while you are already in the data is scope creep, even when it feels efficient in the moment.

The Owners Have Not Multiplied

The people involved are still the ones who owned this data to begin with, not a growing list of stakeholders you are pulling in because the fix started touching their systems too. A widening circle of people needing to sign off is one of the clearest early signs that a bounded fix has stopped being bounded.

The moment any of those three starts slipping for you, your fix has stopped being the bounded project this piece describes and has started becoming the larger, organization-wide undertaking that deserves its own separate plan, its own budget, and its own timeline.

Key Takeaways

  • Setting a data quality effort’s scope too wide taxes resources without producing business benefit, a principle Gartner states directly in its own guidance.
  • Mapping your affected data by value and risk determines what actually needs fixing first, not every inconsistent field carries equal priority.
  • Whether your data is centralized, regional, or local to one team changes how large the fix needs to be and who needs to be involved.
  • A bounded fix stays scoped to your diagnosed use case. A fix that starts touching unrelated systems or unrelated teams has quietly become a different, larger project.

How to Tell If Your AI Problem Is Data Quality or Data Availability

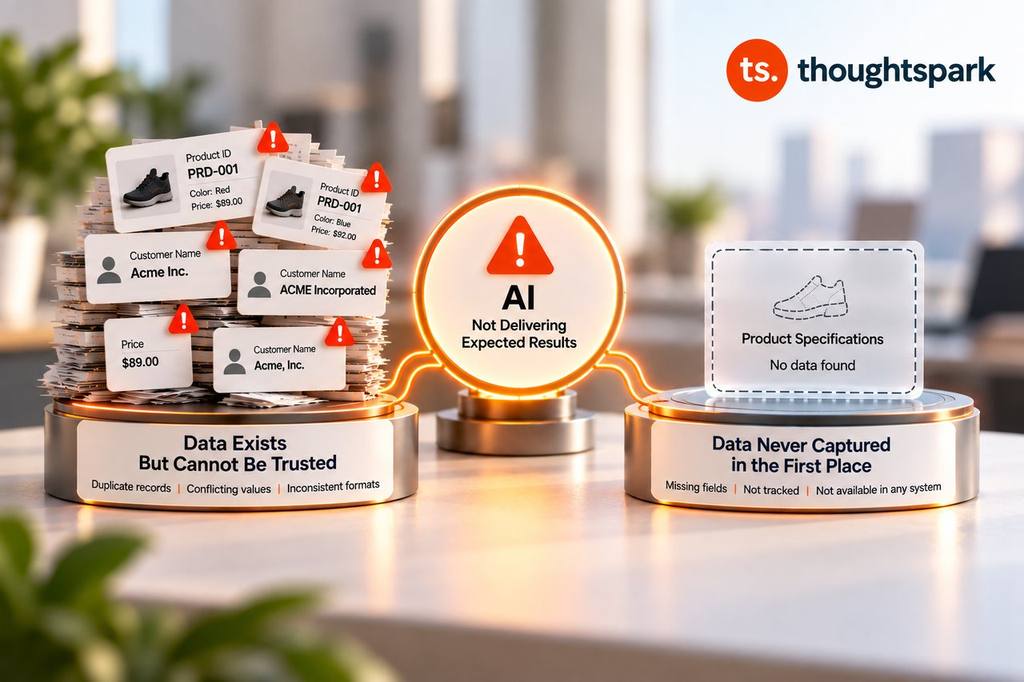
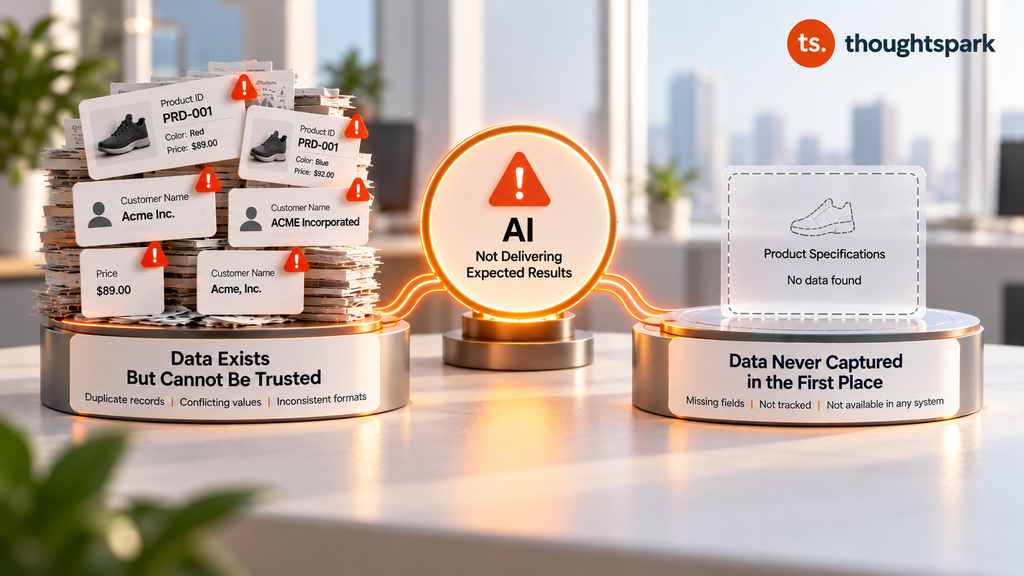
Two platforms comparing an AI diagnostic problem, one showing data that exists but cannot be trusted with duplicate and conflicting records, the other showing data that was never captured at all, with an AI warning symbol between them

Two organizations can have the exact same complaint, our AI initiative is not working, and be describing completely different problems. One has data that is wrong, the other has data that simply does not exist yet, and treating those as the same problem is why so many AI budgets get spent solving nothing.

The distinction matters because the fix is different in each case, and most teams never actually check which one they have before reaching for a solution. They assume, usually based on instinct or whichever problem they dealt with last time, and spend weeks or months acting on a guess.

There are six questions that get you there, and answering them honestly about your own initiative is usually enough to know which problem you are actually solving before you spend another dollar assuming.

In Brief

  • A data quality problem means the data exists but cannot be trusted. A data availability problem means the data was never captured in the first place. The fix for each is different.
  • Six direct questions determine which one applies to a specific AI initiative, based on what is actually happening in the organization’s own systems today.
  • Quality problems and availability problems produce different symptoms in production, inconsistent outputs versus initiatives that succeed in testing and fail once they go live.
  • The diagnosis takes under an hour and determines which of two entirely different next steps is the right one.

The Diagnosis Most Teams Skip Before Blaming the Model

Only 7% of organizations say their data is completely ready for AI, and 27% say it is not ready at all, a gap Harvard Business Review Analytic Services documented in a 2026 study conducted with Cloudera, surveying more than 230 data decision-makers. Seventy-three percent describe preparing data for AI as genuinely difficult.

Those numbers hide something the survey itself was not built to capture, that “not ready” describes two entirely different situations, and a team can spend a quarter cleaning up records that were never the actual problem, or spend that same quarter waiting on a data initiative when the real gap was somewhere else entirely. From the outside, these two mistakes look identical, and both come from skipping the same step, a real diagnosis before a real fix.

Two Kinds of Data Problems, Briefly

This distinction exists because most organizations skip a scoping step before either problem ever gets diagnosed, a precondition failure that plays out the same way across most AI initiatives, and the short version of the split is enough to work with here. A quality-bottlenecked problem means the data exists but cannot be trusted, duplicated records, conflicting values, inconsistent formats across systems. An availability-bottlenecked problem means the data a specific AI use case needs was never captured or structured in the first place, simply because nobody needed that information until now.

Treating these as degrees of the same problem, rather than as two separate ones, is what makes the mistake expensive, since the fix, the timeline, and the resourcing required are different for each.

The Diagnostic Questions That Separate the Two

Run your AI initiative against these six questions and answer plainly, based on what is actually happening in your systems today. Each question is designed to isolate one signal, and it is the overall pattern across all six that points toward the actual bottleneck.

Does the data your use case needs already exist somewhere in your systems today, in some form?

This question works as the starting fork, since answering yes puts you in quality territory, evaluating data that exists but needs to be trusted, and answering no shifts the entire conversation to availability territory, whether that data was ever tracked in the first place. Be precise here, “exists in some form” means a real system of record, not a spreadsheet someone built once for a different purpose.

If it exists, do different systems or records disagree with each other about the same fact?


Three systems giving three different addresses for the same customer is a clear quality signal, and not a formatting inconvenience. It means there is no single trustworthy version of that fact anywhere in the organization, and any AI model trained on it will learn whichever version appears most often, regardless of which one is actually correct.

If it exists and agrees, has anyone actually verified it is current and accurate, or is that assumed?

Systems agreeing with each other is no guarantee they are correct, since multiple systems can consistently share the same outdated or wrong value, especially when one system was the original source and the others simply copied from it years ago without anyone checking since. This question catches quality problems that consistency alone would hide.

If the data does not exist yet, is that because nobody has ever needed to track it, or because it was tracked once and lost?

If the data was simply never tracked, that is a build problem, new capture has to be designed from scratch. If it existed once and disappeared, through a deprecated system or an integration that quietly stopped working, that is closer to a recovery and quality problem, worth investigating before assuming a full rebuild is necessary.

Would fixing existing records solve your problem, or would you still be missing something afterward?

This question works as an honesty check on the earlier answers, since it is possible to describe something that sounds like quality trouble when the real gap is actually availability. If a team could clean every existing record perfectly and the use case would still lack a piece of information it needs, that missing piece is an availability problem no amount of cleanup will touch.

Could a data team start cleaning tomorrow and make real progress, or would they hit a wall where the information simply is not there to clean?

This question serves as the practical test. A quality problem is workable immediately, since there is something to correct. An availability problem hits a hard wall almost right away, because there is nothing yet to act on. A team that reports being stuck within days of starting is usually describing an availability problem, not a quality one.

A pattern of answers across questions 2, 3, and 5 pointing toward inconsistency and conflict signals a quality-bottlenecked problem. A pattern across questions 1, 4, and 6 pointing toward genuine absence rather than inconsistency signals an availability-bottlenecked problem.

What a Quality-Bottlenecked Answer Looks Like

A mid-sized retailer wants AI to flag which products are likely to be returned before they ship. The company has years of return data, along with three systems that each record customer addresses differently, a product catalog with duplicate SKUs carrying different attributes, and a returns database that has never been reconciled against the original order system.

Running the six questions: the data exists in the point-of-sale, catalog, and returns systems (yes to question one). Those systems disagree with each other constantly, the same customer, the same product, three different values depending on which system is pulled (yes to question two). Nobody has verified which version is correct in years, each system has simply been trusted on its own terms (yes to question three).

Nothing here suggests information was ever lost, the raw signal exists, it is just contradictory (this points away from question four’s concern). Cleaning and reconciling the records would plausibly resolve the inconsistency and give the model something trustworthy to learn from (yes to question five). A data team could start reconciling these systems immediately, there is real, existing work to do starting tomorrow (yes to question six).

Every signal here points toward a quality-bottlenecked problem, and the fix is a targeted reconciliation project scoped to this specific use case, smaller and faster than a new AI capability build or a company-wide governance overhaul.

What an Availability-Bottlenecked Answer Looks Like

A logistics company wants AI to predict which shipments are at risk of customs delays before they happen. The company has clean, trustworthy data on shipment volumes, routes, and delivery times going back years. It has never once recorded which customs documentation was submitted with which shipment, because until this initiative, nobody needed that information for anything.

Working through the same six questions: the specific data this use case needs, documentation submitted per shipment, does not exist anywhere in the company’s systems (no to question one). Because it does not exist, there is nothing to compare for disagreement, and nothing to verify for currency or accuracy either, since there is no record at all (questions two and three do not apply). Nobody ever needed to track this before, the field was never tracked, not lost, which confirms question four’s answer.

Cleaning the existing shipment data, however thoroughly, would not surface documentation that was never captured in the first place (no to question five). A data team assigned to this would hit a wall almost immediately, there is genuinely nothing to clean until new capture exists (this confirms question six).

The pattern here points to an availability-bottlenecked problem, and the fix is building new data capture, integrating with whatever system tracks customs documentation and connecting it to the shipment record, on the same timeline as the AI build instead of a strict sequence.

Why Each Bottleneck Produces the Symptoms It Does

A model trained on inconsistent data tends to perform well in one test and poorly in the next, because it is learning from a signal that disagrees with itself. The signal is present, just corrupted, so the model produces an answer, just not a reliable one. That inconsistency is the fingerprint of a quality-bottlenecked problem.

Availability leaves a different fingerprint. An initiative built on missing data either cannot get off the ground at all, or performs surprisingly well in testing and falls apart the moment it reaches production, because testing environments are often built on hand-prepared sample data that quietly fills a gap the real environment does not have. The model was never actually learning the missing signal, since that signal was never there to learn from.

Recognizing which fingerprint is showing up is often a faster shortcut than running all six questions from scratch, inconsistency pointing toward quality, and absence, especially absence that only becomes visible once a project reaches production, pointing toward availability.

What to Do Once You Know Which One You Have

A quality-bottlenecked diagnosis points to a specific, scoped next step, cleaning and reconciling the exact records this use case depends on, not a broad governance program that touches everything, and scoping that cleanup correctly is where most reconciliation projects actually go wrong (Cluster 2 link, pending publication).

An availability-bottlenecked diagnosis leads somewhere different entirely, building the specific new data capture this use case needs, run alongside the AI build rather than treated as something that has to finish first, and that parallel build carries its own sequencing decisions distinct from a data cleanup (Cluster 3 link, pending publication).

Either way, the diagnosis itself is the highest-leverage thirty minutes available before committing real budget to either path.

Key Takeaways

  • Data quality and data availability are two distinct problems that produce the same surface complaint, “our AI initiative is not working,” and require different fixes.
  • Only 7% of organizations report their data as completely ready for AI, per a 2026 Harvard Business Review Analytic Services and Cloudera study, and 27% report it as not ready at all.
  • Six direct questions, answered honestly, are usually enough to determine which bottleneck actually applies to a given AI initiative.
  • Quality-bottlenecked problems tend to leave inconsistent outputs. Availability-bottlenecked problems tend to succeed in testing and fail once they reach production.

What Organizations Get Wrong About Data Readiness Before AI

Businessman standing at a fork in the road between signposts reading Fix the Data and Build the AI, with a third unmarked path continuing straight ahead

Your CFO wants a straight answer to a simple-sounding question. Where does next quarter’s AI budget go, into cleaning up the data or into building the AI itself. You have maybe twenty minutes in that meeting, and the uncomfortable truth is that most people in the room have not actually agreed on what problem the AI is supposed to solve in the first place.

That gap gets papered over constantly. Someone says “fix the data first,” because it sounds responsible. Someone else says “just start building,” because leadership wants visible progress this quarter. Both answers can be defended in a slide, and both skip past the decision that actually determines whether this initiative works.

There is a real answer to which comes first, and most organizations are asking a different question entirely.

Why Data Readiness Is Not the First Question to Answer

That real question starts with an instinct almost everyone in the room already has. Ask ten data leaders whether to fix data readiness before starting an AI initiative, and most will say yes without hesitating. It is the responsible answer. It is also, in a meaningful number of cases, the wrong first move. Data readiness still matters. The problem is that jumping straight to it assumes a decision has already been made that usually has not.

RAND Corporation interviewed 65 experienced data scientists and machine learning engineers to understand why AI projects fail. Their finding cuts against the instinct in that CFO meeting. Eighty-four percent of interviewees named leadership-driven failure as the primary reason projects collapse, ahead of data quality itself. Business leaders and technical teams frequently disagree, sometimes without realizing it, about what problem the AI is actually meant to solve or how success will be measured.

That is a scoping problem, sitting upstream of the data-first-or-AI-first debate entirely. Skip it, and the sequencing decision you make next stops mattering, because you end up optimizing the wrong thing regardless of which path you pick.

What an Unscoped AI Problem Actually Looks Like

That wrong optimization has a shape to it, and it rarely announces itself. Leadership asks for a model that predicts customer churn. The technical team builds one, optimized for prediction accuracy. Three months later, leadership asks why churn has not improved, because what they actually needed was a model that identified which at-risk customers were worth the cost of retaining, a narrower and more useful target than simply predicting who was likely to leave.

Both sides did their jobs, each one correctly by their own definition. The project failed because the target metric and the business objective were never the same thing, and nobody caught the mismatch until the work was already done.

A simple test cuts through this before a single dollar gets spent on data or infrastructure. Can leadership and the technical lead each independently write down, in one sentence, what business outcome this AI initiative is meant to change. That alignment has to happen before the sequencing conversation starts.

Two Different Data Problems Once the Use Case Is Scoped

Once leadership and the technical team agree on what problem the AI is solving, the real sequencing question finally becomes answerable, and it is narrower than most people expect. It comes down to which of two situations you are actually in.

In the first, the data your use case needs already exists somewhere in the organization, but it cannot be trusted. It is inconsistent across systems, duplicated, ungoverned, or simply wrong in ways nobody has caught yet.

In the second, the data does not exist yet in usable form. The specific use case is simply new, and the organization has never needed to capture, structure, or retain that information before now.

These are two different problems, each calling for its own first move.

When Data Exists But Cannot Be Trusted

This is the quality-bottlenecked path, and it is the one most content on data readiness already addresses, for good reason. Picture a customer record that shows three different names for the same account, a product catalog with duplicate entries carrying different prices, or a sales figure that changes depending on which system you pull it from.

RAND’s interviews found this pattern repeatedly. Organizations believe they have good data because they get weekly reports, without realizing that the data behind those reports was never built to support a new purpose.

When this is the actual bottleneck, fixing the data first is the correct sequence. The reason has little to do with feeling responsible. Building AI on top of untrustworthy data produces a faster path to a model nobody trusts, and that is a more expensive failure than a delayed start.

When AI Needs Data That Does Not Exist Yet

The availability-bottlenecked path looks different, and it gets far less attention in most data readiness conversations, which is part of why organizations mishandle it. Here, the data is simply incomplete. It does not exist yet, because the use case is asking a question the organization has never needed to answer before.

Picture a manufacturer launching a new product line and wanting AI to flag supplier risk before a shipment gets delayed. The company has years of clean, trustworthy sales data. It has never once tracked supplier lead-time variability at the granularity this use case needs, because nobody needed that number before. Cleaning existing records will not surface a number that was never captured, so the only real fix is building the data collection itself.

This is a real and growing constraint, and a significant one. Stanford HAI’s 2026 AI Index flags a broader version of this same problem at industry scale, noting genuine concern among researchers that the supply of high-quality training data itself may be approaching structural limits within the next several years. Synthetic data has not proven a full substitute. If data availability is becoming a binding constraint even at the scale of the entire AI industry, it deserves equal weight to quality inside a single organization, as a different problem in its own right.

When this is the actual bottleneck, spending months on a data governance program before touching the AI initiative solves a problem you do not have. The right move is building the specific data capture and structure the use case needs, alongside building the AI capability itself, on the same timeline instead of a strict sequence.

The Real Cost of Sequencing Data Readiness and AI Wrong

Whichever path actually applies, guessing wrong in either direction carries a real cost, and it shows up differently depending on which default an organization reaches for. Organizations that default to “clean everything first” often spend on a broad governance initiative when the actual use case only needed a narrow, targeted fix, delaying value for months over a problem that was smaller than assumed.

Organizations that default to “build now, fix data later” run into the opposite cost. They discover the trust problem only after the model is in production, when a bad prediction has already reached a customer or a decision, and the fix now requires unwinding both the data and the deployed system at once.

A third pattern is just as common, and often the most expensive of all. Organizations split the budget, funding a partial data cleanup and a partial AI build at the same time, without ever diagnosing which one the use case actually needed.

Both efforts end up underfunded, and neither one finishes. The AI initiative stalls waiting on data that was never fully fixed, and the data initiative loses priority the moment the AI timeline slips, leaving the organization with the appearance of progress on two fronts and real progress on neither.

All three defaults carry real risk. Diagnosing which path actually applies costs far less than guessing wrong in any of them.

How to Know Which Path Applies to Your Organization

The scoping check comes first. Confirm that leadership and the technical team can each state the target business outcome in the same terms, and resolve any gap in that alignment before anything else.

Once scoped, the diagnostic question is direct. Does the data your use case needs already exist somewhere, just inconsistent or untrustworthy, or does it not exist yet in usable form at all. That single distinction determines whether the right next move is a data quality initiative or a parallel build.

This is the exact question a Data & AI Strategy engagement is built to answer, replacing the guesswork with a clear sequencing plan.

Key Takeaways

  • RAND’s interviews with 65 experienced AI practitioners found leadership-driven misalignment was the most cited primary cause of AI project failure, named by 84% of interviewees, ahead of data quality itself.
  • Confirming what problem the AI use case solves, in terms both leadership and the technical team agree on, has to happen before any sequencing decision is meaningful.
  • Once scoped, sequencing splits into two distinct paths: fixing data that exists but is not trustworthy, or building toward data that does not exist yet for the specific use case.
  • Stanford HAI’s 2026 AI Index confirms data availability is a serious, industry-recognized constraint carrying equal weight to quality.
  • Splitting the budget between partial data cleanup and a partial AI build, without diagnosing which one the use case actually needs, is common in practice and often costs more than committing to either path deliberately.