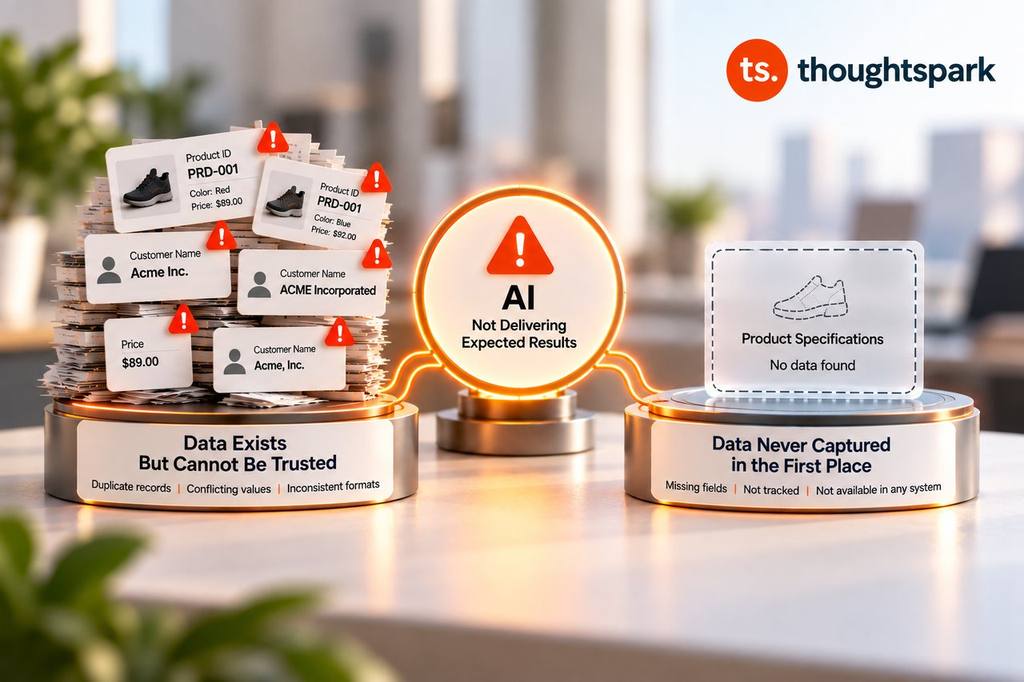
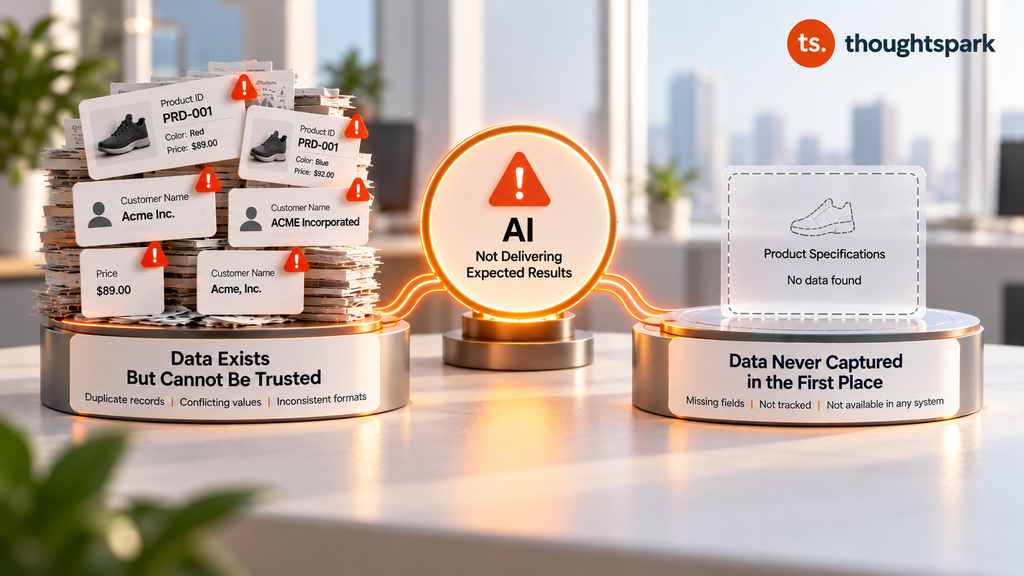
Two organizations can have the exact same complaint, our AI initiative is not working, and be describing completely different problems. One has data that is wrong, the other has data that simply does not exist yet, and treating those as the same problem is why so many AI budgets get spent solving nothing.
The distinction matters because the fix is different in each case, and most teams never actually check which one they have before reaching for a solution. They assume, usually based on instinct or whichever problem they dealt with last time, and spend weeks or months acting on a guess.
There are six questions that get you there, and answering them honestly about your own initiative is usually enough to know which problem you are actually solving before you spend another dollar assuming.
In Brief
- A data quality problem means the data exists but cannot be trusted. A data availability problem means the data was never captured in the first place. The fix for each is different.
- Six direct questions determine which one applies to a specific AI initiative, based on what is actually happening in the organization's own systems today.
- Quality problems and availability problems produce different symptoms in production, inconsistent outputs versus initiatives that succeed in testing and fail once they go live.
- The diagnosis takes under an hour and determines which of two entirely different next steps is the right one.
Table of Contents
The Diagnosis Most Teams Skip Before Blaming the Model
Only 7% of organizations say their data is completely ready for AI, and 27% say it is not ready at all, a gap Harvard Business Review Analytic Services documented in a 2026 study conducted with Cloudera, surveying more than 230 data decision-makers. Seventy-three percent describe preparing data for AI as genuinely difficult.
Those numbers hide something the survey itself was not built to capture, that "not ready" describes two entirely different situations, and a team can spend a quarter cleaning up records that were never the actual problem, or spend that same quarter waiting on a data initiative when the real gap was somewhere else entirely. From the outside, these two mistakes look identical, and both come from skipping the same step, a real diagnosis before a real fix.
Two Kinds of Data Problems, Briefly
This distinction exists because most organizations skip a scoping step before either problem ever gets diagnosed, a precondition failure that plays out the same way across most AI initiatives, and the short version of the split is enough to work with here. A quality-bottlenecked problem means the data exists but cannot be trusted, duplicated records, conflicting values, inconsistent formats across systems. An availability-bottlenecked problem means the data a specific AI use case needs was never captured or structured in the first place, simply because nobody needed that information until now.
Treating these as degrees of the same problem, rather than as two separate ones, is what makes the mistake expensive, since the fix, the timeline, and the resourcing required are different for each.
The Diagnostic Questions That Separate the Two
Run your AI initiative against these six questions and answer plainly, based on what is actually happening in your systems today. Each question is designed to isolate one signal, and it is the overall pattern across all six that points toward the actual bottleneck.
Does the data your use case needs already exist somewhere in your systems today, in some form?
This question works as the starting fork, since answering yes puts you in quality territory, evaluating data that exists but needs to be trusted, and answering no shifts the entire conversation to availability territory, whether that data was ever tracked in the first place. Be precise here, "exists in some form" means a real system of record, not a spreadsheet someone built once for a different purpose.
If it exists, do different systems or records disagree with each other about the same fact?
Three systems giving three different addresses for the same customer is a clear quality signal, and not a formatting inconvenience. It means there is no single trustworthy version of that fact anywhere in the organization, and any AI model trained on it will learn whichever version appears most often, regardless of which one is actually correct.
If it exists and agrees, has anyone actually verified it is current and accurate, or is that assumed?
Systems agreeing with each other is no guarantee they are correct, since multiple systems can consistently share the same outdated or wrong value, especially when one system was the original source and the others simply copied from it years ago without anyone checking since. This question catches quality problems that consistency alone would hide.
If the data does not exist yet, is that because nobody has ever needed to track it, or because it was tracked once and lost?
If the data was simply never tracked, that is a build problem, new capture has to be designed from scratch. If it existed once and disappeared, through a deprecated system or an integration that quietly stopped working, that is closer to a recovery and quality problem, worth investigating before assuming a full rebuild is necessary.
Would fixing existing records solve your problem, or would you still be missing something afterward?
This question works as an honesty check on the earlier answers, since it is possible to describe something that sounds like quality trouble when the real gap is actually availability. If a team could clean every existing record perfectly and the use case would still lack a piece of information it needs, that missing piece is an availability problem no amount of cleanup will touch.
Could a data team start cleaning tomorrow and make real progress, or would they hit a wall where the information simply is not there to clean?
This question serves as the practical test. A quality problem is workable immediately, since there is something to correct. An availability problem hits a hard wall almost right away, because there is nothing yet to act on. A team that reports being stuck within days of starting is usually describing an availability problem, not a quality one.
A pattern of answers across questions 2, 3, and 5 pointing toward inconsistency and conflict signals a quality-bottlenecked problem. A pattern across questions 1, 4, and 6 pointing toward genuine absence rather than inconsistency signals an availability-bottlenecked problem.
What a Quality-Bottlenecked Answer Looks Like
A mid-sized retailer wants AI to flag which products are likely to be returned before they ship. The company has years of return data, along with three systems that each record customer addresses differently, a product catalog with duplicate SKUs carrying different attributes, and a returns database that has never been reconciled against the original order system.
Running the six questions: the data exists in the point-of-sale, catalog, and returns systems (yes to question one). Those systems disagree with each other constantly, the same customer, the same product, three different values depending on which system is pulled (yes to question two). Nobody has verified which version is correct in years, each system has simply been trusted on its own terms (yes to question three).
Nothing here suggests information was ever lost, the raw signal exists, it is just contradictory (this points away from question four's concern). Cleaning and reconciling the records would plausibly resolve the inconsistency and give the model something trustworthy to learn from (yes to question five). A data team could start reconciling these systems immediately, there is real, existing work to do starting tomorrow (yes to question six).
Every signal here points toward a quality-bottlenecked problem, and the fix is a targeted reconciliation project scoped to this specific use case, smaller and faster than a new AI capability build or a company-wide governance overhaul.
What an Availability-Bottlenecked Answer Looks Like
A logistics company wants AI to predict which shipments are at risk of customs delays before they happen. The company has clean, trustworthy data on shipment volumes, routes, and delivery times going back years. It has never once recorded which customs documentation was submitted with which shipment, because until this initiative, nobody needed that information for anything.
Working through the same six questions: the specific data this use case needs, documentation submitted per shipment, does not exist anywhere in the company's systems (no to question one). Because it does not exist, there is nothing to compare for disagreement, and nothing to verify for currency or accuracy either, since there is no record at all (questions two and three do not apply). Nobody ever needed to track this before, the field was never tracked, not lost, which confirms question four's answer.
Cleaning the existing shipment data, however thoroughly, would not surface documentation that was never captured in the first place (no to question five). A data team assigned to this would hit a wall almost immediately, there is genuinely nothing to clean until new capture exists (this confirms question six).
The pattern here points to an availability-bottlenecked problem, and the fix is building new data capture, integrating with whatever system tracks customs documentation and connecting it to the shipment record, on the same timeline as the AI build instead of a strict sequence.
Why Each Bottleneck Produces the Symptoms It Does
A model trained on inconsistent data tends to perform well in one test and poorly in the next, because it is learning from a signal that disagrees with itself. The signal is present, just corrupted, so the model produces an answer, just not a reliable one. That inconsistency is the fingerprint of a quality-bottlenecked problem.
Availability leaves a different fingerprint. An initiative built on missing data either cannot get off the ground at all, or performs surprisingly well in testing and falls apart the moment it reaches production, because testing environments are often built on hand-prepared sample data that quietly fills a gap the real environment does not have. The model was never actually learning the missing signal, since that signal was never there to learn from.
Recognizing which fingerprint is showing up is often a faster shortcut than running all six questions from scratch, inconsistency pointing toward quality, and absence, especially absence that only becomes visible once a project reaches production, pointing toward availability.
What to Do Once You Know Which One You Have
A quality-bottlenecked diagnosis points to a specific, scoped next step, cleaning and reconciling the exact records this use case depends on, not a broad governance program that touches everything, and scoping that cleanup correctly is where most reconciliation projects actually go wrong (Cluster 2 link, pending publication).
An availability-bottlenecked diagnosis leads somewhere different entirely, building the specific new data capture this use case needs, run alongside the AI build rather than treated as something that has to finish first, and that parallel build carries its own sequencing decisions distinct from a data cleanup (Cluster 3 link, pending publication).
Either way, the diagnosis itself is the highest-leverage thirty minutes available before committing real budget to either path.
Key Takeaways
- Data quality and data availability are two distinct problems that produce the same surface complaint, "our AI initiative is not working," and require different fixes.
- Only 7% of organizations report their data as completely ready for AI, per a 2026 Harvard Business Review Analytic Services and Cloudera study, and 27% report it as not ready at all.
- Six direct questions, answered honestly, are usually enough to determine which bottleneck actually applies to a given AI initiative.
- Quality-bottlenecked problems tend to leave inconsistent outputs. Availability-bottlenecked problems tend to succeed in testing and fail once they reach production.