If the data your AI initiative depends on has never been captured, how do you move the initiative forward? One answer is to wait until the data exists, which stalls the initiative for as long as that takes. The other is to build against a hand-prepared sample in place of the missing data, which produces a model that looks fine in testing and struggles on live records.
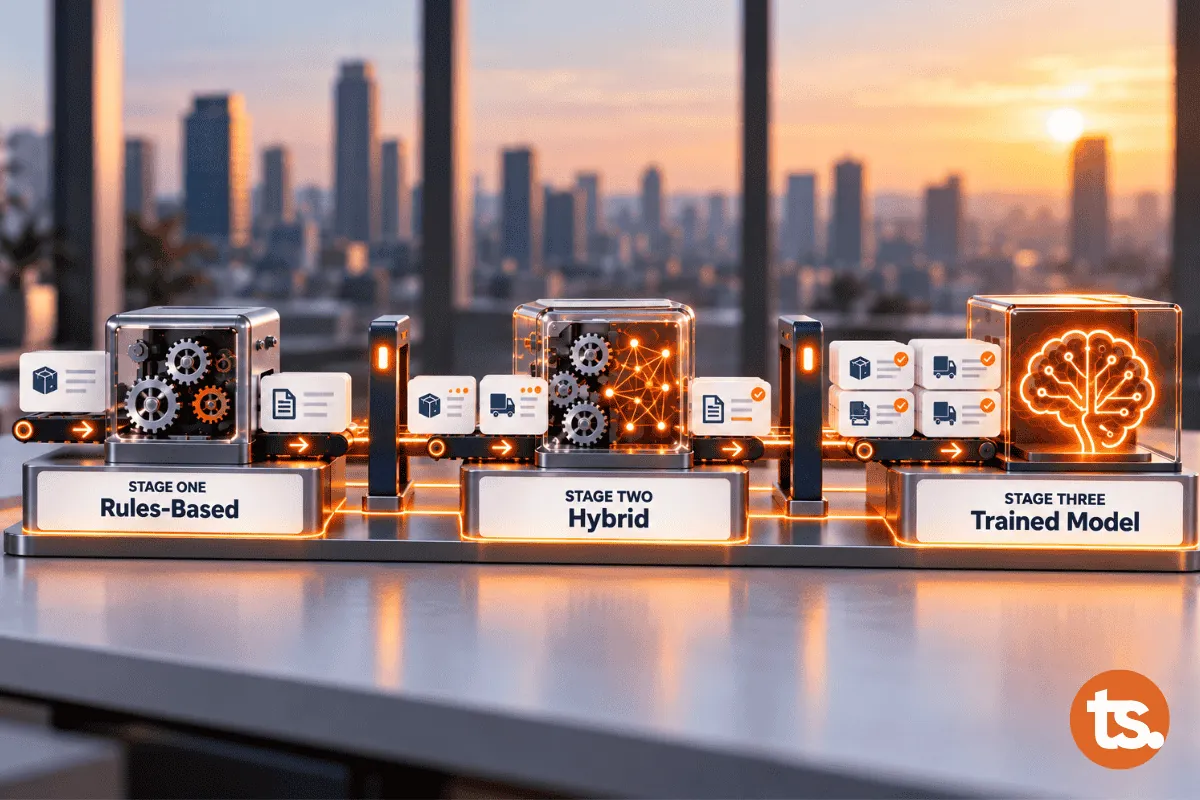
A staged build is a third option, and it works in three steps:
- Start capturing the missing data now.
- Launch a simple rules-based version using the data the organization already has. It follows fixed rules, such as flagging any route that has had delays before, so it does not need the new data.
- Launch an AI model trained on the new data once enough of it has been collected, then widen what the model covers as more data arrives.
The team agrees in advance what counts as enough, as a set of conditions that together form a gate.
Staging is worthwhile because this kind of data cannot be collected faster than the business produces it. A supplier's lead-time history, a season of returns, or a quarter of customs outcomes each grows one record at a time, and no budget speeds that up.
This is why capture should start as early as possible: every day capture waits is a day of history the model never gets to learn from.
In Brief
- Staging applies when the needed data is not being captured today. Data that existed once and has since disappeared is a recovery job.
- The length of the wait depends on how often the outcome you want to predict occurs.
- Capture starts with a one-page specification that lists each field, its source, its trigger, its format, and a coverage target.
- Staging fits predictive use cases that learn from history. A generative use case needs the gap captured and does not need a history of outcomes.
Why Data You Are Not Yet Capturing Takes Time to Accumulate
Once capture is running, the data grows at a pace with two inputs. The first is how often the relevant events happen: shipments cleared, returns processed, deliveries received. The second is the share of those events the capture actually records. For illustration, a business that clears a thousand shipments a month with capture covering half of them gains five hundred usable records a month, and coverage is the input the team can raise.
Google's own engineering guidance on machine learning advises starting early for this reason: track as much as possible in the current system before the machine learning system is formalized, since historical data on anything that might matter later is better collected now.
That makes the missing data a quantity that grows at a rate the team can estimate, and a quantity can be planned around in a way a yes-or-no condition cannot.
When Staging an AI Build Is the Right Approach
That growing-quantity view applies to one specific kind of gap: the data the use case needs is not recorded anywhere today, usually because nobody needed it until the AI initiative came along.
Data that exists but conflicts across systems is a quality problem with its own fix, and data that existed once and has since disappeared is a recovery job. Six diagnostic questions tell these cases apart, and a "never tracked" answer is what points here.
Staging fits predictive use cases, where a model learns from history to forecast a delay or score a risk, because that history has to accumulate. A generative use that reads attributes at the moment it answers needs the missing information captured for the records it reads. It does not need a history of past outcomes to learn from.
Take a logistics company that wants a model to predict which shipments will face customs delays. It holds years of clean data on volumes, routes, and delivery times, and it has never recorded which customs documentation goes with which shipment.
Working Out How Much Data the Use Case Needs
For that company, and for any use case in this position, the first task is defining what enough data looks like, since every later decision depends on it: what to record, when a stage is ready, and what to tell the business.
Which Attributes the Model Needs
Start from the decision the model will make and list what a person making that decision by hand would look at. Each item that is not already recorded becomes an attribute to capture.
In the logistics example, the model needs to know which documents accompany a shipment and when they were submitted. Suppose the outcome it predicts, whether a shipment faced a customs delay, can be read from delivery records the company already holds. That leaves the documentation as the missing piece.
How Much History the Use Case Needs
History length depends on how much the pattern changes across the year. If shipments behave differently in a peak season, a model trained only on quiet months has never seen the pattern it will be asked to handle, so the plan has to include a stretch of history that covers it. Ask the business which cycles matter for this use case, and treat the answer as a minimum.
How Many Examples of the Rarest Outcome You Need
What limits the model is the count of the outcome you want to predict. Each record whose outcome is known, such as a shipment marked delayed or on time, is a labeled example, and most records show the normal case. Only the rare outcomes show the model what it needs to learn.
MIT Sloan Management Review describes the same limit in its discussion of scarce data: when an outcome is uncommon, such as a rare cardiac event or defects from a factory that has produced few of them, labeled examples are few and cannot be increased on demand.
Your data science team can estimate how many examples of the rarest outcome the model needs. Divide that estimate by the number of usable examples of that outcome you expect to capture each month, and the result is a first read of how many months the wait runs, which you revise as real capture rates come in.
What Can Shorten the Wait and What Cannot
Data-efficient techniques, such as starting from a pretrained model (one already trained on a large body of similar data), can reduce how many labeled examples a model needs. The MIT Sloan Management Review article describes cases where a fraction of the usual number is enough. These techniques address a shortage of labels.
A field the organization never recorded is a missing input, and no technique supplies an input nobody wrote down. The article does not discuss inputs that were never recorded, so this limit is our own reading. It has a planning consequence: a pretrained model may shorten how long the outcomes take to accumulate, and capture still has to start on the same day.
Start Data Capture Before the AI Build Starts
Capture goes first because it sets the schedule, and a simple capture that starts now gives the eventual model more history than a thorough one that starts a quarter later. The team's first deliverable is a capture specification, one page that says what gets recorded and how you will know it is working:
- Field: each attribute the use case needs, taken from the attribute list above.
- Source: the system, or the person at the moment of the work, where the value is first known.
- Trigger: the event that causes the record to be written.
- Format: a controlled set of values, so records can be compared months later.
- Coverage target: the share of relevant events that must carry the field before it counts as usable.
Two design choices decide whether the captured data is usable:
- Record the cases that seem easy to skip. Google's guide describes logging only what a user saw, which leaves no examples of what was not seen. The same trap applies when documentation is recorded for delayed shipments and skipped for the ones that cleared.
- Record at the point of the work. A value entered from memory a week later can carry errors the model then learns from.
Coverage needs watching once capture is running, since it can fall without any alarm. Google's guide notes that a feature populated in most examples can drop sharply after an implementation change and go unnoticed, so a coverage figure reported on a set schedule belongs on the same page as the specification.
Staging an AI Build From a Rules-Based Version to a Trained Model
With capture running, the build itself proceeds in three stages. Capture and the build run at the same time, as our data readiness and AI sequencing guide recommends, and the release is staged, so the model at full scope goes live last.
A Rules-Based or Human-Assisted First Version
The first stage is a rules-based or human-assisted version that uses only the data the organization already holds. In the logistics example, a simple rule flags shipments on routes with prior delays, and a person reviews each flag before anything happens. Google's guide is direct that machine learning requires data, and that a simple rule, or even human editing, can get a product out the door until that data exists.
This stage earns its place in three ways:
- It gives the business something usable early.
- It sets the baseline every later model has to beat.
- Each reviewed flag, together with what happens to that shipment afterward, adds a labeled example the model will later learn from.
The value of this stage depends on the review being genuine, since checkpoints that handle more items than a person can examine become a formality.
A Simple Model Sized to the Data
The second stage introduces a trained model once the gate in the next section is met. Google's guidance recommends a simple first model and a solid pipeline around it, and it links the complexity a model can support to how much data is available. A few carefully chosen attributes on a modest dataset are a sound start, and the rules-based version keeps running as the fallback and the baseline.
Wider Scope Once Coverage Holds
The third stage widens the scope as coverage holds: more attributes, more routes or product lines, and more automation of the decisions a person reviewed.
Where the model makes its errors, capture more examples from those areas first. The MIT Sloan Management Review article recommends this targeted approach, since errors tend to cluster in particular regions of the data. If the errors point to an attribute the model lacks, that attribute joins the capture specification, and each widening has to pass a gate again.
The Gates That Decide When to Move to the Next Stage
A gate is three conditions that must all hold. The same three apply before the trained model goes live and again before each widening.
Coverage, Volume, and a Test on Newer Records
- Coverage: the capture specification's target is met, and the figure has held there for a stretch you agree in advance.
- Volume: the count of the rarest outcome reaches the estimate from the earlier section, revised with real capture rates.
- A test on newer records: a model trained on records up to a chosen date is tested on records captured after it, and it has to beat the rules-based baseline on those newer records. Google's guide recommends testing this way because it better reflects what happens in production. Testing only on hand-prepared samples can make a model look fine and then fail on live records.
What to Commit to on the Timeline
When the business asks for a date, the answer has two parts:
- Dates for what you control: the day capture starts and the day the rules-based first version goes live.
- Gates, with a forecast range, for what the data controls: build the range from the estimate of examples needed divided by the usable examples captured each month, and revise it monthly against actual capture.
Leadership gets firm dates for the parts within your control and a forecast that sharpens each month for the rest.
What Happens If a Gate Is Not Met
Sometimes a gate stays closed longer than the forecast. Three responses are available, and the right one depends on why:
- Stay at the current stage. The rules-based version keeps delivering as the data builds, and nothing has to be withdrawn.
- Widen the capture. If coverage is the problem, add sources or events to the specification. If volume is the problem, look for more places the outcome is recorded.
- Narrow the use case. Scope the model to the routes or segments where the data is already sufficient.
Occasionally the outcome is too rare for a trained model to reach the volume it needs in any useful time. In that case the rules-based version may be the finished product, and Google's guide says a team should choose the simple rule when it does better than the model on the metrics that matter.
A Worked Example of Staging a Customs Delay Model
Take the logistics company from earlier. The sequence starts with a definition of how much data is enough. The model needs the documents that accompany each shipment and when they were submitted, and suppose the delay outcome can be read from existing delivery records.
In this example customs delays are the uncommon case, so the count of delayed shipments sets the pace. The data science team estimates how many delayed shipments the model needs and divides by the number of usable delayed-shipment examples expected each month, which gives a forecast range for the second stage.
The capture specification then reads:
- Field: the customs documentation that accompanies each shipment.
- Source: the customs filing step.
- Trigger: submission of the filing.
- Format: a controlled list of document types.
- Coverage target: the share of shipments that must carry the field, set with the business.
It records documentation for shipments that clear without delay as well as for the delayed ones. The build then proceeds in three stages:
- Stage one goes live once capture is running. A rule flags shipments on routes with prior delays, using data the company already holds, and a reviewer examines each flag. The business gets usable flags, and each reviewed flag adds a labeled example once the shipment's outcome is known.
- Stage two opens when coverage holds at target, the count of delayed shipments reaches the estimate, and a model trained on shipments up to a chosen date beats the rule on shipments after it. A simple model then goes live for a limited set of routes, with the rule running beside it.
- Stage three adds more routes and attributes, with the same gate at each step, and the model's errors show where capture focuses next.
The message to leadership has three parts:
- Capture starts on one date.
- The rules-based version goes live on another date.
- Each later stage opens when its gate does, with a forecast that sharpens each month.
If delayed shipments turn out to be too rare for the second stage to open in a useful time, the rule stays in place and the company has a working process with a growing dataset behind it. That position is stronger than a model launched early on hand-prepared samples.
When the Foundation Has to Come First
Staging suits a narrow gap, one field from one source, like the customs documentation above. A gap that needs data integrated across many systems is a different project, and the foundation comes first. McKinsey's article on scaling AI in manufacturing describes a pharmaceutical site that first built three integrated data platforms connecting about a dozen IT systems and more than 150 sensors, and then built applications on that base.
Three signals suggest the foundation has to come first. These reflect practitioner judgment, and no published threshold backs them:
- Capturing the field means integrating several source systems.
- Several use cases depend on the same missing data, which makes it a platform need.
- The new records have no shared identifier that connects them to the records the organization already holds.
If none of these apply, the staged approach fits, and the first step is the capture specification.
Key Takeaways
- The trained model goes live when its gate is met: capture coverage at target, enough examples of the rarest outcome, and a win over the baseline on newer records.
- A rules-based first version delivers early value, sets the baseline, and produces the labeled examples a model later learns from.
- Testing on records captured after the training window catches what hand-prepared samples hide.
- Commit dates to what you control, such as the capture start and the first release, and commit gates with a forecast to what the data controls.
- A pretrained model may shorten the wait for outcomes, and capture still has to start on the same day.
- When the missing data requires integrating many systems, the foundation comes first.